
Show HN: Paper Radar – daily ArXiv triage, now runs on Claude Haiku too
Article URL: https://github.com/Eliot5566/JEV-Paper-Radar Comments URL: https://news.ycombinator.com/item?id=50462542 Points: 1 # Comments: 0
Search headlines, summaries and articles to connect the dots.
Article URL: https://github.com/Eliot5566/JEV-Paper-Radar Comments URL: https://news.ycombinator.com/item?id=50462542 Points: 1 # Comments: 0
The n8n 2.48.0 release addresses multiple bugs, including fixes for AI builder, compression node, core functionality, editor improvements, and RabbitMQ node issues. New features include enhanced assistant models, Microsoft Work IQ OAuth2 credential support, app bindings UI, migration report enhancements, and improved user experience elements like chat message unification and credential modal restrictions.
The n8n 3.2.0 release introduces several bug fixes addressing issues in AI Builder, core functionality, editor UI, and node-specific behaviors, including improved handling of JSON, XML, CSV, and YAML responses, enhanced security through expanded IP blocking, and better error reporting. New features include support for Microsoft Work IQ OAuth2 credentials, a new App bindings UI, and updated default Assistant models. The release also reverts some previous changes due to compatibility or stability concerns.
Zyphra released ZYFA, open-source FP8 and BF16 prefill attention kernels for AMD Instinct MI355X. On real model activations, its FP8 kernels run 1.16-1.76x faster than AMD’s AITER, with 62-78% lower error at head dimension 128. The post Zyphra ZYFA: FP8 FlashAttention for AMD MI355X, Up to 1.76x Faster appeared first on MarkTechPost.
Article URL: https://github.com/AlgoVesta/mcp Comments URL: https://news.ycombinator.com/item?id=50375559 Points: 1 # Comments: 0
Article URL: https://github.com/chirrop/chirrop-mcp Comments URL: https://news.ycombinator.com/item?id=50376897 Points: 2 # Comments: 0
Article URL: https://github.com/watscho/chat-gpt-telegram-bot Comments URL: https://news.ycombinator.com/item?id=50377737 Points: 1 # Comments: 0
Vercel Connect now enables webhook triggers for Resend, X, Twilio, Notion, and Telegram, automatically registering webhooks for Resend and Telegram while requiring manual setup for the others. It verifies requests, handles heartbeats, and forwards events to specified endpoints in Vercel projects, with support for monitoring via the Observability tab. This expands existing trigger support for Slack, Discord, Microsoft Teams, GitHub, and Linear.
MiniMax has open-sourced MCode Stack, an MIT-licensed repo of 17 SKILL.md skills and 5 checklists that its MiniMax Code team uses daily for code review, subagent splits, context budgets and long-running commands. The post MiniMax Open-Sources MCode Stack: 15 Agent Skills Its Coding Team Uses Daily appeared first on MarkTechPost.

FlashMap is a speculative decoding drafter from Polymathic AI, Princeton and USC ISI researchers. It drafts 16 tokens jointly in one pass and reaches up to 6.14x lossless speedup on Qwen3-8B. The post Polymathic AI and Princeton Researchers Release FlashMap, a Flow Map Drafter for 6.14x Faster LLM Decoding appeared first on MarkTechPost.

Google DeepMind released Genie 4 as a research preview. The real-time world model adds native audio, live dialogue and text steering, with Gemini 3.8 Flash planning events inside the simulation loop. The post Meet Google DeepMind’s Genie 4: Real-Time World Model With Native Audio appeared first on MarkTechPost.

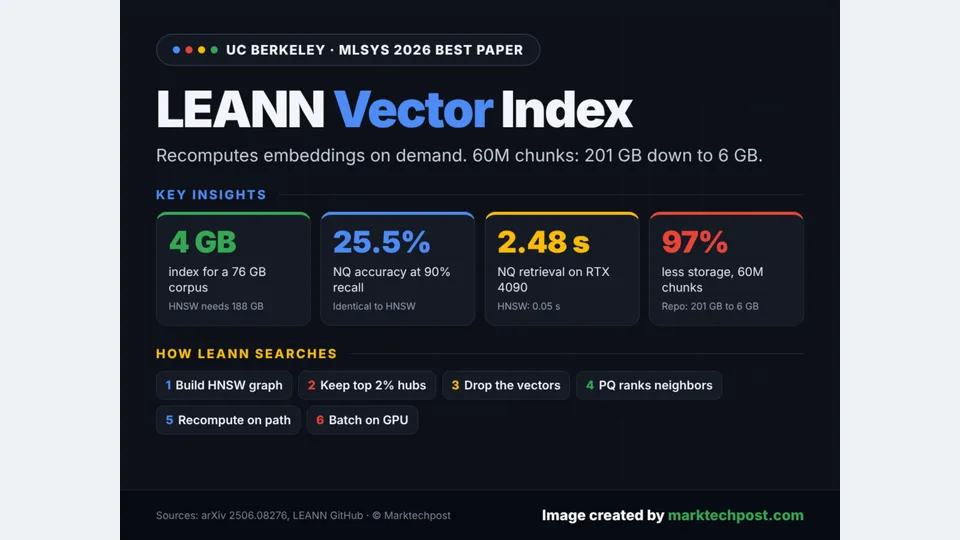
UC Berkeley’s LEANN vector index stores a pruned graph and recomputes embeddings at query time. It matches HNSW accuracy at 90% recall using 4 GB instead of 188 GB, at the cost of seconds-level search. The post Meet LEANN: An Open-Source Vector Index that Shrinks a 60M-Chunk RAG Index from 201 GB to 6 GB appeared first on MarkTechPost.
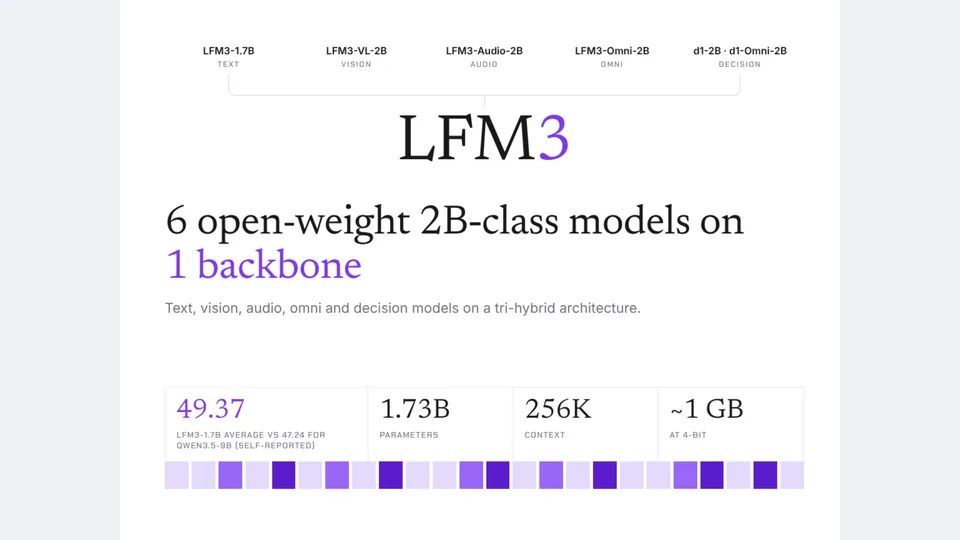
Liquid AI released LFM3, 6 open-weight 2B-class models for text, vision, audio, omni and decisions. LFM3-1.7B uses a tri-hybrid backbone, a 256K context window and fits in about 1 GB at 4-bit. The post Liquid AI Releases LFM3: 6 Open-Weight 2B-Class Multimodal Models appeared first on MarkTechPost.
Mirendil released Fern 0.1, its first model, pretrained from scratch with a 10M-token context window. It targets agentic AI R&D work, scores 100% on RULER single needle at 10M, but trails frontier models on agentic coding. The post Mirendil Launches Fern 0.1, Its First Model, With 10M-Token Context appeared first on MarkTechPost.

vLLM Semantic Router released d3-ultra, a 27B open-weight multimodal decision model. It reads text, images and video once, then returns probabilities for every answer, scoring 87.2 on the team’s SR-Text test. The post vLLM Semantic Router Releases d3-ultra: A 27B Open Multimodal Decision Model appeared first on MarkTechPost.

Baidu has released Unlimited OCR 2, an MIT-licensed 3B OCR model that parses hundred-page documents in one request. Its SR-SWA attention keeps per-step decoding cost nearly flat, scoring 77.1 on MarathonDocBench The post Baidu Open-Sources Unlimited OCR 2 for Hundred-Page Document Parsing appeared first on MarkTechPost.

OpenAI released GPT-6.1 Terra, a fast computer-use and vision model priced at $1/$5 per million tokens. It matches GPT-6 Astra’s medium-effort Agents’ Last Exam score at $0.29 per task versus $4.82. The post OpenAI Launches GPT-6.1 Terra, Halving GPT-6.1 Sol’s API Price for Agent Work appeared first on MarkTechPost.

Nanbeige LLM Lab released Nanbeige4.3-33B, a 33B dense Apache 2.0 model with 512K context. It reports 80.9 on Terminal-Bench 2.1 and will teach the upcoming Nanbeige4.3-3B. The post Nanbeige Releases Nanbeige4.3-33B, a 33B Open Agentic Coding Model appeared first on MarkTechPost.

Hugging Face released Carbon-X, an open 14.8B DNA language model built on Qwen3-14B. It reads raw DNA in chat, answers in English, and averages 66.7% across 5 DNA benchmarks under Apache 2.0. The post Hugging Face Releases Carbon-X, a 14B Open DNA Language Model that Brings DNA and Natural Language Together for the First Time appeared first on MarkTechPost.

Google DeepMind and GovTech Singapore have jointly launched a lightweight edge AI model based on the Gemma series, optimized for local execution on users’ devices. It can detect and issue real-time alerts for conversational scams without uploading any chat data to the cloud.