Measuring how AI agents handle everyday wet-lab science
OpenAI introduces BioBasicsBench, a 100-task benchmark measuring how well AI agents interpret raw experimental data and handle everyday wet-lab science.
Search headlines, summaries and articles to connect the dots.
OpenAI introduces BioBasicsBench, a 100-task benchmark measuring how well AI agents interpret raw experimental data and handle everyday wet-lab science.
arXiv:2611.07408v1 Announce Type: new Abstract: Panoptic Scene Graph generation (PSG) requires holistic yet fine-grained reasoning over complex relations among objects. However, current Multimodal Large Language Models (MLLMs) applied to PSG suffer from a perception bottleneck: they function as static observers limited by fixed-resolution views. As a result, models often overlook critical relations involving small or peripheral objects and struggle to differentiate ambiguous predicates in complex scenes. To address these limitations, we propose PSGAgent, an agentic framework that enhances visual perception for PSG through a think-act-observe loop. PSGAgent allows MLLMs to dynamically refine their visual perception using two tools: a Region Zoom-In Tool for local exploration of small or boundary relations and a Visual Highlight Tool for relation-focused segmentation that filters out irrelevant contextual noise. To optimize decision-making, we construct a two-stage training pipeline. First, we create a high-quality, error-aware Multimodal Chain-of-Thought (M-CoT) dataset that provides robust supervision for cold-start learning. Then, we design a novel hierarchical reward mechanism integrated with Group Sequence Policy Optimization (GSPO) to enable strategic and adaptive tool usage. Extensive experiments on the PSG benchmark show that PSGAgent achieves SOTA performance, demonstrating strong capability in both holistic and fine-grained scene understanding.
Chris Alexiuk has a simple rule about open source AI: If you believe in it, be loud about it. “We should be shouting about this technology from the rooftops,” said Alexiuk, a Toronto-based senior product research engineer in deep learning at NVIDIA who specializes in making open large language models (LLMs) practical for working developers. […]
arXiv:2611.07392v1 Announce Type: new Abstract: We present \textbf{WeLM-Image}, a unified image foundation model that integrates multimodal understanding into text-to-image generation, instruction-guided editing, and multi-reference synthesis. Designed for single-GPU deployment in WeChat's large-scale consumer applications, the model processes text, reference images, and target latents as one interleaved sequence. A Mixture-of-Transformers (MoT) backbone combines shared attention with independent understanding and generation parameters to limit optimization interference. Equipping each path with Mixture-of-Experts (MoE) modules provides sparse capacity, with 31.7B stored parameters and approximately 5.4B generation parameters activated per target latent token. A generation-oriented data engine combines a knowledge-grounded visual vocabulary with large-scale visual clustering to balance semantic coverage and editing tasks, while training-time evaluation guides iterative data refinement. Bilingual annotations and verified editing supervision support progressive training up to native 1.5K resolution. We optimize generation and editing separately with rubric- and checklist-based rewards, then consolidate the specialized policies through noise-aware on-policy distillation. In the reported overall comparisons, the 1536-resolution model ranks first among the evaluated open-source models on PRISM-Bench, Qwen-Image-Bench, and UnicBench. MeanFlow-based few-step distillation yields WeLM-Image-Turbo, which generates a $1024\times1024$ image in 4.98\,s on a single NVIDIA H20 GPU using eight guidance-free steps.
Phonon, a small text-to-speech model that runs entirely on the user's device without requiring internet access, has been released with support for English, French, German, Spanish, and Portuguese. Built on the Pocket TTS lineage using flow matching, Phonon achieves high-quality audio in compact sizes (65 MB and 75 MB), with the 31m version licensed under Apache 2.0 for commercial use. It excels in intelligibility and speed, ranking first in German and Spanish on Hugging Face's Open TTS Leaderboard and leading in CPU streaming benchmarks. The model supports voice cloning, custom voices via Gradium Studio, and integrates with Hugging Face Transformers. It is available in multiple formats and backends, including WebAssembly, GPU, and NPU, enabling deployment across phones, laptops, single-board computers, and browsers. Over 200,000 downloads were recorded in its first two weeks, with active developer adoption through tools like ExecuTorch, Micdrop, and Spaces. Future developments include support for additional languages, smaller models, and custom vocabulary fine-tuning.
arXiv:2611.05451v1 Announce Type: new Abstract: While discrete tokenization in Unified Multimodal Models (UMMs) establishes strong semantic reasoning, it introduces a strict quantization bottleneck that degrades fine-grained visual details, often resulting in structurally accurate but artifact-heavy images. We introduce FlowShift, a parameter-efficient post-training framework that bypasses this bottleneck by converting pre-trained discrete UMMs into continuous rectified-flow generators. Instead of discarding the backbone's semantic priors, FlowShift replaces discrete visual interfaces with continuous latent projections and applies LoRA to the attention layers. To efficiently boost visual quality without semantic drift, we propose Dual-Objective Velocity Vector Distillation (DOVD), which aligns the model with a high-fidelity continuous teacher and ground-truth continuous trajectories. This approach drastically improves perceptual quality while preserving prompt adherence and reasoning. When applied to leading discrete UMMs, FlowShift significantly improves COCO-30K FID and aesthetic scores, while retaining over 99.5% of multimodal understanding capabilities. Ablations confirm DOVD drives generation quality. Ultimately, FlowShift achieves high-fidelity continuous generation without sacrificing pre-trained semantic grounding.
arXiv:2611.05803v1 Announce Type: new Abstract: How much phonological knowledge do language models (LMs) possess about Chinese characters, and how is this knowledge represented and used? We introduce PinyinBench, a controlled benchmark covering homophones, phonological features (initials, finals, and tones), and polyphonic characters. We investigate 17 text-only and multimodal LMs through three complementary approaches: behavioral evaluation, layer-wise probing, and activation steering. Behaviorally, models demonstrate substantial knowledge of initials and finals, with a frontier model (DS-v4-flash) scoring 90%+ in homophone judgment, when two characters share no phonological features. However, its accuracy drops sharply to 72% when two characters differ only in lexical tone. Probing reveals that tone is highly decodable from embeddings and improves modestly across layers, whereas segmental information starts less decodable and improves substantially with depth. Activation steering shows that segmental representations can systematically influence generation, while tone exhibits much weaker effects. Furthermore, audio-bearing training improves phonological decodability, including tone, without corresponding improvements in steering effectiveness. Together, these findings reveal distinct representational and functional profiles for segmental and tonal information, with tonal information much harder to access and manipulate, demonstrating the necessity for combined evaluation, probing, and causal intervention for understanding linguistic knowledge in LMs.
arXiv:2611.05392v1 Announce Type: new Abstract: Agentic artificial intelligence (AI) systems powered by large language models (LLMs) execute as autonomous multi-step pipelines that dynamically invoke tools, integrate observations into memory, and iterate until a task is resolved or a resource budget is exhausted. Unlike classical workflows with fixed graphs, the aggregate compute, bandwidth, and end-to-end latency demands of such pipelines are unknown at dispatch time: they emerge at runtime from intermediate observations and stochastic token sampling, yielding heavy-tailed, multi-modal random variables. This unpredictability forces infrastructure orchestrators into a dilemma: under-provisioning risks mid-execution throttling and deadline violations, while over-provisioning wastes scarce edge or cloud capacity. Existing schedulers require a fully known pipeline graph, while edge resource-management methods rely on parametric or stationary demand models, and neither fits the unknown, non-stationary profiles of agentic pipelines. We formalize this setting as the uncertainty-aware agentic orchestration problem, where the goal is to reserve, at dispatch time, compute and bandwidth allocations that cover actual pipeline demands, and to verify that the pipeline can meet its deadline, each with a prescribed probability. We then propose Conformal Reservation for Orchestration (CRO), an online algorithm that translates a sliding window of past execution traces into dispatch-time resource allocations with finite-sample, distribution-free coverage guarantees via conformal prediction. Simulations over heterogeneous task mixes with multi-modal and heavy-tailed profiles show that CRO is the only evaluated method that simultaneously satisfies target probabilistic coverage across all risk levels while, among coverage-feasible methods, attaining the lowest over-reservation, roughly halving the resource waste of the Chebyshev-bound baseline.
arXiv:2611.04034v1 Announce Type: new Abstract: Transfer learning from pretrained backbones has become standard practice in multi-sensor computer vision---yet two questions remain open: which pretrained weights transfer best to multi-sensor setups, and can in-domain pretraining outperform off-the-shelf solutions? Frameworks like MultiMAE demonstrate the utility of masked autoencoding in a multi-modal context, but rely entirely on dense, model-derived modalities. It is unclear how robustly these methods translate to real-world applications that use physical sensors, where the aggregation of diverse public datasets for large-scale pretraining inherently introduces modality sparsity. To investigate this systematically, we curate a multi-sensor autonomous driving collection of $2.82M$ images from 16 publicly available datasets, incorporating both physical hardware modalities (RGB, LWIR, NIR, Event) and model-derived modalities (Stereo Depth, Segmentation). We use this collection for in-domain pretraining based on the MultiMAE approach. We adapt MultiMAE's loss formulation to accommodate sparse samples, and study the effect of an enforced encoder bottleneck for modality alignment and of additional losses specific to dense reconstruction (SSIM and FFT). We then systematically compare against common pretrained backbones (ViT, MAE, DINO and MultiMAE) across downstream sensor fusion tasks. We find that MultiMAE is a surprisingly strong out-of-the-box baseline, transferring effectively even to modalities it has never seen, while our targeted modifications yield incremental but consistent improvements on multi-sensor transfer and overall robustness.
arXiv:2611.04087v1 Announce Type: new Abstract: Scientific discovery builds on accurate observations interpreted through domain knowledge and reasoning. For scientific 3D data, this requires understanding structures and spatial relationships, from protein contacts to anatomical organization. Existing multimodal benchmarks largely evaluate text and 2D images, while scientific 3D evaluations vary in representations and protocols across disciplines, limiting cross-disciplinary comparison. To assess these foundational capabilities, we introduce ScienceVision, a cross-domain benchmark for scientific 3D understanding and reasoning through expert-level visual question answering (VQA). We construct 250 questions, with 50 each from Biology, Chemistry, Medical Imaging, Mechanical CAD, and Architecture, through a pipeline combining synthetic question generation with domain-expert review and annotation. Each task pairs a native 3D artifact with a scientific question, a specified response format, and a task-specific reference answer, requiring domain knowledge to be applied to geometric or topological evidence. We evaluate 12 models on the same questions in three settings: visual question answering with native 3D artifacts accessed through an agent harness's file and code-execution tools; the same workflow augmented with expert-inspired viewer inspection and measurement tools exposed through the Model Context Protocol (MCP); and visual question answering from prescribed rendered 2D images using an agent harness. All settings use the same task-specific deterministic final-answer scoring. The inspection environment supports view changes, target isolation, and slice inspection. In this main comparison, the best mean answer score is 0.53 out of 1. Mean scores in the native-artifact workflow without additional MCP tools exceed those in the rendered-image workflow for every model, by 17.2 percentage points on average.
Dify 1.19.0 enhances observability with nested workflow tracing, allowing users to follow execution steps inside Workflow Tools, inspect LLM calls, and maintain context across nested invocations. The release also enables portable app packages via App packages, improves Agent file uploads and previews, introduces Skill Hub automation through CLI commands, and upgrades the bundled plugin daemon to version 0.6.14-local. Key changes include support for format v2 app packages, enhanced security, improved editing workflows, and updated environment variables and API endpoints.
vLLM supports Kimi K3.1 Pro on day 0: sparse attention on a KDA hybrid, a packed KV cache with FP8 or NVFP4 latents and MXFP4 index keys, token-sharded prefill, decode context parallelism, and fused low-latency decode.
arXiv:2610.37867v1 Announce Type: new Abstract: Food similarity underlies retrieval, recommendation, substitution, and other food computing tasks, yet food representations are typically evaluated by identity preservation. We ask what happens to food similarity beyond identity: how different visual representations organize foods into relational neighborhoods, what culinary relationships these neighborhoods reveal or obscure, and how consistently these structures emerge across representations. Indian cuisine provides a challenging setting in which visually similar foods may have different culinary identities, while foods within a culinary family can vary substantially in appearance. Using an expanded Khana dataset and seven pretrained visual representations spanning convolutional, transforme
arXiv:2610.38355v1 Announce Type: new Abstract: KV cache reuse accelerates LLM serving, but existing systems manage host DRAM and NVMe SSD as a tiered hierarchy where DRAM acts as an intermediate cache. Production LLM workloads break both premises of this hierarchy. First, bimodal reuse defeats DRAM temporal filtering, since workloads are dominated either by one-shot blocks with long reuse distances or by multi-gigabyte agentic sessions that exceed DRAM capacity, putting SSD on the critical read path. Second, DRAM staging and eviction-ordered layout bottleneck SSD restoration. Holding host staging buffers for in-flight prefixes causes contention under load that aborts prefetches, while incremental eviction scatters a session's blocks across the SSD and prevents large sequential reads. We p
Since coding is solved, why code for the job?

Google DeepMind released Genie 4 as a research preview. The real-time world model adds native audio, live dialogue and text steering, with Gemini 3.8 Flash planning events inside the simulation loop. The post Meet Google DeepMind’s Genie 4: Real-Time World Model With Native Audio appeared first on MarkTechPost.

arXiv:2610.36178v1 Announce Type: new Abstract: We measure, without sampling error, the probability a language model assigns to each integer from 1 to N when asked for a random number. For a fixed prompt the model defines one probability vector, which we compute by summing over each integer's scored spellings rather than estimate by sampling, removing the noise that limits earlier studies [1, 4]. We evaluate 18 open-weight model lines at five ranges up to N = 100, under 29 decoding configurations, on two inference stacks; 15 of them have matched base and instruction-tuned checkpoints that both give usable answers. Instruction tuning makes the distribution less uniform in all 15 pairs. It installs one heuristic, round-number avoidance, and sharpens another, endpoint avoidance. Base checkpoi
arXiv:2610.36013v1 Announce Type: new Abstract: General-purpose embodied intelligence requires robots to coordinate diverse skills over long horizons, track task progress, and recover from failures. Specialist policies alone do not ensure task-level reliability, while powerful multimodal agents rely on costly reasoning and external experience that compact models struggle to reproduce. We introduce OmniBrain-0, a lightweight unified embodied agent that coordinates manipulation and navigation through a shared high-level decision model, integrating task understanding, planning, progress tracking, and feedback-driven recovery. Our progressive training framework combines embodied pretraining, domain-specialized agent distillation, and multi-teacher on-policy distillation (MOPD). It distills pow
NVIDIA Nemotron 3.5 Transcribe and Granary v2: Intelligent Multilingual Transcription You Can Prompt and Adapt
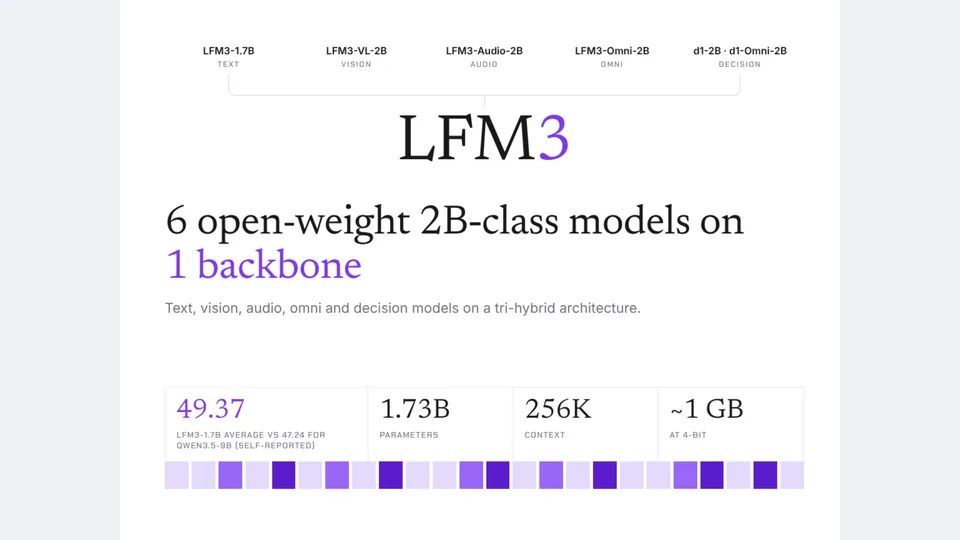
Liquid AI released LFM3, 6 open-weight 2B-class models for text, vision, audio, omni and decisions. LFM3-1.7B uses a tri-hybrid backbone, a 256K context window and fits in about 1 GB at 4-bit. The post Liquid AI Releases LFM3: 6 Open-Weight 2B-Class Multimodal Models appeared first on MarkTechPost.