Skip to content
AI NEWS JOURNAL
AI, IN PERSPECTIVE

Search AI news

Search headlines, summaries and articles to connect the dots.

Newest first

After talking to many parties, why did Apple ultimately choose only Alibaba?

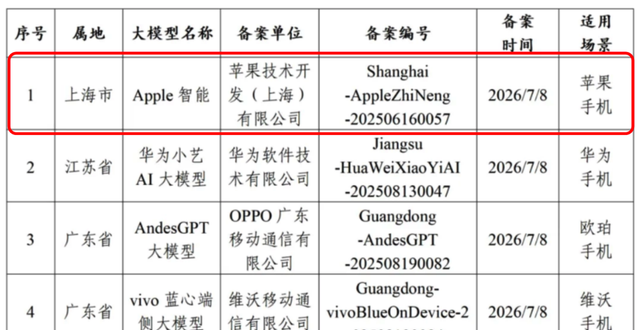
On October 31, the official announcement finally came: Apple and Alibaba have formally reached a cooperation agreement, allowing Chinese users to directly use Alibaba’s Qwen within Siri, writing tools, and visual intelligence applications. After more than two years of waiting, Apple Intelligence is finally coming to mainland China. Interestingly, over the past two years, numerous domestic large-model companies—Baidu, Tencent, ByteDance, DeepSeek, Zhipu…—have all been linked to Apple in one way or another. So why was it only Alibaba’s Qwen that ended up “winning the prize”? In fact, if we look closely, we’ll find that Apple had no real choice but to go with Alibaba. 01. Compliance Is the First Barrier Overseas, Apple Intelligence’s main partners are OpenAI and Google. But in China, neither of these companies’ models is available. However, this doesn’t mean that models which are usable domestically and properly registered can simply be integrated into Apple Intelligence; they still require separate on-device generative AI service registration. Meanwhile, as a hand...

谈了一圈,为什么苹果最后只能选阿里?
Timeline and related coverage

llama.cpp · b12032

sycl: Try PkgConfig for LevelZero includes / libs (#31076) **Website:** - **Attestations:** - **macOS/iOS:** - [macOS Apple Silicon (arm64)](https://github.com/ggml-org/llama.cpp/releases/download/b12032/llama-b12032-bin-macos-arm64.tar.gz) - macOS Apple Silicon (arm64, KleidiAI enabled) [DISABLED](https://github.com/ggml-org/llama.cpp/pull/23780) - [macOS Intel (x64)](https://github.com/ggml-org/llama.cpp/releases/download/b12032/llama-b12032-bin-macos-x64.tar.gz) - [iOS XCFramework](https://github.com/ggml-org/llama.cpp/releases/download/b12032/llama-b12032-xcframework.zip) **Linux:** - [Ubuntu x64 (CPU)](https://github.com/ggml-org/llama.cpp/releases/download/b12032/llama-b12032-bin-ubuntu-x64.tar.gz) - [Ubuntu arm64 (CPU)](https://github.com/ggml-org/llama.cpp/releases/download/b12032/

Timeline and related coverage

llama.cpp · b12029

mtmd : fix InternVL CLS token order (#30886) **Website:** - **Attestations:** - **macOS/iOS:** - [macOS Apple Silicon (arm64)](https://github.com/ggml-org/llama.cpp/releases/download/b12029/llama-b12029-bin-macos-arm64.tar.gz) - macOS Apple Silicon (arm64, KleidiAI enabled) [DISABLED](https://github.com/ggml-org/llama.cpp/pull/23780) - [macOS Intel (x64)](https://github.com/ggml-org/llama.cpp/releases/download/b12029/llama-b12029-bin-macos-x64.tar.gz) - [iOS XCFramework](https://github.com/ggml-org/llama.cpp/releases/download/b12029/llama-b12029-xcframework.zip) **Linux:** - [Ubuntu x64 (CPU)](https://github.com/ggml-org/llama.cpp/releases/download/b12029/llama-b12029-bin-ubuntu-x64.tar.gz) - [Ubuntu arm64 (CPU)](https://github.com/ggml-org/llama.cpp/releases/download/b12029/llama-b12029-b

Timeline and related coverage

llama.cpp · b12028

tests : enable Gemma 4 in `test-llama-archs` (#31401) * tests : enable Gemma 4 in `test-llama-archs` * tests : use GQA for Gemma 4 in `test-llama-archs` **Website:** - **Attestations:** - **macOS/iOS:** - [macOS Apple Silicon (arm64)](https://github.com/ggml-org/llama.cpp/releases/download/b12028/llama-b12028-bin-macos-arm64.tar.gz) - macOS Apple Silicon (arm64, KleidiAI enabled) [DISABLED](https://github.com/ggml-org/llama.cpp/pull/23780) - [macOS Intel (x64)](https://github.com/ggml-org/llama.cpp/releases/download/b12028/llama-b12028-bin-macos-x64.tar.gz) - [iOS XCFramework](https://github.com/ggml-org/llama.cpp/releases/download/b12028/llama-b12028-xcframework.zip) **Linux:** - [Ubuntu x64 (CPU)](https://github.com/ggml-org/llama.cpp/releases/download/b12028/llama-b12028-bin-ubuntu-x64.

Timeline and related coverage

llama.cpp · b12027

llama : enable tensor split for LFM3 (#31431) Assisted-by: Claude Opus 5.5 **Website:** - **Attestations:** - **macOS/iOS:** - [macOS Apple Silicon (arm64)](https://github.com/ggml-org/llama.cpp/releases/download/b12027/llama-b12027-bin-macos-arm64.tar.gz) - macOS Apple Silicon (arm64, KleidiAI enabled) [DISABLED](https://github.com/ggml-org/llama.cpp/pull/23780) - [macOS Intel (x64)](https://github.com/ggml-org/llama.cpp/releases/download/b12027/llama-b12027-bin-macos-x64.tar.gz) - [iOS XCFramework](https://github.com/ggml-org/llama.cpp/releases/download/b12027/llama-b12027-xcframework.zip) **Linux:** - [Ubuntu x64 (CPU)](https://github.com/ggml-org/llama.cpp/releases/download/b12027/llama-b12027-bin-ubuntu-x64.tar.gz) - [Ubuntu arm64 (CPU)](https://github.com/ggml-org/llama.cpp/releases/

Timeline and related coverage

[Digital Intelligence Weekly Report] Zhang Yiming has topped the list of China’s richest individuals with a fortune of 670 billion yuan, setting a new record for China’s wealthiest person; Alibaba has partnered with Apple to integrate Qwen into Apple’s smart ecosystem; Anthropic has filed its IPO registration documents, planning to list on Nasdaq under the ticker symbol “ANT.”

(October 26–31) OpenAI is reportedly lowering its target for the next round of fundraising by $10 billion, aiming to raise $20 billion at a valuation of $1.25 trillion; Google has launched its latest world model, Genie 4, doubling the simulation duration to two minutes and achieving synchronized audio-video generation for the first time; Meta plans to raise $35 billion and intends to issue shares worth $60 billion; CITIC Securities: GPT-6 Astra has entered robot control, marking a major turning point for physics-based AI...

Timeline and related coverage

llama.cpp · b12024

reshaping so mm on 2d instead of 3d tensor for lfm sc (#30831) **Website:** - **Attestations:** - **macOS/iOS:** - [macOS Apple Silicon (arm64)](https://github.com/ggml-org/llama.cpp/releases/download/b12024/llama-b12024-bin-macos-arm64.tar.gz) - macOS Apple Silicon (arm64, KleidiAI enabled) [DISABLED](https://github.com/ggml-org/llama.cpp/pull/23780) - [macOS Intel (x64)](https://github.com/ggml-org/llama.cpp/releases/download/b12024/llama-b12024-bin-macos-x64.tar.gz) - [iOS XCFramework](https://github.com/ggml-org/llama.cpp/releases/download/b12024/llama-b12024-xcframework.zip) **Linux:** - [Ubuntu x64 (CPU)](https://github.com/ggml-org/llama.cpp/releases/download/b12024/llama-b12024-bin-ubuntu-x64.tar.gz) - [Ubuntu arm64 (CPU)](https://github.com/ggml-org/llama.cpp/releases/download/b12

Timeline and related coverage

llama.cpp · b12022

server : fix /v1/responses endpoint to accept extra_params (#30959) **Website:** - **Attestations:** - **macOS/iOS:** - [macOS Apple Silicon (arm64)](https://github.com/ggml-org/llama.cpp/releases/download/b12022/llama-b12022-bin-macos-arm64.tar.gz) - macOS Apple Silicon (arm64, KleidiAI enabled) [DISABLED](https://github.com/ggml-org/llama.cpp/pull/23780) - [macOS Intel (x64)](https://github.com/ggml-org/llama.cpp/releases/download/b12022/llama-b12022-bin-macos-x64.tar.gz) - [iOS XCFramework](https://github.com/ggml-org/llama.cpp/releases/download/b12022/llama-b12022-xcframework.zip) **Linux:** - [Ubuntu x64 (CPU)](https://github.com/ggml-org/llama.cpp/releases/download/b12022/llama-b12022-bin-ubuntu-x64.tar.gz) - [Ubuntu arm64 (CPU)](https://github.com/ggml-org/llama.cpp/releases/downloa

Timeline and related coverage

llama.cpp · b12021

mtmd : resize Gemma 4 images without letterbox padding (#30922) * mtmd : resize Gemma 4 images without letterbox padding * Apply suggestion from @ngxson --------- Co-authored-by: Xuan-Son Nguyen **Website:** - **Attestations:** - **macOS/iOS:** - [macOS Apple Silicon (arm64)](https://github.com/ggml-org/llama.cpp/releases/download/b12021/llama-b12021-bin-macos-arm64.tar.gz) - macOS Apple Silicon (arm64, KleidiAI enabled) [DISABLED](https://github.com/ggml-org/llama.cpp/pull/23780) - [macOS Intel (x64)](https://github.com/ggml-org/llama.cpp/releases/download/b12021/llama-b12021-bin-macos-x64.tar.gz) - [iOS XCFramework](https://github.com/ggml-org/llama.cpp/releases/download/b12021/llama-b12021-xcframework.zip) **Linux:** - [Ubuntu x64 (CPU)](https://github.com/ggml-org/llama.cpp/releases/do

Timeline and related coverage

llama.cpp · b12020

opencl: add fwht (#31434) Co-authored-by: Li He **Website:** - **Attestations:** - **macOS/iOS:** - [macOS Apple Silicon (arm64)](https://github.com/ggml-org/llama.cpp/releases/download/b12020/llama-b12020-bin-macos-arm64.tar.gz) - macOS Apple Silicon (arm64, KleidiAI enabled) [DISABLED](https://github.com/ggml-org/llama.cpp/pull/23780) - [macOS Intel (x64)](https://github.com/ggml-org/llama.cpp/releases/download/b12020/llama-b12020-bin-macos-x64.tar.gz) - [iOS XCFramework](https://github.com/ggml-org/llama.cpp/releases/download/b12020/llama-b12020-xcframework.zip) **Linux:** - [Ubuntu x64 (CPU)](https://github.com/ggml-org/llama.cpp/releases/download/b12020/llama-b12020-bin-ubuntu-x64.tar.gz) - [Ubuntu arm64 (CPU)](https://github.com/ggml-org/llama.cpp/releases/download/b12020/llama-b1202

Timeline and related coverage

llama.cpp · b12019

chat : strip the think block in the qwen3-coder with reasoning_format none (#31380) * chat : accept the think block in the qwen3-coder response format with reasoning_format none Assisted-by: Claude Opus 5.5 * chat : define both qwen3-coder think block variants up front **Website:** - **Attestations:** - **macOS/iOS:** - [macOS Apple Silicon (arm64)](https://github.com/ggml-org/llama.cpp/releases/download/b12019/llama-b12019-bin-macos-arm64.tar.gz) - macOS Apple Silicon (arm64, KleidiAI enabled) [DISABLED](https://github.com/ggml-org/llama.cpp/pull/23780) - [macOS Intel (x64)](https://github.com/ggml-org/llama.cpp/releases/download/b12019/llama-b12019-bin-macos-x64.tar.gz) - [iOS XCFramework](https://github.com/ggml-org/llama.cpp/releases/download/b12019/llama-b12019-xcframework.zip) **Linu

Timeline and related coverage

llama.cpp · b12018

sycl: fix f32 to q2_0/q4_0/q5_0 rounding in CPY (#31120) **Website:** - **Attestations:** - **macOS/iOS:** - [macOS Apple Silicon (arm64)](https://github.com/ggml-org/llama.cpp/releases/download/b12018/llama-b12018-bin-macos-arm64.tar.gz) - macOS Apple Silicon (arm64, KleidiAI enabled) [DISABLED](https://github.com/ggml-org/llama.cpp/pull/23780) - [macOS Intel (x64)](https://github.com/ggml-org/llama.cpp/releases/download/b12018/llama-b12018-bin-macos-x64.tar.gz) - [iOS XCFramework](https://github.com/ggml-org/llama.cpp/releases/download/b12018/llama-b12018-xcframework.zip) **Linux:** - [Ubuntu x64 (CPU)](https://github.com/ggml-org/llama.cpp/releases/download/b12018/llama-b12018-bin-ubuntu-x64.tar.gz) - [Ubuntu arm64 (CPU)](https://github.com/ggml-org/llama.cpp/releases/download/b12018/ll

Timeline and related coverage

China‑bound Apple Intelligence enters beta testing in 4 days! Alibaba officially announces full integration of Qwen.

Author: Li Shuiqing | Editor: Xin Yuan — According to Zhidongxi (WeChat official account: zhidxcom), on October 31, Alibaba announced a partnership with Apple to integrate Qwen into Apple Intelligence. Chinese users will be able to directly access Qwen’s capabilities for text and image understanding, content generation, and more, within Siri, writing tools, and visual intelligence features. These functions will begin beta testing starting November 4 alongside the latest iOS Developer Beta version, and...

国行苹果智能倒计时4天开测!阿里官宣,千问全面接入
Timeline and related coverage

Refuse to Be Held Hostage by AI! Apple’s New Leader, John Ternus, Unveils a “Hardcore” Product Vision

IT Home reported on October 31 that Wired published a blog post yesterday (October 30), interviewing Apple’s current CEO, John Ternus, and discussing topics such as the future direction of Apple’s product lineup and developments in the field of AI. On the product front, Ternus repeatedly emphasized during the interview that he is a “product-focused CEO”: he loves products, values hardware and attention to detail, and hopes Apple will continue to succeed by creating experiences that people truly love...

拒绝被AI绑架!苹果新掌门特努斯的“硬核”产品宣言
Timeline and related coverage

Apple officially announces Apple Intelligence’s integration with Alibaba Qwen; DeepSeek completes its second round of financing totaling 105.5 billion yuan, with a valuation reaching 615.5 billion yuan; Intel’s stock plunges more than 30% at the open | Geek Morning Briefing

China-bound Apple Intelligence has confirmed its launch timeline: beta testing begins in November, and Qwen will be integrated into Siri on October 31. Apple announced that the first batch of features for China-bound Apple Intelligence will be available for beta testing starting November 4 alongside the iOS Developer Beta, and will officially roll out to users in December with iOS 27.3. The initial features include real-time translation, writing tools, photo removal, AI-generated emojis, and notification summaries, supporting the iPhone 15 Pro series, iPhone 16 and later models, as well as the iPhone Air and iPhone Duo. Alibaba emphasized that before any questions, documents, or images are sent to Qwen, user consent will always be obtained first. Apple stated that these features are powered by its own proprietary models, while users also have the option to integrate Alibaba Qwen to handle certain requests within Siri, writing tools, and visual intelligence. However, the initial update does not include the new version of Siri AI, and other platforms such as iPad and Mac will need to wait for necessary approvals. (Source: GeekPark) OpenAI rescinds its plan to reduce quotas for Pro 200 while increasing usage limits for Work and Codex. On October 29 local time, OpenAI announced adjustments to the usage quotas for Work and Codex under the Pro and Business Premium subscriptions. The original quotas for Pro 100 and Pro 500 have been doubled, and even users of the previously lower‑quota Pro 200 now receive a doubling of their limits, aligning them with those who originally enjoyed higher quotas. These new limits take effect immediately, without requiring existing subscribers to wait until their next renewal. This also means OpenAI has withdrawn its earlier announcement from late September regarding quota reductions for Pro 200, allowing users who previously had higher limits to retain them. It should be noted, however, that doubling the quota does not guarantee doubling the number of tasks you can complete—actual consumption depends on the model, task type, and speed mode. In Fast mode, quota consumption is roughly 2.5 times faster than in standard mode, while Ultrafast mode consumes at about eight times the rate. (Source: ITBears) Intel’s stock plunged more than 30% at the open, potentially marking the largest single-day drop in recorded history. Following the opening bell on October 30, Intel shares plummeted sharply, with intraday losses at one point exceeding 3

Timeline and related coverage