
Skip to content
AI NEWS JOURNAL
AI, IN PERSPECTIVE

Search AI news

Search headlines, summaries and articles to connect the dots.

Newest first

Liquid AI unveils the LFM3 multimodal model family, emphasizing efficient, specialized intelligence

Recently, Liquid AI officially launched its next-generation foundation model family, LFM3. The first release includes six models with approximately 2 billion parameters, covering text, vision, audio, omni-modal, and decision-making capabilities—all built on the LFM3-1.7B-Base foundation and achieving a pre-training throughput of 22 trillion tokens. This series adopts a novel tri-hybrid layer architecture, integrating gated short convolutions, sliding windows, and other mechanisms, prioritizing fewer parameters and higher efficiency.

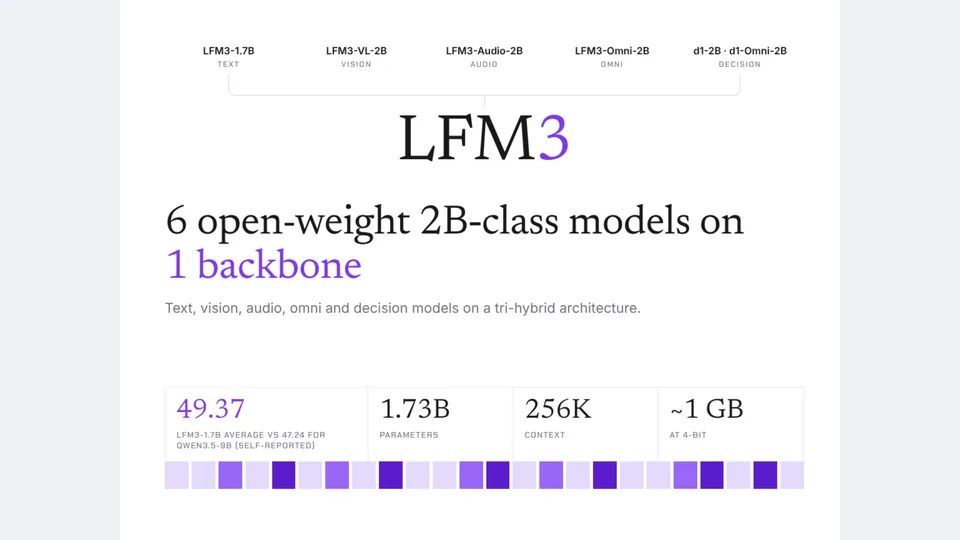
Liquid AI重磅发布LFM3 多模态模型家族,主打高效专用智能
Timeline and related coverage

Mining Frames: Association Rule Mining as an Unsupervised Framework for News Framing Detection

arXiv:2610.31874v1 Announce Type: new Abstract: Computational framing analysis is dominated by supervised classifiers that require large annotated corpora and predefined frame taxonomies, limiting their use for non-English languages, novel events, and low-resource settings. This paper presents Association Rule Mining (ARM) as an unsupervised, annotation-free framework for news framing detection. Each document or sentence is treated as a transaction of lexical items, and high-lift co-occurrence rules are read as candidate framing signals (Gamson and Modigliani's condensing symbols), confirmed in context by journalist-researchers. The primary validation is Framing Gaza: 25,512 English-language articles from 16 US, UK, French, and German outlets covering the first year of the Gaza war (Octobe

Timeline and related coverage

IBM releases the Granite Speech 5.0 series of speech models: supporting multilingual transcription, translation, and speaker attribution.

IBM has released three open-source speech models in the Granite Speech 5.0 series—granite-speech-5.0-2b (high-precision multilingual ASR/MT), granite-speech-5.0-470m-turboctc (ultra-fast edge-side multilingual transcription), and the updated granite-speech-4.1-2b-plus (enhanced multi-speaker conversational modeling)—all licensed under Apache 2.0 and compatible with mainstream inference frameworks.

Timeline and related coverage

AnyLanguageModel 1.0 released: a unified Swift interface supporting both local and hosted models, compatible with the entire Apple platform family of operating systems 27

Hugging Face has officially released AnyLanguageModel 1.0, an open-source Swift framework fully compatible with the Apple Foundation Models API. It supports seamless switching between local models (MLX, llama.cpp, Core ML) and hosted models (OpenAI, Anthropic, Gemini, Hugging Face Inference Providers, etc.), and introduces new features such as image input, tool invocation, guided generation, and automatic adaptation of inference chunks.

Timeline and related coverage

Qwen2.5: A Party of Foundation Models!

GITHUB HUGGING FACE MODELSCOPE DEMO DISCORD Introduction In the past three months since Qwen2’s release, numerous developers have built new models on the Qwen2 language models, providing us with valuable feedback. During this period, we have focused on creating smarter and more knowledgeable language models. Today, we are excited to introduce the latest addition to the Qwen family: Qwen2.5. We are announcing what might be the largest opensource release in history!

Hello Qwen2

GITHUB HUGGING FACE MODELSCOPE DEMO DISCORD Introduction After months of efforts, we are pleased to announce the evolution from Qwen1.5 to Qwen2. This time, we bring to you: Pretrained and instruction-tuned models of 5 sizes, including Qwen2-0.5B, Qwen2-1.5B, Qwen2-7B, Qwen2-57B-A14B, and Qwen2-72B; Having been trained on data in 27 additional languages besides English and Chinese; State-of-the-art performance in a large number of benchmark evaluations; Significantly improved performance in coding and mathematics; Extended context length support up to 128K tokens with Qwen2-7B-Instruct and Qwen2-72B-Instruct.

Qwen1.5-MoE: Matching 7B Model Performance with 1/3 Activated Parameters

GITHUB HUGGING FACE MODELSCOPE DEMO DISCORD Introduction Since the surge in interest sparked by Mixtral, research on mixture-of-expert (MoE) models has gained significant momentum. Both researchers and practitioners are keenly interested in understanding how to effectively train such models and assessing their efficiency and effectiveness. Today, we introduce Qwen1.5-MoE-A2.7B, a small MoE model with only 2.7 billion activated parameters yet matching the performance of state-of-the-art 7B models like Mistral 7B and Qwen1.