Skip to content
AI NEWS JOURNAL
AI, IN PERSPECTIVE

Search AI news

Search headlines, summaries and articles to connect the dots.

Newest first

Cities Worldwide Build and Scale AI Services With NVIDIA Physical and Agentic AI

Cities generate enormous amounts of data from cameras, sensors and operational systems, but turning it into useful action — for planning, maintenance and public services — remains a challenge. Physical and agentic AI offer new ways to close that gap, from digital twins for infrastructure planning to vision and service agents, while keeping local governments […]
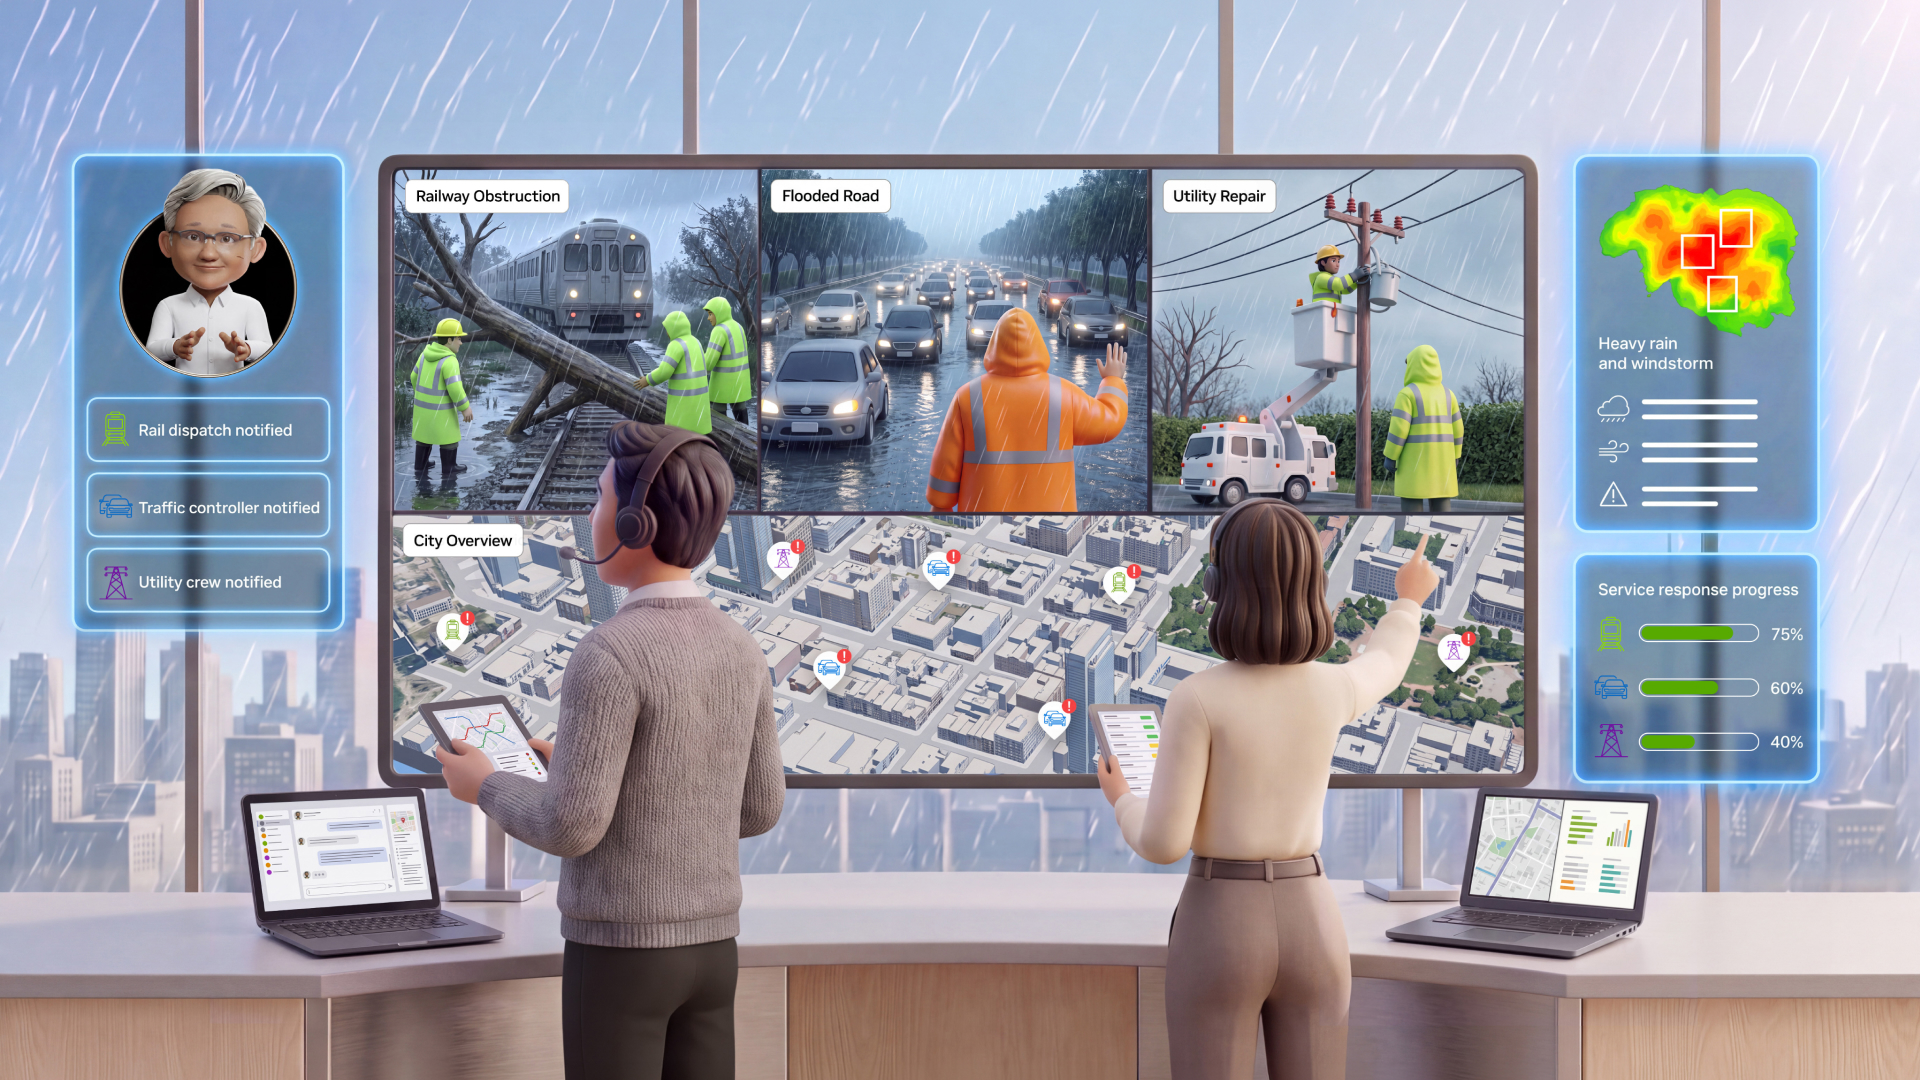
Cities Worldwide Build and Scale AI Services With NVIDIA Physical and Agentic AI

Responsible Quantum Machine Learning for Medical Imaging: A Fairness Audit Across Sensitive Subgroups

arXiv:2610.37819v1 Announce Type: new Abstract: Quantum machine learning (QML) is increasingly explored for medical classification, yet its behaviour under subgroup-aware fairness criteria remains understudied. We present an empirical fairness audit of classical and quantum classifiers for medical imaging, assuming QML is not inherently fair. Two scenarios are evaluated: dermatological lesions on DDI (sensitive attribute: Fitzpatrick skin type) and chest X-rays on CheXpert-derived data (sensitive attribute: age group). Using ResNet-18 embeddings, we train SVM, MLP, QSVM and QCNN under a baseline and three mitigation settings: differentiable Equalized Odds (EO) regularisation, Gradient Reversal Learning (GRL), and both combined. Foundation models (PanDerm, EVA-X) serve as external reference

Timeline and related coverage

Intuit rewires accounting education as AI pushes new hires toward client work

As AI automates routine finance work, the repetitive tasks that once defined entry-level accounting are disappearing, and advisory services are moving to the center of how firms create value. That shift leaves colleges racing to prepare graduates for a job that looks very different from the one in the textbooks. Closing the gap between classroom […] The post Intuit rewires accounting education as AI pushes new hires toward client work appeared first on SiliconANGLE.

Timeline and related coverage

Intuit rewires accounting education as AI pushes new hires toward client work

As AI automates routine finance work, the repetitive tasks that once defined entry-level accounting are disappearing, and advisory services are moving to the center of how firms create value. That shift leaves colleges racing to prepare graduates for a job that looks very different from the one in the textbooks. Closing the gap between classroom […] The post Intuit rewires accounting education as AI pushes new hires toward client work appeared first on SiliconANGLE.

Timeline and related coverage

Dell sees AI agent guardrails as a path to greater autonomy

As enterprises put AI agents to work, they face a challenge: How can they give those systems more autonomy while keeping AI agent guardrails in place? Security and resilience are becoming central considerations as enterprises decide which tasks to delegate to AI agents. Those decisions extend beyond individual actions to the data protection and cyber […] The post Dell sees AI agent guardrails as a path to greater autonomy appeared first on SiliconANGLE.

Timeline and related coverage

OpenESM: Energy-Steered Models Are Scalable Foundation Learners

arXiv:2610.33005v1 Announce Type: new Abstract: Energy-based models have shown promising properties for domain-specific tasks but remain challenging in modeling general-purpose scenarios. To bridge this gap, we design energy-steered models (ESMs) for foundational language modeling. ESMs integrate energy steering and token generation within a single architecture to leverage the energy-guided search to refine token generation. Specifically, ESMs first optimize a latent state over the energy landscape, then leverages the refined latent state for token generation. By performing such energy-guided pre-training on large-scale corpora, ESMs learn generally effective energy landscape where favorable tokens correspond to lower energy values. To explore the scaling behavior of ESMs, we pre-train ESM

新闻源配图 · arXiv cs.CL
Timeline and related coverage

Async-RBench: Benchmarking Asynchronous Task Execution in LLM Agents

arXiv:2610.32429v1 Announce Type: new Abstract: Large language model (LLM) agents increasingly execute tasks asynchronously: a main agent continues working while its subagents run, and the task state may change before their results arrive. The main agent must decide which work to update or preserve and which checks to repeat, while avoiding prohibited changes. Final task success alone does not reveal whether these results were handled correctly, and natural asynchronous arrivals are hard to reproduce. We introduce Async-RBench, a benchmark for asynchronous task execution in LLM agents, with 200 executable tasks covering eight scenarios. A scenario controller regulates result delivery using predefined task-state conditions, while an Event Response Contract (ERC) specifies what each response

Timeline and related coverage

Position, Role or Label? A Controlled Study of Instruction Conflicts in LLM Agents

arXiv:2610.33201v1 Announce Type: new Abstract: LLM agents take instructions from the operator, repository configuration, user, tool results and saved memory, which often conflict. Instruction-hierarchy benchmarks ask whether the higher-ranked source wins, but a source sets position, role and label at once. First, we build WhoWins, 1,080 code-scored scenarios in five task types, each with up to five mutually exclusive instructions, and seven controlled experiments that vary only how instructions are delivered. Second, we study 14 open-weight models (0.6B to 122B, thinking off and on) over 1,887,356 scored replies, checking main findings on held-out scenarios. Inside one message the first of two conflicting lines wins 72.42 to 94.66%, and across messages it keeps 22.95 to 62.65%. A policy s

Timeline and related coverage

DualPace: Decoupled Scheduling and Cooperative GPU--CPU Decoding for LLM Serving

arXiv:2610.33501v1 Announce Type: new Abstract: Large language model (LLM) serving relies on batching to improve inference throughput, but the key-value (KV) cache grows with sequence length and limits GPU-resident concurrency. CPU offloading can expand KV capacity using host memory, yet existing systems remain largely GPU-gated: CPU-resident requests make progress only when the GPU scheduler exposes suitable overlap opportunities. As a result, host memory and CPU compute cannot act as an independent serving resource, leading to bursty CPU-side progress and inflated tail inter-token latency (ITL) under load. We present DualPace, an LLM serving runtime that turns the host into an independently scheduled decode engine. DualPace separates scheduling authority across two engines: the GPU engin

Timeline and related coverage

FlexA-Mem: Budget-Adaptive Agentic Memory for LLM Agents

arXiv:2610.33274v1 Announce Type: new Abstract: Large language model (LLM) agents work in scenarios with very different memory needs. A question about past conversations needs the exact facts it names, while a multi-step task needs a trace of the steps already taken together with details that the next step cannot name. Existing memories are each designed and tested for one kind of scenario. Retrieval memories such as A-Mem miss steps that the current query does not express, summaries drop exact strings, and pairing the two fixes the split of the budget in advance. We propose FlexA-Mem, a general memory that writes each unit of history once into an immutable store and renders a fresh memory for every call. The rendered memory is a compact timeline of records plus detail that a fixed rule fi

Timeline and related coverage