
[AINews] Anthropic files for $2T IPO in 2 weeks: 1400% growth rate, 48% of revenue through cloud partners, 85% margin, $1B op profit in Q2, $134B cash in bank and $10B lifetime burn
The S-1, the numbers, and the reactions.
Search headlines, summaries and articles to connect the dots.
The S-1, the numbers, and the reactions.
Unprecedented demand for bandwidth calls for bringing optics closer to silicon through a fundamental rethinking of the optical interconnect roadmap. The post The imec Report: Scaling Optical Interconnects For The AI Era appeared first on Semiconductor Engineering.
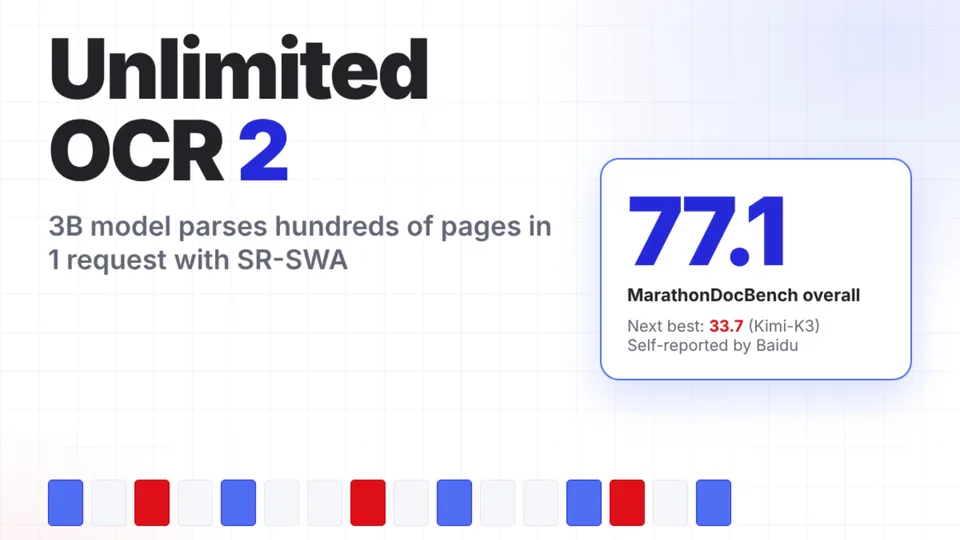
Baidu has released Unlimited OCR 2, an MIT-licensed 3B OCR model that parses hundred-page documents in one request. Its SR-SWA attention keeps per-step decoding cost nearly flat, scoring 77.1 on MarathonDocBench The post Baidu Open-Sources Unlimited OCR 2 for Hundred-Page Document Parsing appeared first on MarkTechPost.
For most of its 30-year history, Cisco Partner Summit has focused on how partners sell Cisco Systems Inc. technology. This year’s event in Vancouver was about something different: how partners make money in a world where the transaction is no longer the main event. Cisco entered the event with tremendous momentum, as its stock was […] The post Cisco Partner Summit: Five insights that will define the channel in the AI era appeared first on SiliconANGLE.
arXiv:2610.33065v1 Announce Type: new Abstract: EEG visual decoding remains difficult because scalp recordings are noisy, spatially coarse, and variable across trials and subjects. Most systems align each trial with a dense image embedding, although that embedding mixes semantic content with instance-specific texture, pose, and background. This target can demand details absent from EEG and provides no explicit account of the visual factors supporting a prediction. We propose \textbf{ProtoEEG}, a prototype-mediated framework that reformulates EEG--image alignment as soft composition over a shared learnable visual codebook. A trainable EEG encoder and a frozen visual teacher produce assignment distributions over the same $K=64$ prototypes. Their weighted reconstructions form a structured rep
arXiv:2610.34419v1 Announce Type: new Abstract: DAG-based BFT protocols marked a shift in consensus design by replacing single-leader proposal paths with concurrent block proposals linked through a shared graph, where references encode consensus evidence. However, under heterogeneous wide-area networks (WANs), existing designs suffer from prolonged rounds and degraded performance due to straggler effects. The root cause is rigid round advancement: replicas move in synchronized rounds, waiting for enough references from the previous round before advancing. We propose a flexible DAG growth framework for asynchronous BFT consensus. Our key observation is that while reference quorums are necessary for safety and liveness, they need not block every round advancement. Instead, the connectivity r
arXiv:2610.32997v1 Announce Type: new Abstract: Automatic Speech Recognition (ASR) models such as OpenAIs Whisper have substantially improved speech recognition quality but remain expensive to fine-tune, especially when large amounts of transcribed audio are available. This makes it challenging for many practitioners to adapt these models to new languages or domains. In this work, we introduce an embedding-based subset selection approach for selecting smaller training sets for ASR fine-tuning. Using Whispers pretrained encoder, we map each audio sample into a fixed-dimensional embedding space and apply a greedy k-center algorithm to select diverse and representative subsets of the training data. We evaluate this approach on both Hebrew and Danish, showing that k-center selection often impr

arXiv:2610.33366v1 Announce Type: new Abstract: Large language models (LLMs) are increasingly used to support research idea generation and scientific discovery. Multi-agent debate offers a collaborative approach to this task by bringing together diverse perspectives to develop research ideas. However, a key challenge is how to equip agents with distinct and meaningful expertise to guide their contributions. Inspired by how researchers draw on accumulated research experience during collaboration, we introduce InsightAgents, a framework that constructs literature-grounded agent expertise by distilling insights from graphs of related papers. Guided by insights that trace evolving research approaches, reveal underlying assumptions, and identify unresolved challenges, within a line of research,
arXiv:2610.33044v1 Announce Type: new Abstract: Embodied vision-language models must answer questions from partial, evolving observations. Their success depends on both the reasoning capability selected and the evidence available to it. Expert routers adapt internal computation, while tool-augmented systems acquire external evidence; choosing these independently can leave a suitable expert without the evidence it needs. We introduce EKT-Router, a bounded framework that jointly selects a capability expert, optional knowledge, and perceptual tools. Outcome-derived signatures represent the overlapping strengths of General, Spatial Reasoning, and Spatiotemporal experts. A joint utility scores complete expert-evidence routes under a call budget. After acquisition, a packet verifier admits valid
arXiv:2610.34521v1 Announce Type: new Abstract: Actor frameworks on mainstream runtimes advertise Erlang/OTP-style supervision, but OTP's consistency contracts assume a synchronous, single-threaded supervisor, and ports inherit that assumption's absence as unexamined risk. We evaluated every supervision guarantee against pinned OTP documentation and source read verbatim, against the source of three further Rust actor frameworks at fixed revisions, and against the actor-model literature, recording the evidence behind each design decision. Blind adversarial audits and the cross-framework study surfaced 24 defect classes, of which eight reduce to one root cause: reconstructing, by explicit mechanism, the atomicity a synchronous supervisor gets implicitly. We introduce a supervision runtime th
arXiv:2610.32429v1 Announce Type: new Abstract: Large language model (LLM) agents increasingly execute tasks asynchronously: a main agent continues working while its subagents run, and the task state may change before their results arrive. The main agent must decide which work to update or preserve and which checks to repeat, while avoiding prohibited changes. Final task success alone does not reveal whether these results were handled correctly, and natural asynchronous arrivals are hard to reproduce. We introduce Async-RBench, a benchmark for asynchronous task execution in LLM agents, with 200 executable tasks covering eight scenarios. A scenario controller regulates result delivery using predefined task-state conditions, while an Event Response Contract (ERC) specifies what each response
arXiv:2610.33014v1 Announce Type: new Abstract: A negotiation assistant can reach a good deal without accurately predicting the other person's response. We ask whether evaluations of social world models test that prediction directly. We audit 113 works published from 1999 to 2026. 9 primary evaluations measure a real person's response to an action selected by the system or experimenter. Only 2 also compare an explicit response forecast with that response. Their predictors use information available when the action is chosen, and the evaluated responses were excluded from fitting; both randomize the intervention. A separate full-text check of 25 language-model works finds no experiment meeting these conditions. The other evaluations test current-state inference, task success, or prediction f
arXiv:2610.33475v1 Announce Type: new Abstract: The widespread deployment of foundational Large Language Models (LLM) across cloud datacenters marks a fundamental paradigm shift from stateless deep learning toward distributed, memory-intensive generative workloads. However, serving massive foundation models under stringent Service Level Objectives (SLO) exposes critical physical and system bottlenecks. These challenges include the persistent High Bandwidth Memory (HBM) wall, operational asymmetry between compute-bound prefilling and memory-bandwidth-bound decoding, explosive Key-Value (KV) cache expansion, prohibitive serverless cold starts, and hardware reliability vulnerabilities. Existing literature reviews remain layer-siloed, decoupling low-level accelerator virtualization from cluste
arXiv:2610.33001v1 Announce Type: new Abstract: Academic revision presents a governance problem when legitimate writing objectives conflict. Writing-process and social-science research show that revision is recursive and that wording carries epistemic and disciplinary commitments. Those literatures identify important constraints but do not settle which objective should prevail when concision, outlet form or stylistic variation conflicts with evidence and claim boundaries. This paper models revision as an admissibility problem under ordered constraints. Task-relative invariants, contextual constraints and mutable presentation choices define the admissible space; a claim-preservation contract links evidence and judgement to an authorised claim boundary. Four governance propositions specify p
arXiv:2610.32308v1 Announce Type: new Abstract: Multi-step retrosynthesis requires recursively transforming a target molecule through successive reaction steps into purchasable building blocks, and recent work has begun to draw on large language model (LLM) reasoning to tackle the task. In its latest evolution, LLM reasoning has entered the long-horizon regime: models pursue objectives across interdependent steps, interact with environments, and adapt to feedback. This shift has markedly advanced LLM capabilities, as illustrated by breakthroughs in AI-driven mathematical research. At this frontier, we introduce Solvent, an 8B LLM that successfully extends long-horizon reasoning to multi-step retrosynthesis. Through a two-round post-training curriculum, Solvent learns to interleave iterativ
arXiv:2610.32305v1 Announce Type: new Abstract: Multi-stage analytical tasks require LLM agents to use intermediate evidence to decide whether to continue, redirect or stop. Self-reflection, in which an agent critiques its output, is widely studied, yet a critique does not show whether evidence changed the next action. We call that capability self-restraint. Existing agent benchmarks largely measure task completion or output quality and leave it untested. DMAIC-Bench evaluates it with 97 seeded tasks across 15 industrial cases in four sectors, built around Lean Six Sigma's explicit statistical prerequisites. Paired counterfactual variants require opposite actions at the same workflow position, distinguishing warranted restraint from indiscriminate stopping. We assess execution traces with
arXiv:2610.33016v1 Announce Type: new Abstract: Llama-3, Qwen3 and many other open LLMs pre-tokenize text with a regular expression whose word class admits only Unicode letters. Devanagari vowel signs are combining marks, so this regex splits Nepali words at every vowel sign, and models that use it spend 2.6 to 5.8 times as many tokens on Nepali as on the same English text. Merge-based vocabulary extension cannot join the split pieces: for Llama-3 and Qwen3 no number of new merges brings this premium below about 2.2, and ten released extensions already end within 4% of this pre-token floor. We give a small edit to the deployed regex that provably keeps every token id of text without combining marks or Devanagari characters. With 32,000 new merges it brings Nepali to 1.01 times English, abo
arXiv:2610.31968v1 Announce Type: new Abstract: Accurate ambulance travel time estimation is critical for emergency medical dispatch, yet existing decision-support practices often rely on static lookup tables or simplified assumptions regarding how ambulance travel time differs from ordinary passenger-car travel. For instance, they assume ambulances simply travel a fixed percentage (e.g., 5%) faster than ordinary passenger cars. However, such assumptions are rarely validated using real ambulance operational data and may fail to capture the effects of trip priority, temporal context, and origin-destination. We address these limitations using historical ambulance trips from the Sk{\aa}ne region in Sweden. Our analysis reveals that ambulance travel times vary substantially by hour, day, and t
arXiv:2610.32179v1 Announce Type: new Abstract: Neural architecture search (NAS) is expensive, but cross-task transfer can reduce costs by reusing knowledge from previous tasks. However, existing methods struggle with sparse search histories and task-specific transfer failures. We propose a method, a risk-robust strategy that combines sparse source logs with zero-cost proxies through champion-based initialization and joint pairwise-ranker pretraining. On TransNAS-Bench-101, the proposal mitigates severe worst-case failures, reducing worst-10% ranks from 290 to 43 for Micro autoencoding and from 465 to 45 for Macro room layout. Across 13 cell-space targets, it outperforms a proxy-only ranker on 10 targets in both mean and worst-case performance, while maintaining competitive average perform
arXiv:2610.35564v1 Announce Type: new Abstract: Serverless computing platforms must preserve quality of service (QoS) while adapting to highly bursty and unpredictable workloads. To cope with workload fluctuations while satisfying QoS requirements and service-level agreements (SLAs), these platforms rely on automatic resource scaling. Commercial function-as-a-service (FaaS) platforms employ different autoscaling strategies to dynamically adjust the number of active function instances and the available processing capacity. In this work, three representative autoscaling strategies are modeled and compared: scale-per-request (SPR), concurrencylevel scaling (CLS), and metric-based scaling (MBS). To enable systematic evaluation independent of proprietary platform-specific implementations, we de