
Measuring how AI agents handle everyday wet-lab science
OpenAI introduces BioBasicsBench, a 100-task benchmark measuring how well AI agents interpret raw experimental data and handle everyday wet-lab science.
Search headlines, summaries and articles to connect the dots.
OpenAI introduces BioBasicsBench, a 100-task benchmark measuring how well AI agents interpret raw experimental data and handle everyday wet-lab science.
Chris Alexiuk has a simple rule about open source AI: If you believe in it, be loud about it. “We should be shouting about this technology from the rooftops,” said Alexiuk, a Toronto-based senior product research engineer in deep learning at NVIDIA who specializes in making open large language models (LLMs) practical for working developers. […]
Phonon, a small text-to-speech model that runs entirely on the user's device without requiring internet access, has been released with support for English, French, German, Spanish, and Portuguese. Built on the Pocket TTS lineage using flow matching, Phonon achieves high-quality audio in compact sizes (65 MB and 75 MB), with the 31m version licensed under Apache 2.0 for commercial use. It excels in intelligibility and speed, ranking first in German and Spanish on Hugging Face's Open TTS Leaderboard and leading in CPU streaming benchmarks. The model supports voice cloning, custom voices via Gradium Studio, and integrates with Hugging Face Transformers. It is available in multiple formats and backends, including WebAssembly, GPU, and NPU, enabling deployment across phones, laptops, single-board computers, and browsers. Over 200,000 downloads were recorded in its first two weeks, with active developer adoption through tools like ExecuTorch, Micdrop, and Spaces. Future developments include support for additional languages, smaller models, and custom vocabulary fine-tuning.
vLLM supports Kimi K3.1 Pro on day 0: sparse attention on a KDA hybrid, a packed KV cache with FP8 or NVFP4 latents and MXFP4 index keys, token-sharded prefill, decode context parallelism, and fused low-latency decode.
Since coding is solved, why code for the job?

Google DeepMind released Genie 4 as a research preview. The real-time world model adds native audio, live dialogue and text steering, with Gemini 3.8 Flash planning events inside the simulation loop. The post Meet Google DeepMind’s Genie 4: Real-Time World Model With Native Audio appeared first on MarkTechPost.

NVIDIA Nemotron 3.5 Transcribe and Granary v2: Intelligent Multilingual Transcription You Can Prompt and Adapt
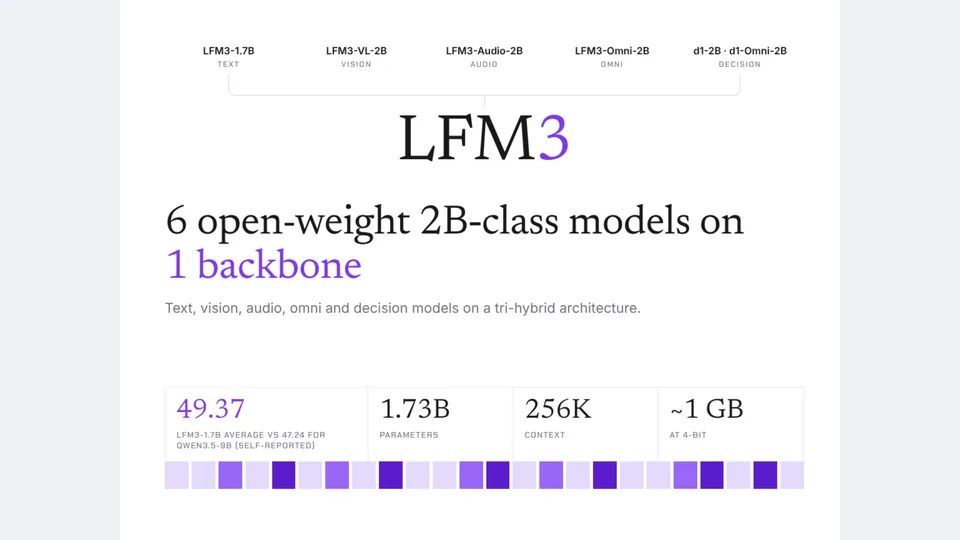
Liquid AI released LFM3, 6 open-weight 2B-class models for text, vision, audio, omni and decisions. LFM3-1.7B uses a tri-hybrid backbone, a 256K context window and fits in about 1 GB at 4-bit. The post Liquid AI Releases LFM3: 6 Open-Weight 2B-Class Multimodal Models appeared first on MarkTechPost.
Google DeepMind released Genie 4, a world model with real-time audio, more realistic simulations, and mid-simulation text prompts, in research preview for trusted testers.
There are 57 million people worldwide living with dementia today. For the researchers working to help them, the obstacle isn’t a lack of effort — it’s too much data, too few experts to synthesize it and a pace of discovery that can’t keep up with the disease. The Consortium for Biomedical Research and AI in […]
Edge Sound Research Inc. today announced it has raised $2 million in new funding to build audio infrastructure that isolates useful sounds and combines them with other sensor data to help physical AI systems understand what’s happening in real time. Stormbreaker Ventures led the round, bringing the company’s total funding to $9 million. When the […] The post Edge Sound raises $2M to help physical AI make sense of audio appeared first on SiliconANGLE.
Venture funding to robotics startups has soared in 2026, with the bulk of investment going to companies based in China and the U.S., Crunchbase data shows. All told, global venture funding to robotics startups totaled $9.9 billion in Q3, more than double the $4.3 billion invested in Q3 2025, per Crunchbase data.
The S-1, the numbers, and the reactions.
vLLM Semantic Router released d3-ultra, a 27B open-weight multimodal decision model. It reads text, images and video once, then returns probabilities for every answer, scoring 87.2 on the team’s SR-Text test. The post vLLM Semantic Router Releases d3-ultra: A 27B Open Multimodal Decision Model appeared first on MarkTechPost.

We're at the start of a major effort to speed up drug development with Claude. Over the past several months, our scientists have engaged in deep research partnerships with six organizations developing new medicines.
Build specialized multimodal models with LFM3
Elastic GPUs, sandbox growth, and the economics of the agent cloud
Elastic GPUs, sandbox growth, and the economics of the agent cloud
European AI cloud service providers such as Nebius, Nscale, and Verda, along with server manufacturers like Bull, Dell, and HPE, are building a new generation of energy-efficient, high-concurrency AI infrastructure based on NVIDIA’s Vera CPU, with a focus on supporting agentic computing workloads—including sandbox execution, semantic search, data analytics, and research collaboration.