
Skip to content
AI NEWS JOURNAL
AI, IN PERSPECTIVE

Search AI news

Search headlines, summaries and articles to connect the dots.

Newest first

Faster Retrieval for Better, More Efficient RAG

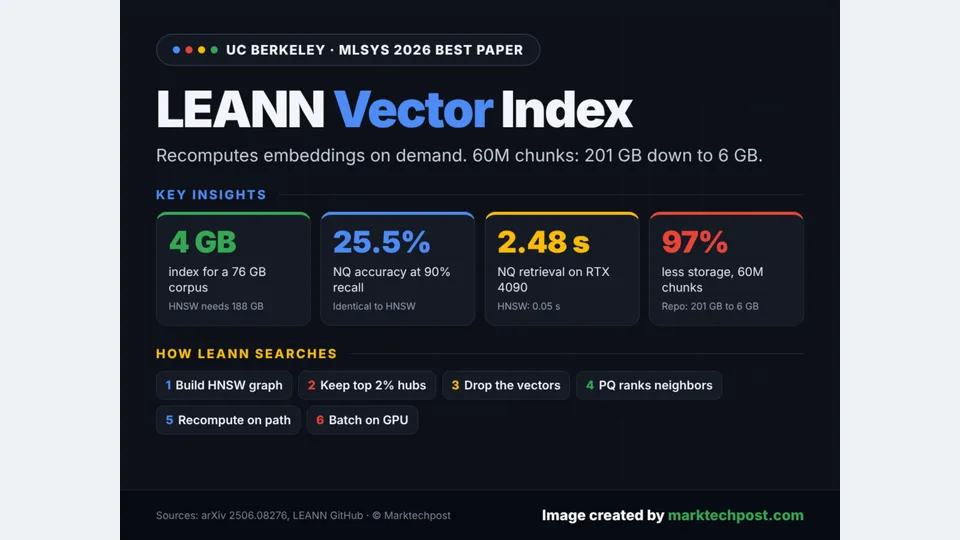
Maximum inner product search (MIPS) sits at the core of recommendation systems, search, and retrieval-augmented generation (RAG). Given a query vector, MIPS systems search within a database of millions of candidate key vectors for the one that best matches the query. The original data point associated with that best-matching key is then used to handle the query: in RAG, the document that is best suited to answer the question is typically prefixed to the query. As the number of keys grows to millions and vector dimensions reach thousands, the computational cost of running an exhaustive…

Intuition with Evidence: Adaptive Dual Memory for Multimodal Agents

arXiv:2610.33019v1 Announce Type: new Abstract: As multimodal agents engage in sustained interactions, long-term memory serves two distinct but complementary functions: fine-grained evidence recall and internalized interpretation for global understanding. Although episodic and latent memory address these demands through explicit historical records and internalized experience, neither paradigm alone can accommodate the diverse memory affinities across tasks, owing to limitations in episodic evidence coverage and integration, and in latent factual grounding. To bridge this divide, we propose a dual-memory framework, unifying a model-native latent memory as an intuitive prior with a multi-indexed episodic memory for exact evidence reconstruction via retrieval-conditioned joint alignment. At i

新闻源配图 · arXiv cs.CV
Timeline and related coverage

Chunk Recomputation under Real Document Revisions: Measuring Update Cost and Retrieval Quality of Fixed, Recursive, and Content-Defined Chunking

arXiv:2610.31019v1 Announce Type: new Abstract: Chunking strategies for retrieval-augmented generation are almost always evaluated on a static snapshot, yet the documents underlying a knowledge base continue to change. Because chunks are embedded independently, a boundary that moves after an edit forces unchanged text to be re-embedded. We measure this update cost on 120 pairs of adjacent Chinese and English Wikipedia revisions for three stateless chunkers (non-overlapping fixed-size, recursive paragraph-first, and content-defined chunking) under a strict byte-identical reuse rule and a frozen dense encoder. On the 116-article common-success pool, with frozen, length-calibrated parameters, fixed-size chunking recomputes 57-68% of its full new-version embedding-input workload, recursive chu

Chunk Recomputation under Real Document Revisions: Measuring Update Cost and Retrieval Quality of Fixed, Recursive, and Content-Defined Chunking
Timeline and related coverage