Skip to content
AI NEWS JOURNAL
AI, IN PERSPECTIVE

Search AI news

Search headlines, summaries and articles to connect the dots.

Newest first

b11951

chat : stop qwen3-coder reasoning and content before template separators (#30557) * chat : strip trailing whitespace from parsed reasoning and content Assisted-by: Claude Fable 5.1 * chat : stop qwen3-coder reasoning and content before template separators Assisted-by: Claude * tests : remove the Qwen parser case from the chat session tests Assisted-by: Claude * common : handle partial prefix until match at end of generation --------- Co-authored-by: Zeshawn Zahid Co-authored-by: Alde Rojas **Website:** - **Attestations:** - **macOS/iOS:** - [macOS Apple Silicon (arm64)](https://github.com/ggml-org/llama.cpp/releases/download/b11951/llama-b11951-bin-macos-arm64.tar.gz) - macOS Apple Silicon (arm64, KleidiAI enabled) [DISABLED](https://github.com/ggml-org/llama.cpp/pull/23780) - [macOS Intel

Timeline and related coverage

Is Token Confidence Just Chain Length? A Signal-Processing Audit of Reasoning Traces

arXiv:2610.36709v1 Announce Type: new Abstract: Reasoning language models answer math problems by writing long chains of thought, and sampling many chains per problem and taking a majority vote raises accuracy at a large cost in generated text. A popular way to cut that cost scores each chain by the model's confidence in each token it writes, where a token is a word or part of a word. The method averages this confidence over a sliding window of 2048 tokens and keeps or stops chains based on the lowest average. We treat the confidence, recorded token by token, as a signal in the sense of audio or radio, and examine the method with standard signal-processing tools such as spectral analysis and statistical tests for detecting a sudden change. We sampled 16 chains for each of 500 problems from

Timeline and related coverage

b11946

server : add realtime conversation and transcription on /v1/realtime (#31269) * server : add realtime conversation and transcription on /v1/realtime Co-authored-by: Xuan Son Nguyen Assisted-by: Claude Opus 5.5 * examples : default the realtime client to the server port 9931 Assisted-by: Claude Opus 5.5 * server : sample realtime responses right after their own decode Slots respond in turns on one context: sampling at the start of the next step read the logits of whichever slot decoded last, so concurrent sessions mixed their outputs. Assisted-by: Claude Opus 5.5 * move more stuff to server-realtime, making it self-contained * examples : fix the type check of the realtime client Assisted-by: Claude Opus 5.5 * examples : use the model card prompts in the realtime client Assisted-by: Claude O

Timeline and related coverage

b11945

model : add LiquidAI/d1-2B and LiquidAI/d1-omni-2B (#31275) * model : add LiquidAI/d1-2B and LiquidAI/d1-omni-2B Assisted-by: Claude Opus 5.5 * convert : keep the speech task templates out of the d1 GGUFs Assisted-by: Claude Opus 5.5 * small refactoring: no_batching --------- Co-authored-by: Xuan Son Nguyen **Website:** - **Attestations:** - **macOS/iOS:** - [macOS Apple Silicon (arm64)](https://github.com/ggml-org/llama.cpp/releases/download/b11945/llama-b11945-bin-macos-arm64.tar.gz) - macOS Apple Silicon (arm64, KleidiAI enabled) [DISABLED](https://github.com/ggml-org/llama.cpp/pull/23780) - [macOS Intel (x64)](https://github.com/ggml-org/llama.cpp/releases/download/b11945/llama-b11945-bin-macos-x64.tar.gz) - [iOS XCFramework](https://github.com/ggml-org/llama.cpp/releases/download/b119
Timeline and related coverage

b11944

server: expose the reasoning effort levels of the chat template (#31271) * server: expose the reasoning effort levels of the chat template The capability probe renders a user turn for each candidate level (minimal, low, medium, high, xhigh, max) and for an unknown level. A level is honored when it renders without raising and differently from the unknown level, which shows the template fallback. Levels sharing a render are aliases and the highest one is kept. The caps serialize to JSON, and chat_template_caps in /props reports the list as reasoning_effort_levels, from lowest to highest. * jinja: keep the caps free of the json dependency The caps keep reporting their flags as a map, and the effort levels stay a plain member. common_chat_templates_get_caps() builds the JSON the server reports

Timeline and related coverage

b11941

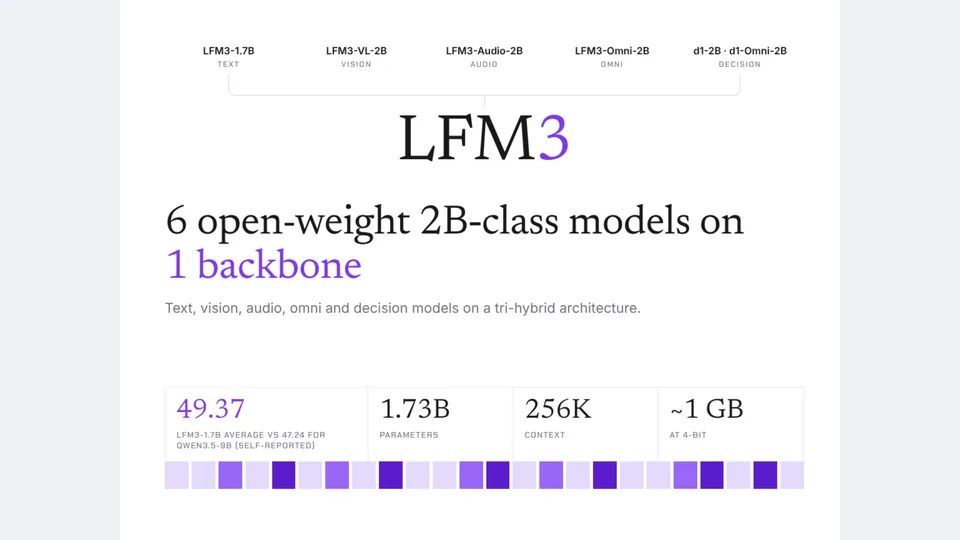
model : add LiquidAI/LFM3-Audio-2B and LiquidAI/LFM3-Omni-2B (#31257) * model : add LiquidAI/LFM3-Audio-2B and LiquidAI/LFM3-Omni-2B Co-authored-by: Xuan Son Nguyen Assisted-by: Claude Opus 5.5 * convert : read the LFM3-Audio config.json as released A transformers that knows lfm3_audio rewrites the config into another layout (no lfm/encoder keys). Assisted-by: Claude Opus 5.5 * mtmd : disable flash attention for the LFM3-Audio depthformer Assisted-by: Claude Opus 5.5 * tts : add a voice option for LFM3-Audio and LFM3-Omni The model card offers a female and a male voice; --tts-voice for llama-tts, "voice" for the server /tts. Assisted-by: Claude Opus 5.5 * clean up template handling * convert : detect LFM3-Audio and LFM3-Omni by model_type Assisted-by: Claude Opus 5.5 * move banned tokens -

Timeline and related coverage

b11940

common : support deferred tools and tool_reference content parts (#31256) * common : support deferred tools and tool_reference content parts Assisted-by: Claude Opus 5.5 * common : credit the deferred tools co-author Co-authored-by: Aldehir Rojas <765227+aldehir@users.noreply.github.com> Assisted-by: Claude Opus 5.5 * tests : fix the type check of the deferred tools test Assisted-by: Claude Opus 5.5 **Website:** - **Attestations:** - **macOS/iOS:** - [macOS Apple Silicon (arm64)](https://github.com/ggml-org/llama.cpp/releases/download/b11940/llama-b11940-bin-macos-arm64.tar.gz) - macOS Apple Silicon (arm64, KleidiAI enabled) [DISABLED](https://github.com/ggml-org/llama.cpp/pull/23780) - [macOS Intel (x64)](https://github.com/ggml-org/llama.cpp/releases/download/b11940/llama-b11940-bin-maco
Timeline and related coverage

b11938

model : add LiquidAI/LFM3-1.7B and LiquidAI/LFM3-VL-2B (#31252) * model : add LiquidAI/LFM3-1.7B and LiquidAI/LFM3-VL-2B Co-authored-by: Sigbjørn Skjæret Co-authored-by: Xuan-Son Nguyen Assisted-by: Claude Opus 5.5 * tests : set the SWA rope base of the LFM3 test model Assisted-by: Claude Opus 5.5 * llama : enable recurrent state rollback for LFM3 Assisted-by: Claude Opus 5.5 * Apply batched suggestions from code review Co-authored-by: Sigbjørn Skjæret Co-authored-by: Tarek Dakhran * gguf-py : align the lfm3vl mapping comments Assisted-by: Claude Opus 5.5 * llama : fix CRLF line endings from the review suggestions Assisted-by: Claude Opus 5.5 * tests : add the LFM3 Metal fusion baseline Assisted-by: Claude Opus 5.5 * llama : keep the LFM3-VL depthwise conv kernels in F32 when quantizing As

Timeline and related coverage

b11936

llama : build the k-pool sparse selection independently of the kq_mask shape (#31243) * llama : build the k-pool sparse selection independently of the kq_mask shape qwen4exp (QSA) and glm5-next pick cache cells by index and no longer read the kq_mask values, but they still shaped the selection like the dense kq_mask. Build the selection as [n_kv, n_tokens] over the cache cells instead, and split it into the streams of the K view right before the attention. This lets the dense mask change its layout (e.g. per-sequence row lists) without touching the sparse layers. * improve comment Co-authored-by: Georgi Gerganov * llama : drop the unused build_fused_top_k_mask args, review nits --------- Co-authored-by: Georgi Gerganov **Website:** - **Attestations:** - **macOS/iOS:** - [macOS Apple Silico

Timeline and related coverage

b11935

rpc : catch std::length_error in recv_msg (#31204) **Website:** - **Attestations:** - **macOS/iOS:** - [macOS Apple Silicon (arm64)](https://github.com/ggml-org/llama.cpp/releases/download/b11935/llama-b11935-bin-macos-arm64.tar.gz) - macOS Apple Silicon (arm64, KleidiAI enabled) [DISABLED](https://github.com/ggml-org/llama.cpp/pull/23780) - [macOS Intel (x64)](https://github.com/ggml-org/llama.cpp/releases/download/b11935/llama-b11935-bin-macos-x64.tar.gz) - [iOS XCFramework](https://github.com/ggml-org/llama.cpp/releases/download/b11935/llama-b11935-xcframework.zip) **Linux:** - [Ubuntu x64 (CPU)](https://github.com/ggml-org/llama.cpp/releases/download/b11935/llama-b11935-bin-ubuntu-x64.tar.gz) - [Ubuntu arm64 (CPU)](https://github.com/ggml-org/llama.cpp/releases/download/b11935/llama-b1

Timeline and related coverage

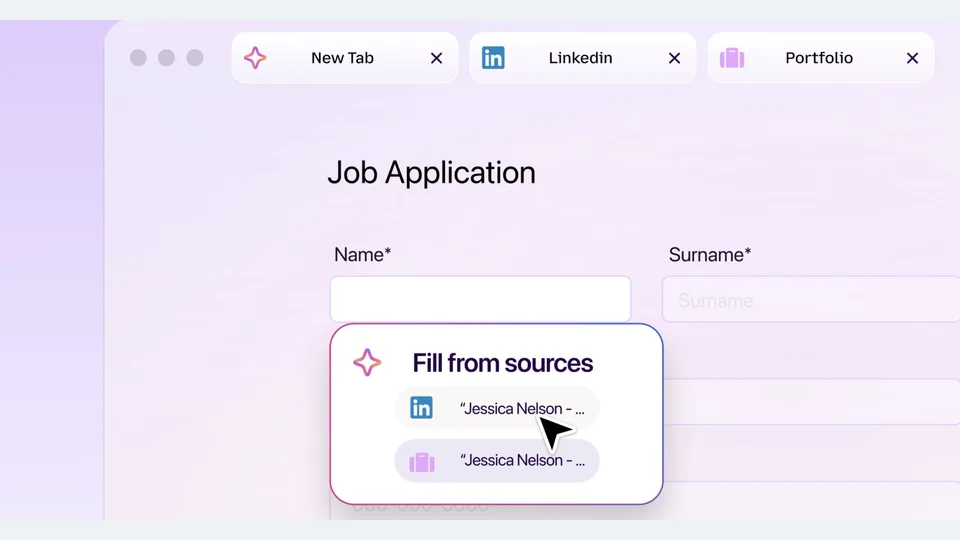
Firefox Smart Window adds an AI form-filling feature that can automatically extract information based on the current tab.

On October 27, 2026, Mozilla updated Firefox’s AI browsing feature, Smart Window, introducing a new capability to intelligently fill out forms based on the user’s currently open tabs. This feature supports extracting information from websites such as LinkedIn and personal portfolios to automatically populate multi-field forms like job application forms.

新闻源配图 · The Verge · AI

Why it matters:This update represents a significant advancement in Firefox’s recent AI feature iterations. As reported by The Verge and clearly dated October 27, 2026, the announcement focuses on specific interaction logic and use cases, with complete information elements and clear sources. However, it does not disclose technical implementation details, data processing methods, or privacy policies, nor does it specify whether this feature has been rolled out to all users or remains limited to certain testing channels.

Timeline and related coverage

b11934

tests : speed up tensor data generation and model saving (#31145) * tests : speed up tensor data generation and model saving Refactor save_models to create only the model, not a llama_context, which is not needed for saving. Replace the slow std::normal_distribution draw with a splitmix64 + box-muller normal generator. Assisted-by: dsh:llama.cpp/ggml-org/DeepSeek-V4-Flash-Vision-Exp-GGUF (Mac Studio, M2 Ultra, 192GB) * tests : use a shared pool of normal draws for tensor data Generate a pool of normal draws once with std::mt19937 and std::normal_distribution, then have every tensor copy a cyclic slice of it instead of running a per-tensor box-muller. The name-keyed slice selection keeps the draw deterministic. Assisted-by: dsh:llama.cpp/ggml-org/DeepSeek-V4-Flash-Vision-Exp-GGUF (Mac Studi

Timeline and related coverage