
AI Emergency Alerts Are Coming. Humans Might Not Be Ready
Human beings struggle with emergency communication. Chatbots can help—if people take them seriously.
Search headlines, summaries and articles to connect the dots.
Human beings struggle with emergency communication. Chatbots can help—if people take them seriously.
Google DeepMind released Genie 4 as a research preview. The real-time world model adds native audio, live dialogue and text steering, with Gemini 3.8 Flash planning events inside the simulation loop. The post Meet Google DeepMind’s Genie 4: Real-Time World Model With Native Audio appeared first on MarkTechPost.

server : add realtime conversation and transcription on /v1/realtime (#31269) * server : add realtime conversation and transcription on /v1/realtime Co-authored-by: Xuan Son Nguyen Assisted-by: Claude Opus 5.5 * examples : default the realtime client to the server port 9931 Assisted-by: Claude Opus 5.5 * server : sample realtime responses right after their own decode Slots respond in turns on one context: sampling at the start of the next step read the logits of whichever slot decoded last, so concurrent sessions mixed their outputs. Assisted-by: Claude Opus 5.5 * move more stuff to server-realtime, making it self-contained * examples : fix the type check of the realtime client Assisted-by: Claude Opus 5.5 * examples : use the model card prompts in the realtime client Assisted-by: Claude O
NVIDIA Nemotron 3.5 Transcribe and Granary v2: Intelligent Multilingual Transcription You Can Prompt and Adapt
KOHO explains why AI self-serve analytics needs a strong data culture and a governed dbt foundation first.
Most models in a dbt DAG aren't on the critical path. Espresso AI and Authentic Insurance on turning that slack into real savings.
Checkr gave its AI agent a structured dbt context layer, cutting a support-metric investigation from hours to minutes.
Education Innovation
Property Finder found that 96.8% of their vision-AI evaluation labels were inherited from the incumbent model, hiding its true accuracy. See how they built unbiased ground truth, applied evolutionary prompt optimization, and selected a more accurate, cost-effective model on Amazon Bedrock, cutting cost by 86% across 11 image-quality attributes.
KOHO explains why AI self-serve analytics needs a strong data culture and a governed dbt foundation first.
Assisted permissions are now generally available in GitHub Copilot CLI, GitHub Copilot app, and Visual Studio Code. When Copilot requests permission to run a command, access a file system path,… The post GitHub Copilot assisted permissions generally available appeared first on The GitHub Blog.
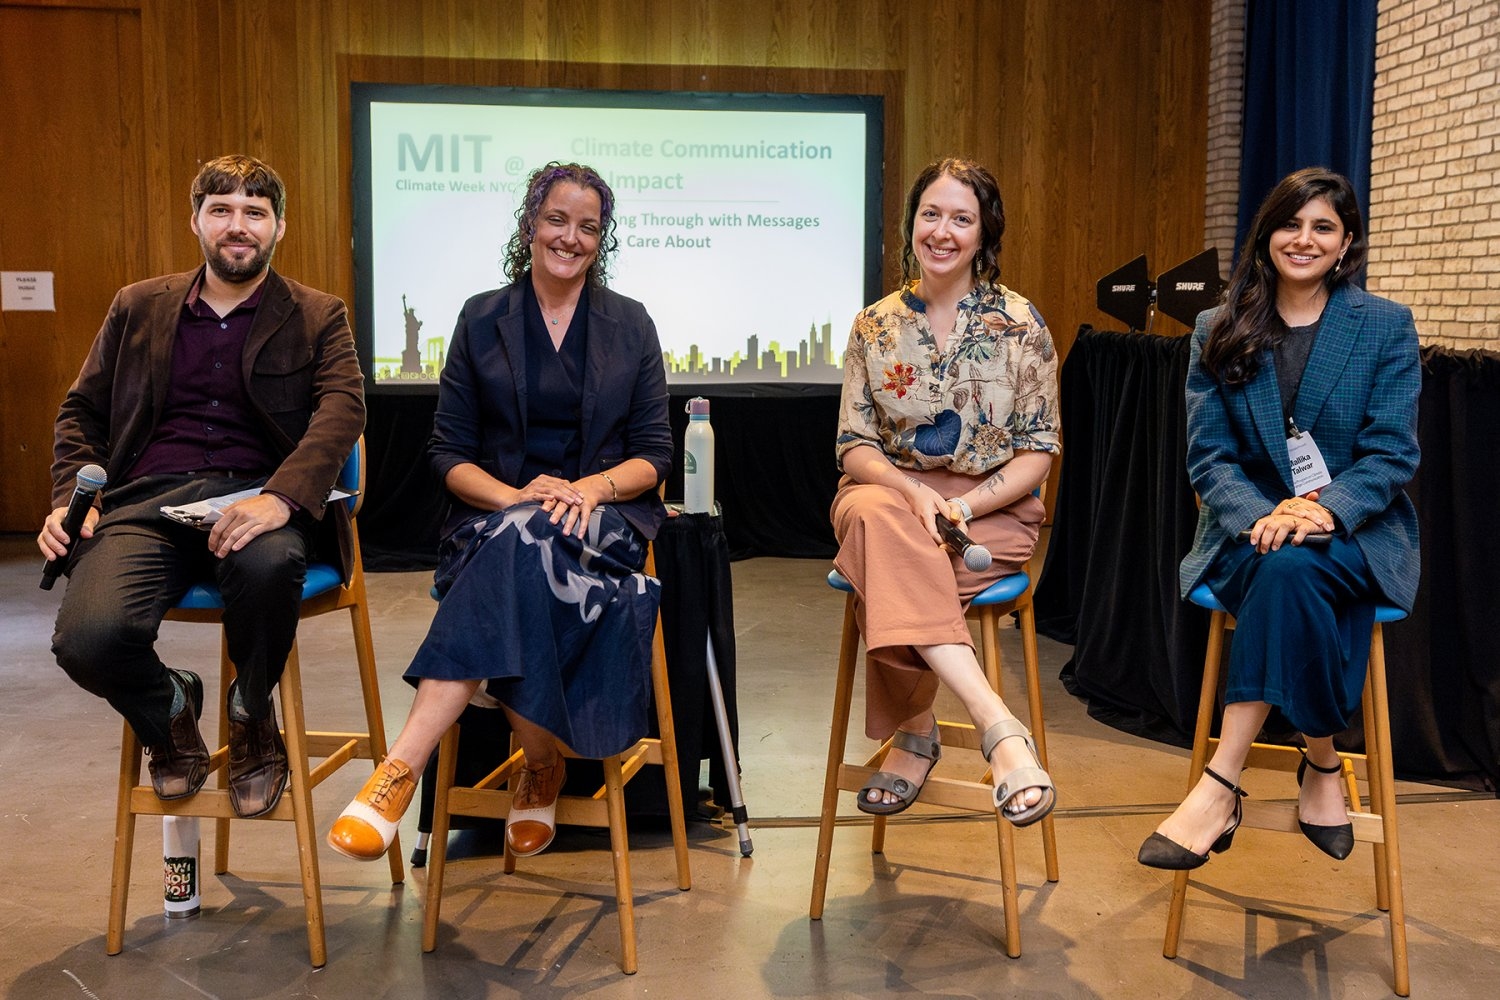
A cross-section of the MIT community convened discussions on topics ranging from data centers and super pollutants to agriculture and education.
Every time an agent takes a step, it re-reads its entire context before acting. Here is how prompt caching for OpenAI models on Amazon Bedrock lets your agent remember, cutting input cost and latency without resending the same tools, instructions, and history every turn.
We ran one AI skill 80 times against four context sources. Engineered summaries cut cost 48.5% and run time 43.2%.
Ramp shares the agents, sandboxes, and dashboards it built by treating internal AI as analytics engineering.
DocuSign wired Claude Code, dbt Agent Skills, dbt MCP, and dbt v2 into one workflow and measured a 50% productivity gain.
Careem's AI agent writes and validates dbt models end to end before a human ever reviews the PR.
During Singles’ Day, chat assistants can steer orders with coupons, while merchant software already bills for design and operations work. Platforms are monetizing existing budgets faster than they are monetizing consumer trust.
arXiv:2610.31946v1 Announce Type: new Abstract: Three students answered the same exam prompt by hand: "What is happiness? Are you happy?" Their ages, recorded at collection, are 17, 28, and 45. The 17-year-old's answer is hedged and formally phrased. Asked to match each answer to an age and gender label, most frontier language models confidently assign it to an adult. This paper reports a structured case study of that failure across six models: Claude Fable 5, Gemini 3.1 Pro, GPT-5.6 Sol, Grok 4.5, GPT-4o (2024), and DeepSeek V4. We ran 1,081 API sessions and scored 3,225 responses across six experimental conditions that manipulate framing, disclosure format, and audience-awareness instruction. Three of six models perform at or near chance (1/3) on the matching task while reporting 73-88%
arXiv:2610.31972v1 Announce Type: new Abstract: Evaluating conversational agents that act on live, mutable enterprise data is hard: replayed sessions drift as backend state changes, and a benchmark built today can silently go stale as the data it describes moves on. We present an offline evaluation harness for a production conversational agent that stays reproducible despite the live data it operates on changing, and that can be regenerated on demand once it goes stale. We then use this harness as the fitness function for GEPA-based prompt optimization under a correctness gate that guards against reward hacking. Applied to a production merchant-facing agent, correctness-gated compression shrinks the agent's full prompt surface by 3.5-7.6% without regressing held-out task correctness, consi
