
Skip to content
AI NEWS JOURNAL
AI, IN PERSPECTIVE

Search AI news

Search headlines, summaries and articles to connect the dots.

Newest first

Show HN: Rendering 3D Models in the Terminal

This is something that I've been making for a little under a year now. It has support for the new stuff like Kitty Graphics Protocol and Sixel, but still has fallbacks for terminals that don't support those. Also has textures, animations, wireframe, keyboard and mouse controls, and neovim support.https://github.com/Murat65536/dcat https://github.com/Murat65536/dcat.nvim Comments URL: https://news.ycombinator.com/item?id=50361230 Points: 2 # Comments: 0
Swapping the Judge Changes the Ranking: A Preregistered Study of Cross-Provider Replication in LLM-Judged System Comparisons

arXiv:2611.04090v1 Announce Type: new Abstract: Practitioners who compare systems with an LLM judge and have no human labels often check a conclusion by repeating it with a judge from another provider. We test how far that check can be trusted. In a preregistered study (with a disclosed post-registration reduction of the judge set), five judge models from three providers re-judged 4,000 Chatbot Arena battles (nine systems, 33 system pairs) that carry human votes, each in both response orders. Agreement with the human vote was low at the verdict level (median Cohen's kappa = 0.22), and system rankings did not survive a change of judge: Kendall's tau with the human ranking ranged from 0.17 to 0.89 (median 0.67), so the preregistered hypothesis that rankings remain stable was not supported. Conclusions replicated by two low-cost judges from different providers matched the human conclusion more often than single-judge conclusions (+0.10 precision), but the gain came from filtering out one poorly aligned judge, and replication involving that judge left a conclusion for only 35% of comparisons. Judges that agreed with humans reached a stable conclusion with no more verdicts than human votes required; the others failed to converge on 26-70% of system pairs at the sample sizes tested (up to 100 verdicts per pair). Disagreements with the human vote co-occurred across judges far more often than independence predicts, although a single human vote per battle cannot separate shared judge bias from voter noise.

v0.44.0

ComfyUI v0.44.0 introduces multiple new partner nodes for tools like Patina, VEED, BFL, Ideogram, Pruna, MiniMax, Topaz, Sonilo, and OpenAI, adding features such as higher resolution video upscaling, context window editing, and new models. Enhancements include support for ProRes and custom chroma subsampling in video saving, improved frontend handling with pinned versions, optimized tensor comparisons, and better VAE compute dtype control. Performance optimizations address redundant concatenations and memory management, while bug fixes resolve crashes related to VAE decoding and prefetch queue cleanup. The release also updates workflow templates, embedded documentation, and default settings, with contributions from new developers.

v1.19.0 - Trace Your Workflows, Layer by Layer

Dify 1.19.0 enhances observability with nested workflow tracing, allowing users to follow execution steps inside Workflow Tools, inspect LLM calls, and maintain context across nested invocations. The release also enables portable app packages via App packages, improves Agent file uploads and previews, introduces Skill Hub automation through CLI commands, and upgrades the bundled plugin daemon to version 0.6.14-local. Key changes include support for format v2 app packages, enhanced security, improved editing workflows, and updated environment variables and API endpoints.

vLLM Delivers Day-0 Support for Kimi K3.1 Pro

vLLM supports Kimi K3.1 Pro on day 0: sparse attention on a KDA hybrid, a packed KV cache with FP8 or NVFP4 latents and MXFP4 index keys, token-sharded prefill, decode context parallelism, and fused low-latency decode.

What Is This Memory Useful For? Measuring Task-Conditioned Utility in Long-Term Agent Memory

arXiv:2611.03930v1 Announce Type: new Abstract: A stored experience may answer one future question and offer little help with another. We measure this task-conditioned utility rather than assigning each memory a single importance score. A task-blind writer stores a memory without seeing the later task; a frozen reader then answers that task with and without the memory, using identical filler. A cost ledger records the resources used to form, store and expose the memory. On single-call factual-recall tasks built from LongMemEval-V2 web-agent memories, the same memory helps more when it contains information needed for the answer. Its mean paired reward gain on these answer-bearing task pairs exceeds that on matched-control pairs by $+0.33$ (95% interval $+0.21$ to $+0.46$). The tested task-blind summaries and structured records yield smaller gains than Raw, including at fixed total context; a budget sweep is consistent with retention of answer-bearing content contributing to the difference. The bearing--control contrast remains positive in a new session with randomized memory position and under a second reader, although individual memory--task labels change. Generic retrieval performs above chance but misses most screen-defined answer-bearing memories. The factual-recall gains do not extend to the tested software-engineering and scientific-coding benchmarks, where even raw memories have no measurable effect. We provide a public, versioned Conditional Memory Utility Dataset of paired measurements and costs. The practical takeaway is to evaluate memory compression by the task utility it preserves alongside its costs. Task-conditioned measurements make this comparison possible; their stability must also be checked.

Evaluate Vercel Flags from another project without sharing SDK keys.

Project Connections allow applications to evaluate flags from another Vercel project within the same team without managing SDK keys, using deployment identity for authentication. Access is managed via the Connections page or CLI, grants read-only access across all environments, and can be revoked without redeployment. Requires @flags-sdk/vercel 1.6.0 or later, or @vercel/flags-core 1.11.0 or later, and Vercel CLI 63.0.0 or later for CLI management.

How Mercor ships internal apps and billions of production tokens on one platform

Mercor reduced batch job processing time from 12 hours to 2–3 hours by using Vercel AI Gateway, which provided increased inference capacity and failover routing across providers. In its first 10 days on the platform, Mercor routed 18 million requests and 63 billion tokens without hitting rate limits. The company also leveraged Vercel Passport and its internal Audiences product to provision secure access for hundreds of business teams and over 2,000 projects in seconds, enabling rapid deployment of client-specific applications while maintaining strict usage controls and automated offboarding.

How OpenEvidence scales medical search for 650K doctors

OpenEvidence, a platform helping physicians access peer-reviewed medical evidence at the point of care, leverages Vercel to deploy updates in minutes, handle traffic spikes without additional provisioning, and reduce serverless costs by 90% through Fluid compute. The platform supports over 20 million clinical consultations monthly and serves more than 100 million Americans annually, with its small engineering team managing independent deployments for doctor- and patient-facing applications using Next.js and Vercel's infrastructure.

How Zapier turns ideas into working software in hours with Vercel

Zapier leverages Vercel to rapidly develop interactive partner demos in under two hours, build internal applications like Marketing Hive and Marketing OS in a day each, and securely share sensitive data through SSO-protected deployments. The platform enables non-developers to deploy applications, supports AI orchestration via AI Gateway, and facilitates scalable, secure code execution with 3.3 million sandboxes created monthly. Vercel's speed, security, and ease of use have become central to Zapier’s innovation across engineering, marketing, and sales teams.

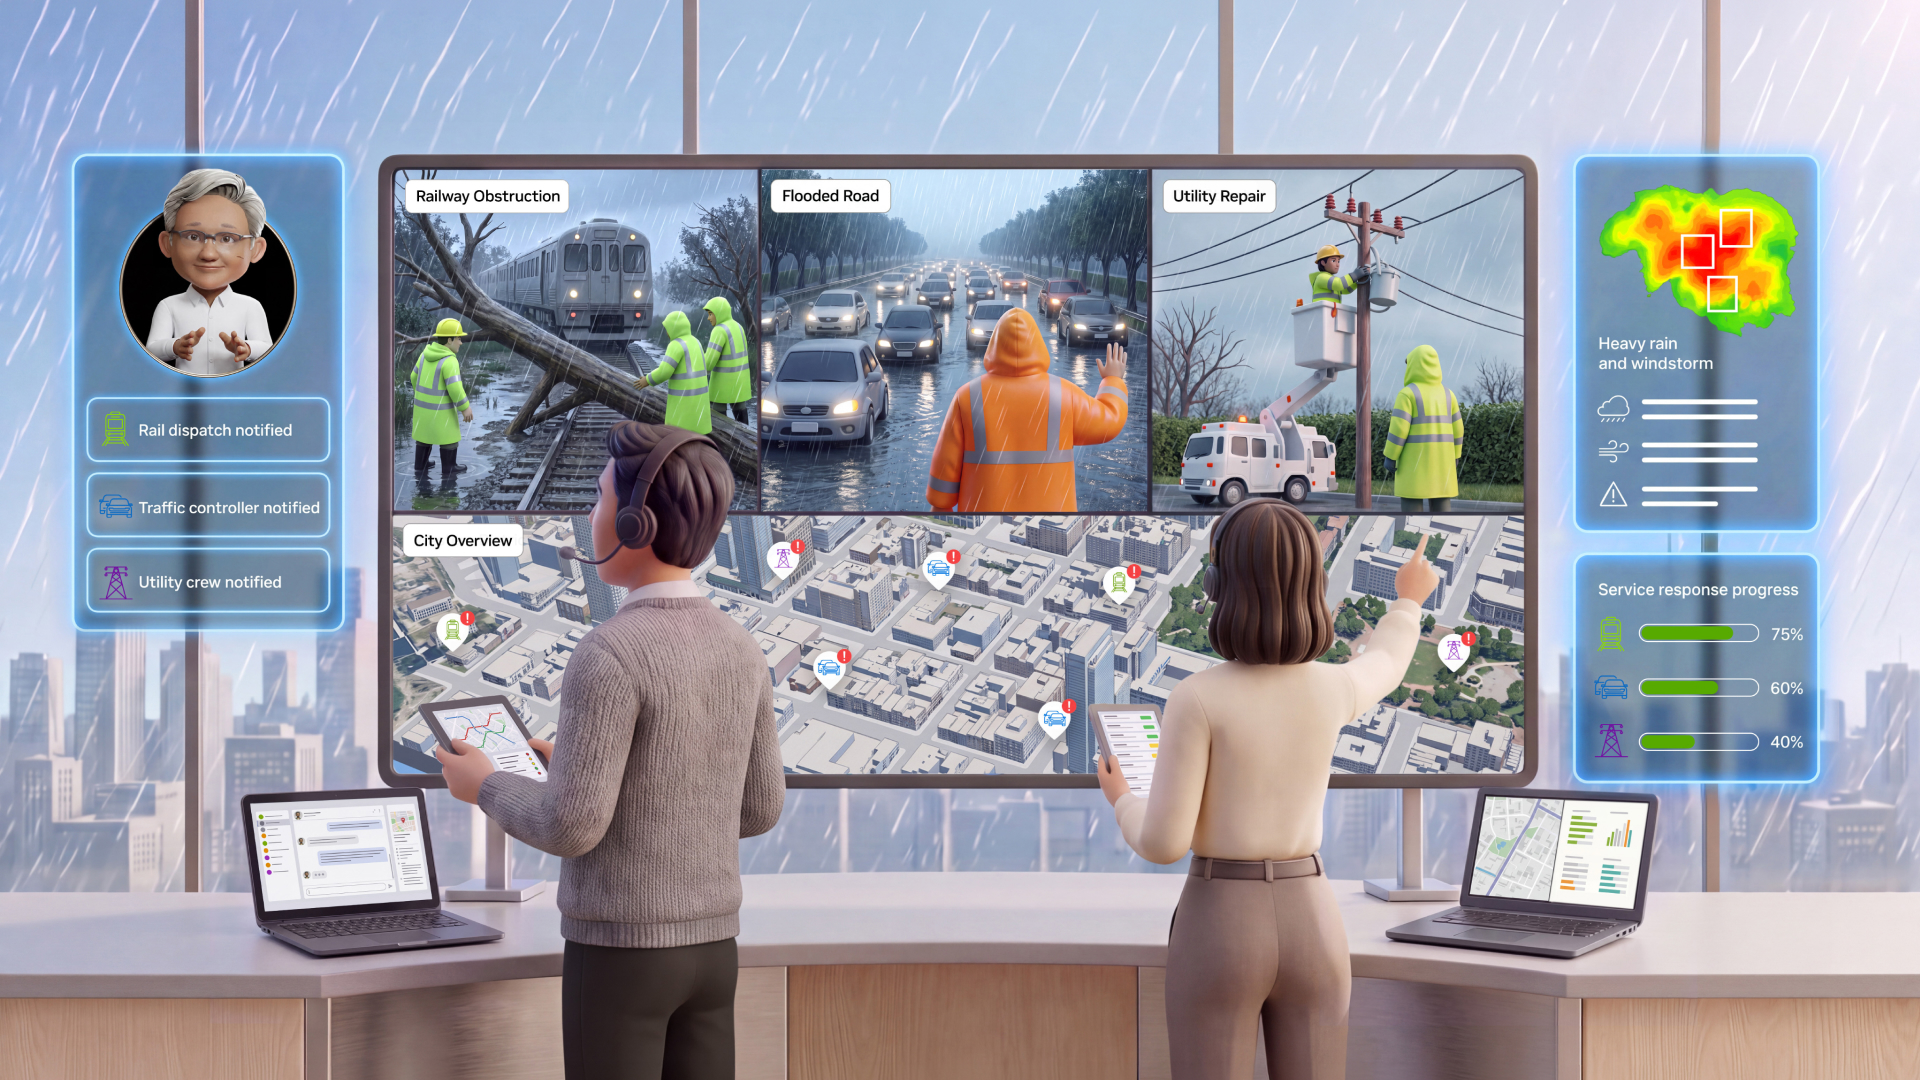
Cities Worldwide Build and Scale AI Services With NVIDIA Physical and Agentic AI

Cities generate enormous amounts of data from cameras, sensors and operational systems, but turning it into useful action — for planning, maintenance and public services — remains a challenge. Physical and agentic AI offer new ways to close that gap, from digital twins for infrastructure planning to vision and service agents, while keeping local governments […]

Cities Worldwide Build and Scale AI Services With NVIDIA Physical and Agentic AI

Rethinking Model Aggregation for Federated Learning with Domain Skew: A Knowledge-Preserving Perspective

arXiv:2611.01893v1 Announce Type: new Abstract: Domain skew challenges federated learning by requiring a shared model to accommodate distinct visual distributions. Domain-specific experts can capture these distributions separately, creating an opportunity to integrate their representations in a unified predictor. We propose Federated Knowledge-Preserving Learning (FKPL), a two-stage framework that combines domain-oriented expert training with prototype-based classifier calibration. First, a one-shot subspace-based clustering procedure groups clients for intra-cluster training. The resulting expert encoders are concatenated and frozen, preserving each learned feature mapping during global integration. Second, clients interpolate their concatenated features with class-matched domain prototypes and upload the resulting virtual features. The server trains a global linear classifier on these features, concentrating classifier optimization at the server after a single feature upload. FKPL achieves average accuracies of 73.01\%, 67.00\%, and 64.51\% on Office-Caltech-10, PACS, and a four-domain subset of DomainNet, respectively. On DomainNet, its cross-domain standard deviation is 7.50 percentage points, the lowest among the evaluated methods. With the same concatenated extractor, prototype-based calibration improves average accuracy over federated classifier training by 9.99 and 14.94 percentage points on Office-Caltech-10 and PACS. These results identify classifier calibration as an effective way to combine preserved domain representations into a global predictor.

Vercel Sandbox with Drives now starts up to 2.4× faster

Vercel has improved the startup speed of sandboxes that use Drives, reducing median creation time from 1.7 seconds to 0.7 seconds and p95 time from 2.2 seconds to 1.6 seconds. The enhancement is automatic for all Drive-using sandboxes, requiring no SDK update or configuration changes, and pricing remains unchanged.

Introducing Vercel Security Review

Vercel introduces Security Review, a new feature in Vercel Agent that automatically scans for vulnerabilities in code changes pushed to connected GitHub repositories. It provides real-time findings via pull request comments, a Security dashboard, and CLI access, with options to auto-fix issues using Vercel Agent or integrate with custom coding agents. The tool checks for logic flaws, enforces team-specific security policies, tracks vulnerabilities across deployments, and supports audit logging for Enterprise users. Available now in public beta for Pro and Enterprise teams, it is free until November 10, 2026.

Intersectional Invariant Learning for Fair Deepfake Detection

arXiv:2610.37881v1 Announce Type: new Abstract: Deepfake detection models achieve high overall accuracy but exhibit large performance disparities across demographic groups, causing some groups to experience substantially higher false-positive rates than others. Existing fairness-aware methods address this by constraining model outputs to equalize group predictions, but do not tackle the underlying feature-level bias. As a result, models may still rely on demographic characteristics, such as skin texture, as indirect cues for detecting manipulated content. To address this problem, we propose Intersectional Invariant Learning (IIL), a framework that improves feature learning rather than only adjusting model outputs. IIL alternates between identifying the most challenging demographic partitio

Timeline and related coverage

Amortized Localized Posterior Inference for Model Calibration with Application to an Ocean Turbulence Closure

arXiv:2610.37731v1 Announce Type: new Abstract: Model discrepancy may prevent a single calibration parameter from reproducing a physical response across the context domain. In addition, uncertainties in observations and contexts affect calibration and must be accounted for and quantified. We construct a family of localized posteriors by weighting observation likelihoods according to their proximity to a target context. Gaussian localization weights incorporate context uncertainty through covariance inflation, with reflection at domain boundaries and an optional correction for uneven context sampling. A conditional normalizing flow approximates the family of posteriors through amortized variational inference. Integrating the localized posteriors under a prescribed context measure gives the

Timeline and related coverage