chDB Durable Layer for agent memory
The chDB Durable Layer keeps agent memory fast to query locally while making its analytical state recoverable across laptops, CI jobs, and short-lived sandboxes.
Search headlines, summaries and articles to connect the dots.
The chDB Durable Layer keeps agent memory fast to query locally while making its analytical state recoverable across laptops, CI jobs, and short-lived sandboxes.
NVIDIA has introduced four new open-weight checkpoints for its Cosmos 3 model family—Cosmos3-Nano-Transfer-Auto, Cosmos3-Nano-Sim-Auto, Cosmos3-Nano-Sim-Transfer, and Cosmos3-Nano-Sim-Bimanual—enabling interactive world simulation and multi-sensor, multi-view driving scene generation. Each model is a post-trained variant of Cosmos 3 Nano with 16B trainable parameters and is based on OpenMDW1.1, allowing commercial and non-commercial use. The checkpoints support applications in robotics and autonomous driving by generating synchronized camera and LiDAR data, enabling streaming simulations, translating simulator controls into photorealistic video, and predicting visual outcomes from robot actions. They are designed to be adapted using custom data and training recipes, with support for offline data generation, causal distillation, and interactive rollouts. Resources include technical reports, demos, and notebooks for inference and adaptation.
Been using this in all my sessions the last months. Opus 5.5 (over MCP) spawns Deepseek flash agents - and codex for audits etc. Very curious to hear what the HN crowd thinks/makes of it. Comments URL: https://news.ycombinator.com/item?id=50383189 Points: 1 # Comments: 0
This is Optimizer, a weekly newsletter sent from Verge senior reviewer Victoria Song that dissects and discusses the latest gizmos and potions that swear they're going to change your life. Opt in for Optimizer here. "How does that make you feel?" I get asked this a lot in therapy. Plenty of life events, big and […]
DEMO PAPER GITHUB HUGGING FACE MODELSCOPE DISCORD To achieve the objective of building an AGI system, the model should be capable of understanding information from different modalities. Thanks to the rapid development of large language models, LLMs are now capable of understanding language and reasoning. Previously we have taken a step forward to extend our LLM, i.e., Qwen, to more modalities, including vision and audio, and built Qwen-VL and Qwen-Audio. Today, we release Qwen2-Audio, the next version of Qwen-Audio, which is capable of accepting audio and text inputs and generating text outputs.
Article URL: https://nickprotop.github.io/cxagent/ Comments URL: https://news.ycombinator.com/item?id=50368887 Points: 1 # Comments: 0
Article URL: https://github.com/watscho/chat-gpt-telegram-bot Comments URL: https://news.ycombinator.com/item?id=50377737 Points: 1 # Comments: 0
API Documentation (Chinese) HuggingFace Demo ModelScope Demo Introduction After the release of Qwen2.5, we heard the community’s demand for processing longer contexts. In recent months, we have made many optimizations for the model capabilities and inference performance of extremely long context. Today, we are proud to introduce the new Qwen2.5-Turbo version, which features: Longer Context Support: We have extended the model’s context length from 128k to 1M, which is approximately 1 million English words or 1.
Article URL: https://github.com/biolend83/tubehaus Comments URL: https://news.ycombinator.com/item?id=50363507 Points: 1 # Comments: 0
Tech leaders are flaunting how out of touch they are when they brag about using AI to connect with their families.

South Korea’s financial institutions have been hit by another wave of cyberattacks, highlighting the growing risk of AI-driven hacking in Asia.

Nvidia Corp. today released a leaderboard-winning open artificial intelligence model for multilingual audio transcription and translation, along with an open data pipeline for fine-tuning Nemotron 3.5 Transcribe. Traditional transcription AI models follow a workflow that detects speech, transcribes it, identifies and labels different speakers, then answers questions about the transcription. Transcribe does all of this […] The post Nvidia releases all-in-one adaptable Nemotron 3.5 audio transcription and translation model appeared first on SiliconANGLE.
NVIDIA RTX Spark powers thin and light laptops built for everything that developers, creators and gamers do. RTX Spark laptops are now available from ASUS, Dell, HP, Lenovo, Microsoft and MSI. These powerful systems combine an NVIDIA Blackwell RTX GPU and an NVIDIA Grace CPU in a single superchip with up to 128GB of unified […]
Nvidia just released a free speech-to-text model that can transcribe up to 40 languages, but it only works on recordings, not live audio, so it’s a big step for meeting and medical transcription tools while still leaving real-time use to rivals like ElevenLabs.

NVIDIA Nemotron 3.5 Transcribe and Granary v2: Intelligent Multilingual Transcription You Can Prompt and Adapt
Katelyn Lesse and Angela Jiang on Opus 5.5, the Claude Platform, and the engineering behind AI agents.
Checkr gave its AI agent a structured dbt context layer, cutting a support-metric investigation from hours to minutes.
Why conversational analytics stalls and the data fundamentals that make it reliable.
A government watchdog is considering a probe into the Home Office’s use of ChatGPT technology to process asylum claims amid concerns over the tools’ accuracy and secrecy surrounding their use.
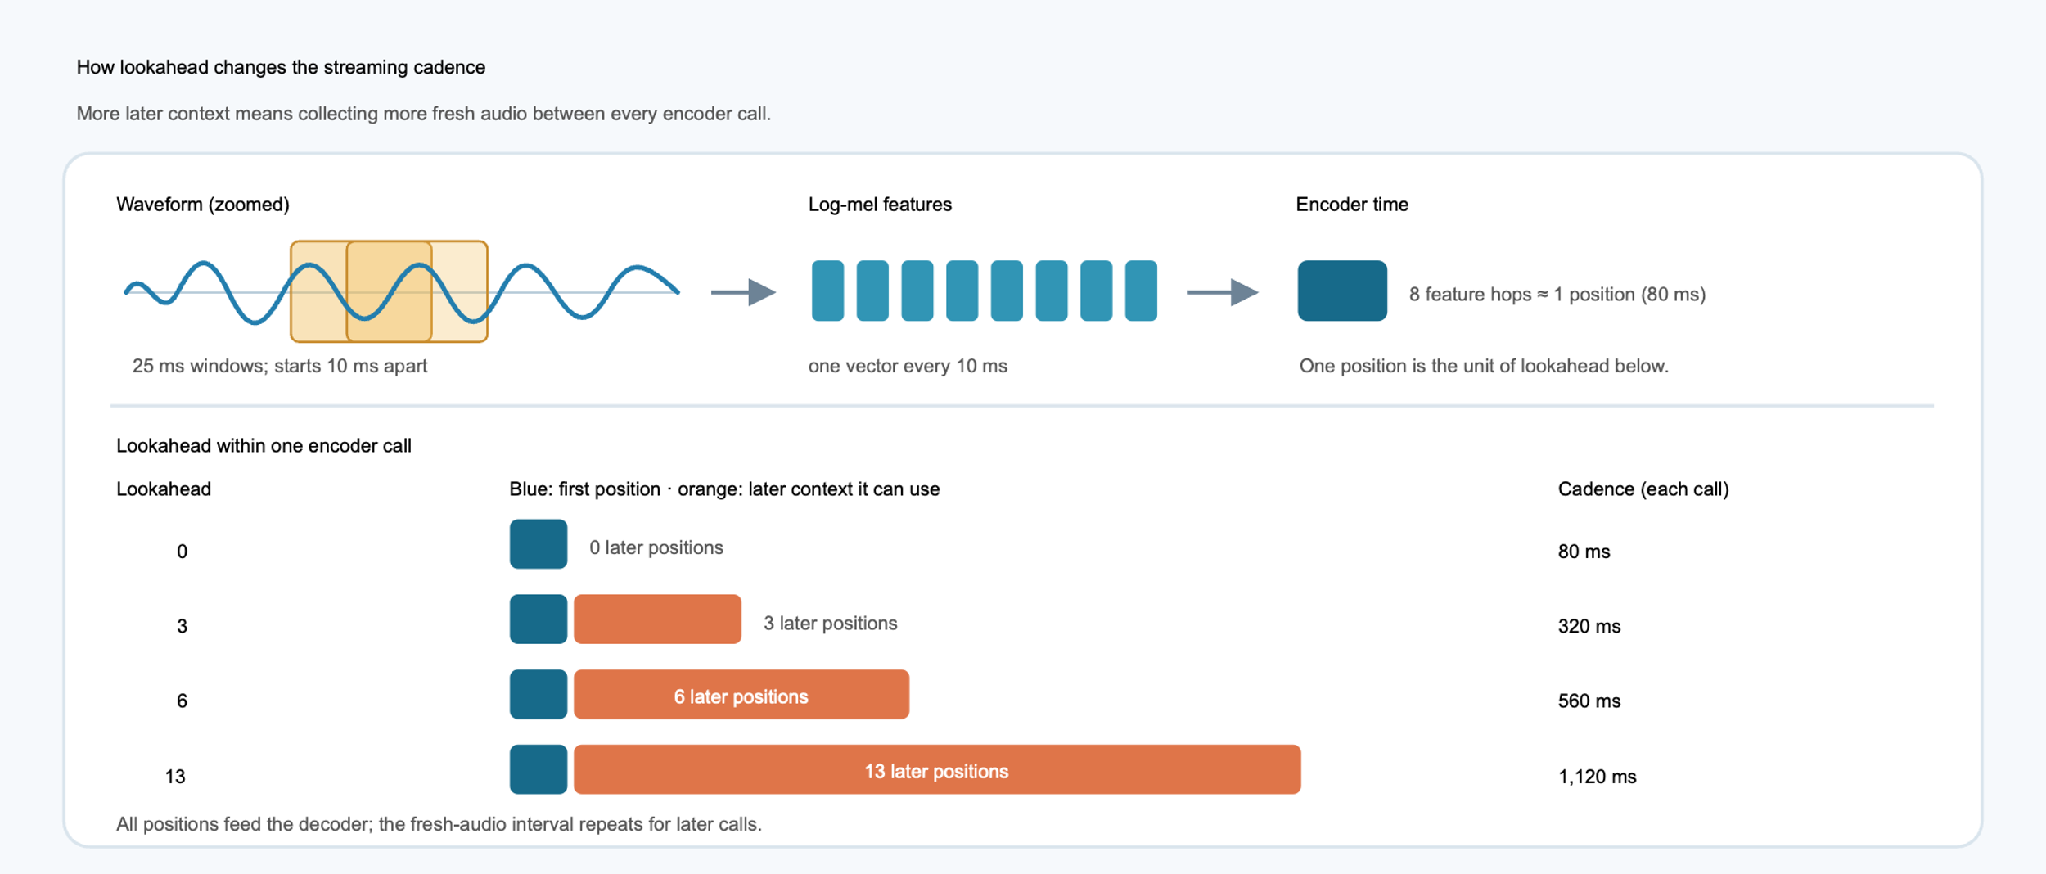
When you’re speaking to a device, you expect text to appear as you talk. That makes streaming automatic speech recognition (ASR) a different challenge from batch transcription, where the model... The post Optimizing Streaming Speech Recognition on Arm® Edge Devices with ExecuTorch appeared first on PyTorch.