Skip to content
AI NEWS JOURNAL
AI, IN PERSPECTIVE

Search AI news

Search headlines, summaries and articles to connect the dots.

Newest first

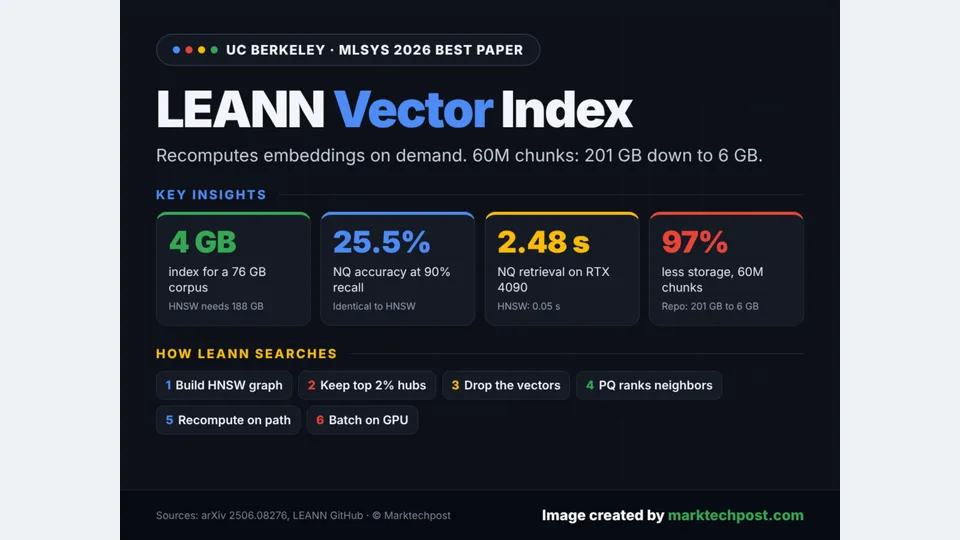
Faster Retrieval for Better, More Efficient RAG

Maximum inner product search (MIPS) sits at the core of recommendation systems, search, and retrieval-augmented generation (RAG). Given a query vector, MIPS systems search within a database of millions of candidate key vectors for the one that best matches the query. The original data point associated with that best-matching key is then used to handle the query: in RAG, the document that is best suited to answer the question is typically prefixed to the query. As the number of keys grows to millions and vector dimensions reach thousands, the computational cost of running an exhaustive…

From Visual Matching to Textual Conditioning: Cross-Domain Few-Shot Segmentation via Reference Inversion

arXiv:2611.04084v1 Announce Type: new Abstract: Cross-Domain Few-Shot Segmentation (CD-FSS) aims to segment objects from unseen domains using only a few annotated references. Recent Segment Anything Model (SAM)-based methods have advanced CD-FSS, yet their reference-target visual matching is highly sensitive to target appearance variations. SAM3 introduces text-conditioned segmentation, enabling natural-language descriptions to guide segmentation across target images, but directly using the category name as the condition still yields unstable performance under severe domain shifts. We propose Reference Inversion for SAM3 (RI-SAM3) that leverages SAM3's large-scale vision-language pre-training to learn suitable textual tokens for each target category. RI-SAM3 comprises three core designs: (i) Bi-level Reference Inversion that learns complementary tokens before and after the frozen text encoder: the former remain anchored in SAM3's text space while the latter represent the category more flexibly; (ii) Layer-adaptive Textual Conditioning combines these tokens differently as object queries evolve across decoder layers; and (iii) Presence-aware Confidence Supervision that jointly supervises query confidence and target presence for reliable predictions. With SAM3 frozen, RI-SAM3 optimizes around 12K parameters only per category and it efficiently segments each target in a single forward pass with reusable textual conditioning without per-sample reference-target visual matching. Extensive experiments over multiple widely adopted benchmarks show that RI-SAM3 achieves superior performance consistently in CD-FSS tasks, together with strong robustness, efficiency, and generalization.

Geometric Refinement and Distributional Alignment for Sim2Real Roadside LiDAR Detection

arXiv:2611.03936v1 Announce Type: new Abstract: We describe our approach to the LUMPI track of the UrbanTwin Sim2Real LiDAR Challenge, in which a 3D object detector must be trained exclusively on synthetic data and evaluated on unseen real roadside LiDAR, while the synthetic point clouds are simultaneously scored for distributional realism. Our final entry scores 0.4793 combined, from a detection mAP of 0.1333 and a realism score of 0.9126. Our contribution is not a new architecture. Working from a PointPillars baseline, we obtained most of our gains from three sources. First, a diagnosis that small object failure in roadside LiDAR is a localisation problem rather than a detection problem, which led to a parameter free geometric refinement worth 86 percent relative on pedestrian AP. Second, an audit of our own post processing which revealed that a shipped rule was destroying valid predictions, the repair of which produced our single largest detection gain at 335 percent relative on the Van class. Third, treating the realism metrics analytically rather than as a black box, which showed that one of the four components is a closed form function of nine summary statistics. We also report an experimental methodology that we believe is the more transferable result. Because mean AP decomposes into independent per class terms, a single submission can carry several mutually controlled experiments, and a submission assembled entirely from previously measured components has a score that is known before it is sent. We predicted our final score to four decimal places prior to submission. We report negative results at equal length, and give a full account of data provenance and compliance in Section 8, including a full account of every mechanism contributing to the submitted score.

Artifact Distillation: Training-Free Transfer from Frontier to Small Language Models

arXiv:2610.37680v1 Announce Type: new Abstract: Closing the gap between frontier and smaller language models is usually approached by distillation: fine-tuning the small model (student) on a frontier model's (teacher) outputs, which binds transfer to training compute and leaves the transferred knowledge largely opaque. We propose Artifact Distillation: a teacher solves training instances and externalizes its problem-solving procedure into an artifact bank that a student queries at inference time, with no gradient updates. Across four LiveBench tasks, a bank written by Claude Opus 4.5 lets Claude Haiku 4.5 outperform unaided Claude Sonnet 4.5 on spatial reasoning (0.707 vs. 0.647) at 60% of its cost, and reach Sonnet 4.5's level on table joining at 89% of its cost. The same raw bank raises

Timeline and related coverage

FinLLM-KG: Knowledge Graph-Enhanced LLMs for Financial Sentiment Analysis in Algorithmic Trading

arXiv:2610.36083v1 Announce Type: new Abstract: Recent advances in Generative AI have substantially improved financial sentiment analysis through post-trained financial large language models (LLMs). However, existing approaches remain confined to predicting the sentiment of each article in isolation and operate as black boxes, which limits contextual understanding and hinders deployment in high-stakes financial decision-making. To this end, we introduce FinLLM-KG, a model-agnostic framework that combines causal LLMs with a financial knowledge graph, in order to inject temporally grounded, company-level knowledge from SEC 10-K filings at inference time, without updating model weights. Within FinLLM-KG, context is supplied either as a natural-language company profile or as a small set of rel

Timeline and related coverage

AK_QMUL at ArGuard Shared Tasks: A Single Fine-Tuned JAIS for Arabic Harmful-Prompt Detection

arXiv:2610.36360v1 Announce Type: new Abstract: We present AK_QMUL's submissions to the ArGuard-2026 shared tasks on Arabic harmful-prompt detection: a binary safe/unsafe task (B1) and a seven-way harm-domain task (B2). Both submissions use one backbone -- JAIS-6.7B fine-tuned with 4-bit QLoRA and a linear classification head over its last-token representation. For B1 we train a four-way head that factors the label by dialect register {safe, unsafe} x {MSA, other}, we augment the training fold with MSA prompts from AraSafe, and decode with a plain argmax to score safe/unsafe. For B2 we fine-tune the same backbone as a seven-way classifier and average the softmax outputs of five random seeds. Both submissions ranked first on their track, with macro-F1 0.984 on B1 and 0.790 on B2. We report

Timeline and related coverage

CONCUR: Concordant Auxiliary Rewards for Multi-Task, Multi-Reward Reinforcement Learning

arXiv:2610.36437v1 Announce Type: new Abstract: When a Large Language Model (LLM) is trained with Reinforcement Learning (RL) on multiple tasks, a task's primary reward can gate auxiliary rewards such as a length reward: on a failing response, an auxiliary cannot exceed the primary. However, group-relative advantage estimators treat a gated auxiliary like any other component, so it can reverse the primary's order, and at the primary's ceiling only auxiliaries order responses. Keeping gated auxiliaries hurts some tasks, while dropping them hurts others. We propose CONCUR, an advantage estimator that replaces the standardized scores of each gated auxiliary with the closest scores that satisfy two conditions: responses with higher primary rewards cannot receive lower scores, and responses at

Timeline and related coverage

Beyond IceBERT: Open-Data ModernBERT Encoders for Icelandic from 12M to 1B Parameters

arXiv:2610.36230v1 Announce Type: new Abstract: IceBERT, the reference encoder for Icelandic, found that a cleaned web crawl is enough to train a strong model and that starting from a multilingual model can help on some tasks. We revisit both findings with the ModernBERT architecture. We train Icelandic encoders from 12M to 1B parameters on 9B tokens of open data, and rerun IceBERT's benchmarks and five newer tasks for 30 encoders under one protocol with confidence intervals. Our 1B model trained from scratch, to our knowledge the first monolingual Icelandic encoder of that size, is significantly better than IceBERT on all eleven tasks; warm-started from the English Ettin encoder of the same shape, it has the best score of all encoders on every task we rank. Because our model shapes match

Timeline and related coverage

Is Token Confidence Just Chain Length? A Signal-Processing Audit of Reasoning Traces

arXiv:2610.36709v1 Announce Type: new Abstract: Reasoning language models answer math problems by writing long chains of thought, and sampling many chains per problem and taking a majority vote raises accuracy at a large cost in generated text. A popular way to cut that cost scores each chain by the model's confidence in each token it writes, where a token is a word or part of a word. The method averages this confidence over a sliding window of 2048 tokens and keeps or stops chains based on the lowest average. We treat the confidence, recorded token by token, as a signal in the sense of audio or radio, and examine the method with standard signal-processing tools such as spectral analysis and statistical tests for detecting a sudden change. We sampled 16 chains for each of 500 problems from

Timeline and related coverage

EKT-Router: Expert-Evidence Alignment for Embodied Vision-Language Models

arXiv:2610.33044v1 Announce Type: new Abstract: Embodied vision-language models must answer questions from partial, evolving observations. Their success depends on both the reasoning capability selected and the evidence available to it. Expert routers adapt internal computation, while tool-augmented systems acquire external evidence; choosing these independently can leave a suitable expert without the evidence it needs. We introduce EKT-Router, a bounded framework that jointly selects a capability expert, optional knowledge, and perceptual tools. Outcome-derived signatures represent the overlapping strengths of General, Spatial Reasoning, and Spatiotemporal experts. A joint utility scores complete expert-evidence routes under a call budget. After acquisition, a packet verifier admits valid

新闻源配图 · arXiv cs.CV
Timeline and related coverage

Multi-Agent Retrieval-Augmented Causality Assessment (MARCA) of Individual Case Safety Reports in Pharmacovigilance

arXiv:2610.33279v1 Announce Type: new Abstract: Introduction: Increasing volumes of individual case safety reports (ICSRs) challenge expert-led causality assessment in pharmacovigilance. We developed MARCA (Multi-Agent Retrieval-Augmented Causality Assessment), a four-agent framework for Naranjo-based assessment, and evaluated agreement with human experts and exploratory differences between non-RAG and RAG-labelled scores. Methods: MARCA combined scientific literature retrieval, drug-label assessment, objective-evidence classification, and clinical causality reasoning using Gemini 2.5 Pro and DeepSeek-V3.2. Agent-generated rationales informed human-assisted scoring. A consensus expert reference standard covered 215 ICSRs and 1,562 drug-event combinations (DECs) from FAERS (Q1-Q2 2025). Agr

Timeline and related coverage

When to Stop Penalizing Actions? Martingale GRPO for VLA Reinforcement Learning

arXiv:2610.32431v1 Announce Type: new Abstract: A failed vision-language-action (VLA) rollout does not imply that every action contributed to failure. Yet in group-relative policy optimization (GRPO), a single trajectory-level advantage is assigned to all actions in a rollout. Potentially useful recovery attempts can thus be penalized alongside the errors they aim to correct. Ideal stopping conditions for failure feedback are characterized using success-probability and policy-score martingales. At these stops, the removed gradient contribution has zero conditional expectation given the retained information. Truncation therefore preserves the expectation of a reference GRPO group-gradient estimator and can reduce its covariance. One such stop occurs when the conditional probability of succe

Timeline and related coverage

POS-Signature Demonstration Retrieval for In-Context Dependency Parsing

arXiv:2610.31966v1 Announce Type: new Abstract: Demonstrations for in-context learning are often retrieved by semantic similarity, which may be a poor proxy for relevance in structured prediction. We study demonstration selection for Universal Dependencies parsing with a POS-signature policy that represents sentences with weighted part-of-speech statistics and retrieves three length-compatible, gold-parsed examples from the labeled training split. We evaluate two open-weight language models without fine-tuning on all 2,077 sentences of the UD English Web Treebank test set, comparing the policy with shot- and format-matched fixed and semantic three-shot baselines, as well as zero-shot, chain-of-thought, and critique-refinement systems. POS-signature retrieval yields the highest labeled atta

Timeline and related coverage

Spatial Heuristic Strategy based Diffusion Reinforcement Learning for Online 3D Bin Packing

arXiv:2610.32241v1 Announce Type: new Abstract: Traditional heuristic methods have accumulated mature experience in core objectives, such as space utilization and layout compactness of 3D bin packing, relying on artificially designed rule-based logic. However, they exhibit obvious limitations in generalization ability and adaptability to dynamic scenarios. Diffusion reinforcement learning, which integrates the spatial search capability of reinforcement learning and the data distribution modeling capability of diffusion learning, has achieved certain progress in action distribution modeling and decision compliance constraints. Nevertheless, there remain issues including insufficient perception of the spatial topological structure in 3D bin packing and limited layout optimization capability.

Timeline and related coverage

New research reveals that open-book assessments primarily measure reading behavior rather than knowledge retention.

An arXiv paper published on October 24, 2026 (2610.31017v1) points out that, in document-level LoRA adapter evaluations, open-book scoring relies heavily on the model’s ability to read on the fly, rather than on whether the adapter has truly encoded knowledge specific to the document; random adapters can reproduce 82% of the performance advantage of expert adapters on open-book tasks, but on cloze tasks involving unstructured text, they only replicate 2%—statistically indistinguishable from zero.

Mostly Reading: What Open-Book Scores Measure in Document-Level LoRA Adapters

Why it matters:This study, through systematic controlled experiments—comprising 150 Wikipedia articles, the Llama-3.1-8B-Instruct model, and a two-task comparison—reveals the fundamental limitations of the current open-book evaluation paradigm: it fails to effectively distinguish between “reading” and “remembering,” posing methodological challenges to the practical utility of knowledge-editing and retrieval‑oriented adapters. The paper also reports four silent errors that lead to “clean yet incorrect results,” highlighting risks to reproducibility.

Timeline and related coverage

The study proposes a new evaluation method and model to address annotation disagreements in identifying unstated arguments (enthymemes) within politically contentious discourse.

This paper, based on tweet data related to vaccination and immigration—each tweet independently annotated by five raters—finds that existing fine-tuned models consistently achieve an F1 score of around 0.67 on the enthymeme detection task. To address this, the authors propose abandoning the single-label evaluation paradigm in favor of a new metric that captures the distribution of annotators’ opinions, and they design a model capable of directly predicting this distribution, thereby better capturing human judgmental divergence without compromising the F1 score.

Interpretive Variation and Discourse Structure in Detecting Enthymemes in Controversial Political Discourse

Why it matters:The paper squarely confronts the long-neglected reality in NLP that “annotator disagreement is an essential characteristic”—particularly in politically sensitive contexts, where identifying enthymemes relies heavily on subjective reasoning. Its methodological shift—from point prediction to distributional prediction—and its empirical demonstration of the limitations of discourse‑structural analysis carry clear implications for the design of content‑moderation systems: models trained on majority‑vote criteria may systematically overlook implicit arguments that require deep contextual inference.

Timeline and related coverage
