Skip to content
AI NEWS JOURNAL
AI, IN PERSPECTIVE

Search AI news

Search headlines, summaries and articles to connect the dots.

Newest first

Adaptive Scheduling Pipeline for Multi-Instance Asynchronous Reinforcement Learning

arXiv:2611.08864v1 Announce Type: new Abstract: We present the Adaptive Scheduling Pipeline (ASP), an offline rollout scheduler for multi-instance asynchronous reinforcement learning (RL) of large language models (LLMs). ASP jointly reduces three sources of rollout underutilization - padding bubbles from intra-minibatch length heterogeneity, skewness bubbles from long-tail outputs, and sorting bubbles from fluctuations in training-queue occupancy induced by length-sorted dispatch - through a single offline preprocessing pass. This enables efficient multi-instance rollout that overcomes the early scaling plateau of single-instance inference while smoothing the arrival of generated samples at the trainer. We integrate the scheduler into an asynchronous architecture that decouples rollout from training while keeping policy lag observable and bounded. Complete ASP improves end-to-end throughput by up to 3.22 times and reduces iteration time by up to 76.8% relative to MindSpeed-RL, while reducing iteration time by up to 62.5% relative to verl. Within ASP, scheduling reduces mean iteration time by 10.9%. ASP also scales more robustly with additional generation resources than these baselines and shows no visible convergence degradation in the measured bounded-lag regime. ASP has since been used in an internal telecom-domain RL post-training workflow, reducing the reported training period from more than three months to about two months and producing a domain-enhanced model for knowledge answering and tool calling.

FinEvolveKG: Controlled and Attributable Prompt Evolution for Financial Knowledge Graph Construction

arXiv:2611.08643v1 Announce Type: new Abstract: Financial institutions construct knowledge graphs (KGs) from shared SEC 10-Ks to serve risk analysis, portfolio management, and investment research, whose analytical needs differ. Extraction must adapt without fragmenting shared grounding, typing, and temporal rules. Hand-authored persona prompts and fine-tuning add cost. Weight-free prompt optimization offers an alternative, but unconstrained evolution of a monolithic prompt can rewrite shared rules alongside persona guidance, obscuring changes and complicating review. We introduce FinEvolveKG, a KG-construction harness separating reusable general and persona-policy blocks and mechanically confining GEPA, a reflective prompt optimizer, to the designated block. During persona adaptation, the approved general block remains byte-stable and every optimizer edit is localized to a separately versioned persona policy. A dual objective balances generic temporal-KG quality with persona-relevant facts, motifs, and multi-hop connectivity. We evaluate five mutation scopes on ticker-disjoint 10-K splits, with three seeds for the persona-conditioned arms (v3-v5) across three personas. On the three-seed mean, the complete two-stage block-constrained workflow (v4) improves over the frozen prompt baseline (v1) by 19.4-30.9% and over the tested unconstrained full-prompt workflow (v5) by 2.2-6.4%, leading v5 on both objective components and winning all nine paired-seed comparisons with the lowest seed variance in every persona. Without further optimization, v4 also exceeds v5 across all evaluated out-of-distribution (OOD) shifts. An SME audit supports using the generated triplets as ground truth; a blinded two-SME audit favors v4 over v5 in 70.1% of contrast-enriched judgments. These results show that mechanically attributable evolution can coexist with strong empirical performance, without attributing the gains causally to the boundary.

Guardrail Erosion in Domain Fine-Tuned Large Language Models: A Paired Audit of Knowledge-Centric Abstention in Biomedical LLMs

arXiv:2611.08780v1 Announce Type: new Abstract: The number of domain fine-tuned models, particularly in the biomedical domain, is rapidly expanding. Fine-tuning promises high-performing models at a fraction of the cost of training a base model, but it can also produce unintended behavioral changes. Multiple studies have shown that safety guardrails can erode with fine-tuning, yet large-scale studies across model architectures, data mixtures, and fine-tuning methodologies remain limited. Where prior work in this space has studied value-centric refusal, this work focuses on knowledge-centric abstention. We audit 25 biomedical domain fine-tuned large language models against 11 paired base checkpoints on MedAbstain and ClinDet-Bench to evaluate the impact of fine-tuning on knowledge-centric abstention. We find that defined appropriate abstention measured by these benchmarks, already low in base models (median 8.3% on MedAbstain), falls further after fine-tuning (median 4.2%, decreasing in 21 of 25 pairs on MedAbstain), and that the magnitude and direction of change are heterogeneous across pairs. These results motivate fine-tuning methods that improve domain-specific capability while preserving appropriate caution.

University of Utah retains operational sovereignty as Redtail expands research access

Operational sovereignty gives universities authority over how shared computing resources are allocated, managed and secured. The University of Utah’s Redtail AI factory supercomputer brings advanced computing capabilities to a statewide community. Supporting researchers, students, administrators and external partners through that infrastructure requires more than computing capacity, according to Manish Parashar (pictured), chief AI officer of […] The post University of Utah retains operational sovereignty as Redtail expands research access appeared first on SiliconANGLE.

Augmentation with Reinforcement Transformation for Low-textured Scientific Sketch Image Retrieval

arXiv:2611.05408v1 Announce Type: new Abstract: Low-textured sketch images are widely used in scientific applications, including wildlife conservation, archaeological illustration, and forensic composites. Learning from and retrieving such images is challenging because they lack detailed surface textures and visual variations commonly exploited by modern deep learning models. This paper proposes Augmentation with Reinforcement Transformation (ART) to fine-tune pretrained models to learn effective representations for accurate sketch image retrieval. Our key observation is that sketches are particularly sensitive to image transformations, such as rotation, flipping, zooming, and stretching. While some transformations preserve their structural integrity, others may introduce distortions that hinder representation learning. Instead of randomly choosing transformations to construct fine-tuning views, ART formulates augmentation selection as a multi-armed bandit (MAB) problem, where transformations are treated as arms and their effectiveness is continuously evaluated through rewards. This enables ART to adaptively construct reward-guided view banks before self-supervised fine-tuning; the subsequent representation loss does not feed back to ART. On Florida manatee sketches provided by Mote Marine Laboratory, ART achieves 71.40% average Top-1 accuracy for transformed-scar retrieval, compared with 68.83% for random augmentation selection, and 55.84% for location-aware sketch retrieval, compared with 18.18% for frozen CLIP.

Faster Retrieval for Better, More Efficient RAG

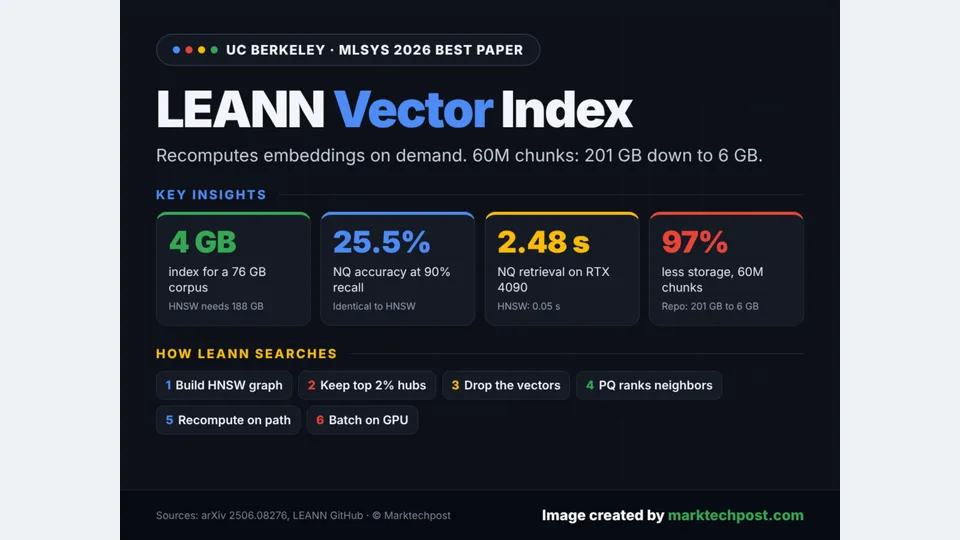
Maximum inner product search (MIPS) sits at the core of recommendation systems, search, and retrieval-augmented generation (RAG). Given a query vector, MIPS systems search within a database of millions of candidate key vectors for the one that best matches the query. The original data point associated with that best-matching key is then used to handle the query: in RAG, the document that is best suited to answer the question is typically prefixed to the query. As the number of keys grows to millions and vector dimensions reach thousands, the computational cost of running an exhaustive…

Structured Priors: Towards an algebra of component priors for prior-data fitted networks

arXiv:2611.04056v1 Announce Type: new Abstract: Prior-data fitted networks are typically trained using synthetic data generated by a single, manually constructed generator. In cases where such a generator combines multiple components, e.g., in TabPFN, Mitra, or TabICLv2, this is achieved through a mixture using manually specified weights, the impact of which on the network only becomes apparent after pre-training. Instead of such a hand-built generator, this work proposes a structured prior: a small set of named component priors, linked by operators whose algebraic properties are formally proven and whose influence on the trained network has been validated. Within a measure-theoretic framework, the operators of mixture, convolution, amplitude scaling, local transform, and projection are defined. Their governing laws are proven. These operators are implemented in the macl2l software package. Experiments demonstrate that the implemented generators reproduce the identities within the resolution of a permutation test. Furthermore, it is shown that trained networks obey the distributive law; that a mixed prior composed of small components performs as well as or better than any individual component in seven out of eight open regression benchmarks; and that on two of these tables a structured prior reaches, with a ninth of the data budget, an error that a generic random-function prior does not reach even with the full budget. A theorem on model averaging demonstrates that networks trained on individual components constitute the Bayes predictor for the mixture, provided that the component networks are themselves the Bayes predictors for their respective priors. However, the pre-registered test of this averaged predictor with trained component networks failed, because the networks identify the generating component too rarely. The paper proposes a research program focused on the algebra of structured priors for prior-data fitted networks.

Geometric Refinement and Distributional Alignment for Sim2Real Roadside LiDAR Detection

arXiv:2611.03936v1 Announce Type: new Abstract: We describe our approach to the LUMPI track of the UrbanTwin Sim2Real LiDAR Challenge, in which a 3D object detector must be trained exclusively on synthetic data and evaluated on unseen real roadside LiDAR, while the synthetic point clouds are simultaneously scored for distributional realism. Our final entry scores 0.4793 combined, from a detection mAP of 0.1333 and a realism score of 0.9126. Our contribution is not a new architecture. Working from a PointPillars baseline, we obtained most of our gains from three sources. First, a diagnosis that small object failure in roadside LiDAR is a localisation problem rather than a detection problem, which led to a parameter free geometric refinement worth 86 percent relative on pedestrian AP. Second, an audit of our own post processing which revealed that a shipped rule was destroying valid predictions, the repair of which produced our single largest detection gain at 335 percent relative on the Van class. Third, treating the realism metrics analytically rather than as a black box, which showed that one of the four components is a closed form function of nine summary statistics. We also report an experimental methodology that we believe is the more transferable result. Because mean AP decomposes into independent per class terms, a single submission can carry several mutually controlled experiments, and a submission assembled entirely from previously measured components has a score that is known before it is sent. We predicted our final score to four decimal places prior to submission. We report negative results at equal length, and give a full account of data provenance and compliance in Section 8, including a full account of every mechanism contributing to the submitted score.

A Comparative Study of Parallel Implementations of Short-Time Fourier Transform

arXiv:2610.38069v1 Announce Type: new Abstract: The short-time Fourier transform (STFT) computes the Fourier transform of a short-duration window of a longer signal, which characterizes how a frequency changes over time. While the Fourier transform algorithms, particularly the Fast Fourier Transform (FFT) algorithm, has been well developed to take advantage of parallel computing, there is limited work on understanding the performance of parallel short-time Fourier transform algorithms. In this study, two parallel short-time Fourier transform algorithms, one is FFT-based and the other a quasi-parallel feedforward algorithm, are implemented and analyzed in comparison with each other. It is found that while the quasi-parallel algorithm outperforms in runtime under low concurrency settings, th

Timeline and related coverage

DistOptimize: Automatic Optimization of Distributed Protocols

arXiv:2610.39017v1 Announce Type: new Abstract: Distributed consensus and consistency protocols are difficult to reason about yet foundational to the cloud; as such, they often undergo a rigorous proof and formal verification process before deployment. The same level of rigor is rarely applied to protocol modifications, which occur frequently in production and threaten to compromise safety. In this paper, we eliminate the risk of safety violations from manual modifications by presenting an automatic optimizer for distributed protocols: DistOptimize. DistOptimize adapts throughput optimizations from academic languages to frameworks used in production, verifying the correctness of the rewrites in Rocq and automating their application through a combination of calibration and ILP-based search

Timeline and related coverage

Supervised Fine-Tuning for Reasoning Large Language Models: A Survey

arXiv:2610.37681v1 Announce Type: new Abstract: Large reasoning models have recently demonstrated remarkable capabilities in solving complex tasks, where supervised fine-tuning (SFT) on long chain-of-thought data serves as a crucial foundation for eliciting and enhancing their reasoning abilities. Despite rapid progress in both improving and analyzing reasoning-oriented SFT, the field still lacks a systematic survey that consolidates its fast-growing literature. To fill this gap, we present a comprehensive review of recent advancements in reasoning SFT, examining the literature through the dual lenses of methodological design and analytical investigation. First, we review methodological improvements across the SFT pipeline and categorize them into data-centric approaches and algorithm-cent

Timeline and related coverage

TRACEs: Fine-Grained Embedded Provenance for Distributed Scientific Workflows

arXiv:2610.39981v1 Announce Type: new Abstract: Large-scale scientific workflows run on distributed HPC resources, making it hard to explain how scientific data products are generated and why similar workflow executions can yield very different results. Existing systems usually focus on either distributed workflow execution or provenance management and rarely treat fine-grained provenance as an intrinsic property of distributed scientific data artifacts. We present TRACEs (Traceable Runtime for Advanced Containerized Executions), a provenance architecture for distributed containerized scientific workflows that embeds data lineage and execution context directly in every generated data artifact. By decoupling provenance from workflow orchestration, TRACEs generalizes artifact-centric provena

Timeline and related coverage

Beyond IceBERT: Open-Data ModernBERT Encoders for Icelandic from 12M to 1B Parameters

arXiv:2610.36230v1 Announce Type: new Abstract: IceBERT, the reference encoder for Icelandic, found that a cleaned web crawl is enough to train a strong model and that starting from a multilingual model can help on some tasks. We revisit both findings with the ModernBERT architecture. We train Icelandic encoders from 12M to 1B parameters on 9B tokens of open data, and rerun IceBERT's benchmarks and five newer tasks for 30 encoders under one protocol with confidence intervals. Our 1B model trained from scratch, to our knowledge the first monolingual Icelandic encoder of that size, is significantly better than IceBERT on all eleven tasks; warm-started from the English Ettin encoder of the same shape, it has the best score of all encoders on every task we rank. Because our model shapes match

Timeline and related coverage