
Learner collaborates with MIT peers to develop book of AI insights
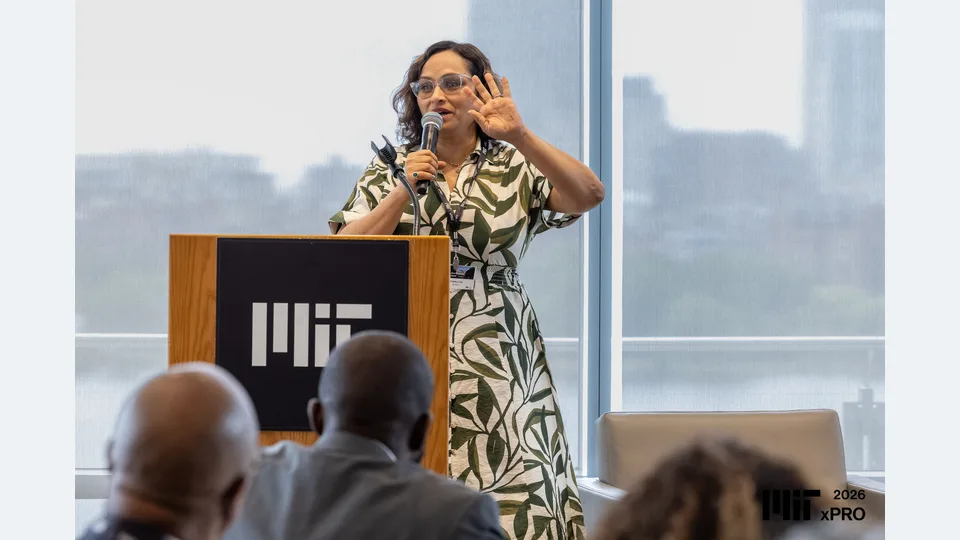
Prabha Jha used her experience with MIT Open Learning’s program for senior executives to develop AI solutions for her employer, Verizon, and to write a book.
Search headlines, summaries and articles to connect the dots.
Prabha Jha used her experience with MIT Open Learning’s program for senior executives to develop AI solutions for her employer, Verizon, and to write a book.
arXiv:2610.32189v1 Announce Type: new Abstract: Unsupervised multivariate time series anomaly prediction (AP) aims to estimate future anomaly risks from current observations, providing early-warning signals for proactive intervention and maintenance in complex systems. Existing unsupervised AP methods follow a perturbation-based paradigm, where predefined or random perturbations are injected into historical windows to simulate abnormal future evolution. However, these methods share perturbations across different variables and contexts, and learn deterministic history-to-future evolution. In reality, anomaly evolution is variable- and context-dependent: the same perturbation may be amplified into abnormal future dynamics in one variable or context, while being absorbed as normal fluctuation
arXiv:2610.32104v1 Announce Type: new Abstract: Several formal theories have been developed to characterize the capabilities and limitations of the transformer architecture, each employing different abstractions that capture different features of the architecture. Due to the differences in their underlying assumptions and conceptual frameworks, these theories can disagree in their predictions about what tasks transformers find easy or hard. We map out seven theories of transformer capability (Star-free, $\mathsf{AC}^0$, $\mathsf{TC}^0$, C-RASP, MPC, BAPO, and Sensitivity) and translate their results into a common matrix of predictions across a suite of tasks covering different computational structures. We provide new theoretical results to complete this matrix. We then evaluate theoretical
arXiv:2610.31833v1 Announce Type: new Abstract: LawZero's Scientist AI trains a Predictor toward the Bayesian posterior, with an objective that penalizes inconsistent probabilities among latent explanations. We ask whether current frontier language models, with no such training, are already consistent in this sense zero-shot: do their probability judgments satisfy the law of total probability, $P(X)=\sum_z P(z)P(X|z)$, when the latent $z$ must be inferred from records in the context? In separate single-turn calls, models are asked for $P(X)$, for $P(z)$ over the latent's states, and for $P(X|z)$; a causal family applies the same test to $P(y|do(x))$ and the back-door adjustment. Every query has an exact ground-truth probability, and a subset of items is asked in three wordings to separate
arXiv:2610.32583v1 Announce Type: cross Abstract: Multiagent deterministic GLP (madGLP) runs Grassroots Logic Programs (GLP) as agents that communicate solely by asynchronous message passing, and assumes fair delivery: every message sent is eventually delivered. Each agent runs on a person's smartphone, named by the person's public key. A grassroots platform depends on no global resource but the network, so agents must reach one another over Bluetooth Low Energy, on a local network, and across the Internet from behind NAT, via rendezvous servers anyone can run. What madGLP requires of such a network, and what the network requires of the platform, has not been specified. We specify the networking layer beneath madGLP. Anything that can be done in GLP is done in GLP: the layer provides only