
Import AI 479: Spacewar; low-latency tasks versus LLMs; Genie 4
What do LLMs think about vision models?
Search headlines, summaries and articles to connect the dots.
What do LLMs think about vision models?
Vercel Labs released agent-desktop, an Apache-2.0 Rust CLI that gives any AI agent computer use on macOS, Windows and Linux by reading OS accessibility trees and acting on stable refs instead of pixels. The post Vercel Labs Open-Sources agent-desktop for Agent Computer Use appeared first on MarkTechPost.

dbreunig/nesformer Inspired by qwenputer by Divyansh Agrawal, Drew Breunig baked a working emulator for a Nintendo Entertainment System 6502 CPU into the weights of Qwen3.5-4B. You can now play NES ROMs such as Super Mario Bros (very slowly) running inside Qwen! In a comment on Hacker News Drew reveals the Opus 5.5 prompts he used to build this system: Read this article and any relevant source code: https://divagr.com/blog/qwenputer. Then explore if you could emulate the chip and ram in a Nintendo Entertainment System (as people do today with FPGAs in MISTRs) using this technique. If so, what size model would you have to build and if you could use smaller faster ones, could you get it to be at the standard clockspeed. Followed by: I think we should build it! Just for fun. It's okay if it's
Sources tell WIRED that an Accenture employee’s personal Claude agent ran on a DOD network for two months before it was identified and the vulnerability could be patched.
Prime Intellect released Prime Mega MoE, a backward pass for DeepSeek’s fused Mega MoE kernel. It makes the kernel trainable and speeds Qwen3 MoE training steps by up to 34% in prime-rl. The post Prime Intellect Releases Prime Mega MoE: Trainable Fused MoE Kernel, 3.11x Faster Forward Pass appeared first on MarkTechPost.
Mistral AI SAS today announced the availability of the open weights of its frontier model Mistral Large 4, nicknamed “Le Chonk,” the company’s most capable large language model to date, initially released in preview three weeks ago. With 1 trillion parameters and 52 billion active parameters, ML4 is natively multimodal and has received three additional […] The post Mistral releases open weights for Mistral Large 4, providing sovereign control for the company’s ‘Le Chonk’ AI model appeared first on SiliconANGLE.
The French AI lab claims its latest release matches or outperforms even the best models from DeepSeek and Z.ai in coding and cybersecurity.
Mistral says its new model can afford organizations a kind of control over its cyber defenses that closed models can't.
The weights of Mistral Large 4 (Le Chonk) are now open. A 1T parameter multimodal model, and best open-weight model for coding, trained in Europe.
Infini-AI-Lab released Hermit, an Apache-2.0 harness adapter framework that trains an external layer of instructions, skills, memory and tools from task feedback, leaving the agent’s model and harness unchanged. The post Infini-AI-Lab Releases Hermit, an Open-Source Harness Adapter Framework for AI Agents appeared first on MarkTechPost.
Google’s new frontier model leads independent evals, with access initially limited to trusted defenders.
Nvidia Corp. today released a leaderboard-winning open artificial intelligence model for multilingual audio transcription and translation, along with an open data pipeline for fine-tuning Nemotron 3.5 Transcribe. Traditional transcription AI models follow a workflow that detects speech, transcribes it, identifies and labels different speakers, then answers questions about the transcription. Transcribe does all of this […] The post Nvidia releases all-in-one adaptable Nemotron 3.5 audio transcription and translation model appeared first on SiliconANGLE.
DeepSeek, Google, and NVIDIA build the agent stack
FlashMap is a speculative decoding drafter from Polymathic AI, Princeton and USC ISI researchers. It drafts 16 tokens jointly in one pass and reaches up to 6.14x lossless speedup on Qwen3-8B. The post Polymathic AI and Princeton Researchers Release FlashMap, a Flow Map Drafter for 6.14x Faster LLM Decoding appeared first on MarkTechPost.

Google DeepMind released Genie 4 as a research preview. The real-time world model adds native audio, live dialogue and text steering, with Gemini 3.8 Flash planning events inside the simulation loop. The post Meet Google DeepMind’s Genie 4: Real-Time World Model With Native Audio appeared first on MarkTechPost.

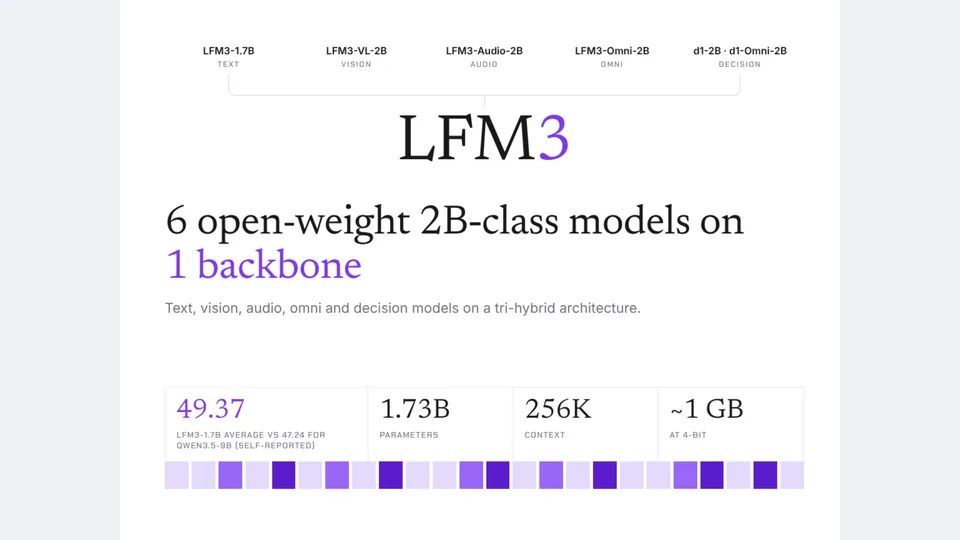
Liquid AI released LFM3, 6 open-weight 2B-class models for text, vision, audio, omni and decisions. LFM3-1.7B uses a tri-hybrid backbone, a 256K context window and fits in about 1 GB at 4-bit. The post Liquid AI Releases LFM3: 6 Open-Weight 2B-Class Multimodal Models appeared first on MarkTechPost.
Katelyn Lesse and Angela Jiang on Opus 5.5, the Claude Platform, and the engineering behind AI agents.
Mirendil released Fern 0.1, its first model, pretrained from scratch with a 10M-token context window. It targets agentic AI R&D work, scores 100% on RULER single needle at 10M, but trails frontier models on agentic coding. The post Mirendil Launches Fern 0.1, Its First Model, With 10M-Token Context appeared first on MarkTechPost.
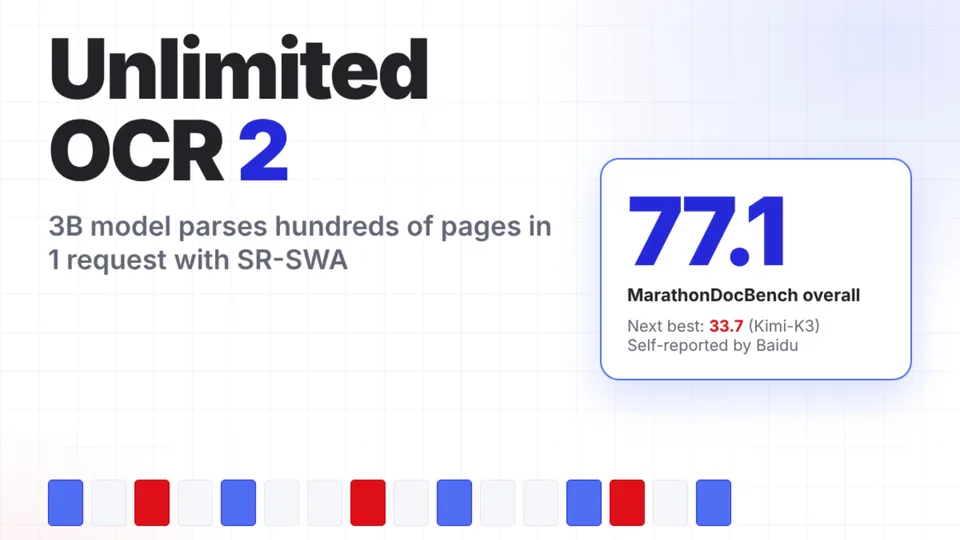
Baidu has released Unlimited OCR 2, an MIT-licensed 3B OCR model that parses hundred-page documents in one request. Its SR-SWA attention keeps per-step decoding cost nearly flat, scoring 77.1 on MarathonDocBench The post Baidu Open-Sources Unlimited OCR 2 for Hundred-Page Document Parsing appeared first on MarkTechPost.
arXiv:2610.33017v1 Announce Type: new Abstract: Multilingual tokenizers trained on English-dominated corpora often over-segment Indic languages, resulting in longer token sequences and increased tokenization disparity across scripts. We present AdaptTok-Indic, an Indic-specialized extension of adaptive tokenization that combines Unicode-normalized preprocessing with explicit Indic conjunct handling, script-aware routing, and learned byte-level boundary prediction jointly trained with a small Transformer language model. Evaluated on Bengali and Hindi, with additional evaluation on Gujarati, Tamil, and Telugu, AdaptTok-Indic achieves lower token fertility than SentencePiece BPE, an Indic-oriented tokenizer baseline, and an independently implemented MAGNET-style baseline. Across five recorded