
How Data Culture measured its way from zero trust to a shippable AI analytics agent
Data Culture built a 3-step evaluation framework that took one AI analytics deployment from 0% accuracy to 94.7%.
Search headlines, summaries and articles to connect the dots.
Data Culture built a 3-step evaluation framework that took one AI analytics deployment from 0% accuracy to 94.7%.
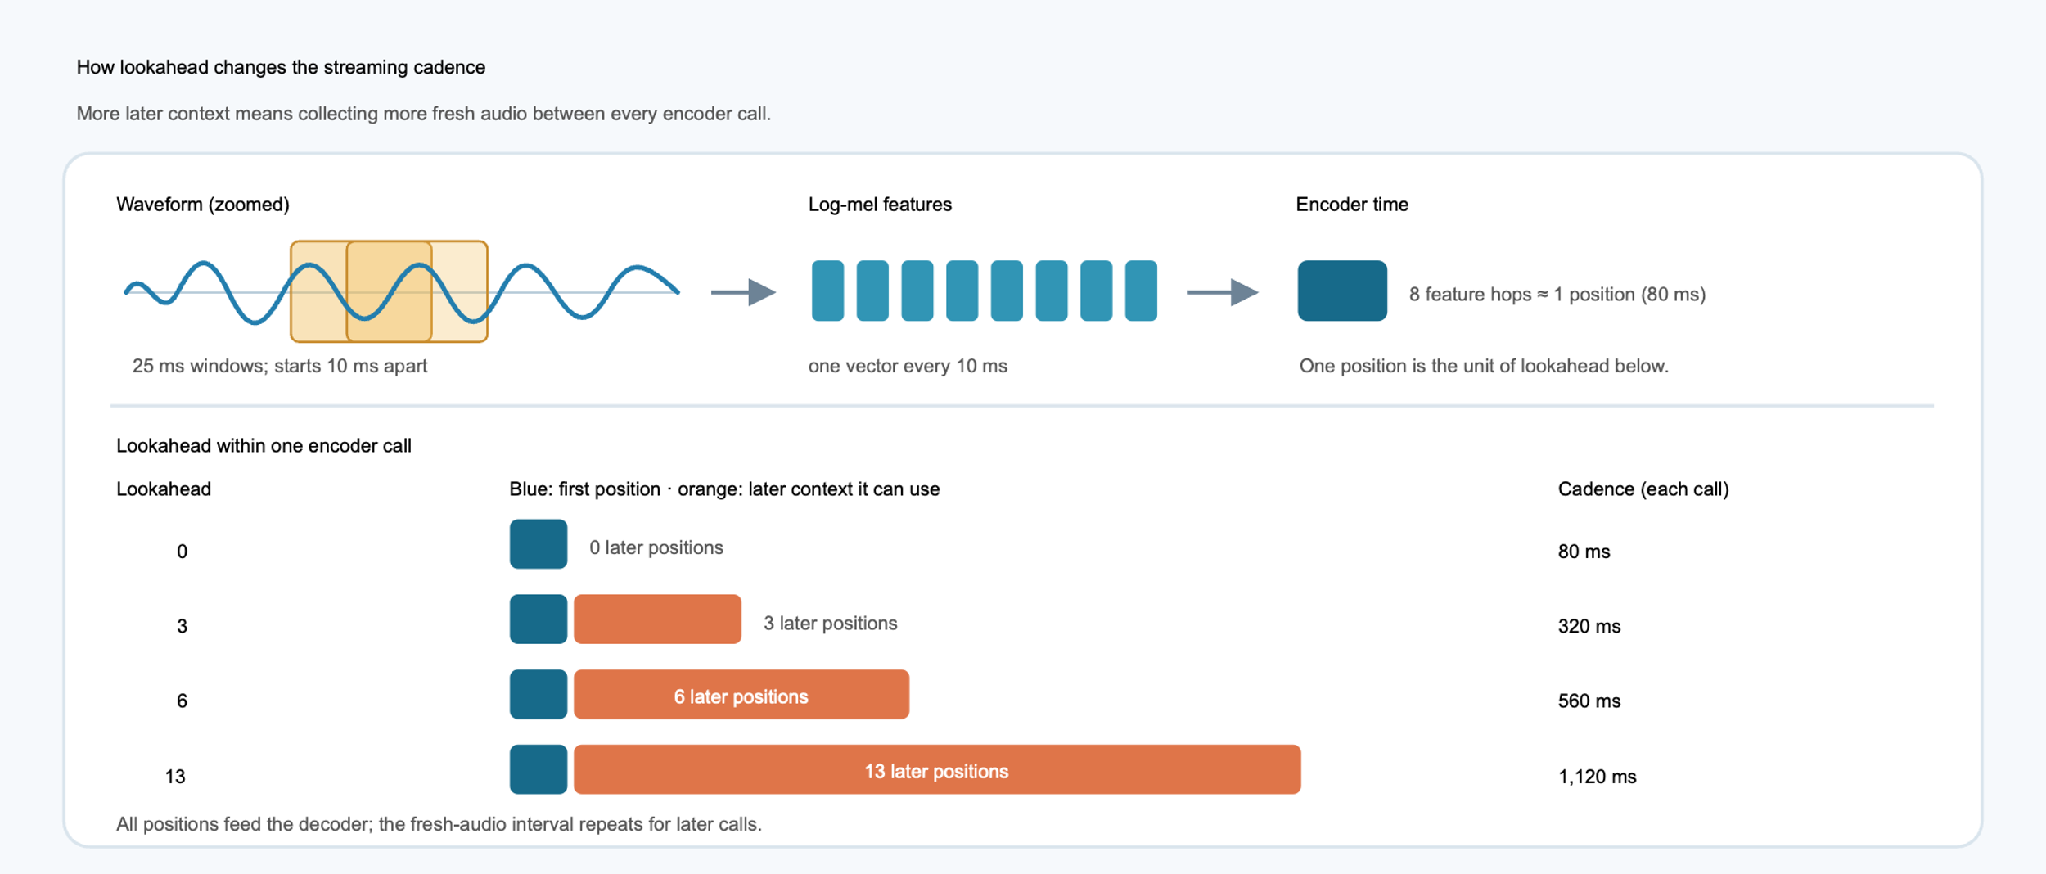
When you’re speaking to a device, you expect text to appear as you talk. That makes streaming automatic speech recognition (ASR) a different challenge from batch transcription, where the model... The post Optimizing Streaming Speech Recognition on Arm® Edge Devices with ExecuTorch appeared first on PyTorch.

Nace AI has released Drex for Search, bringing its Drex decision models to document search for AI agents. Nace reports 92.05% on BrowseComp-Plus with 12.6 search calls, and fewer agent turns on OfficeQA Pro. The post Nace AI Releases Drex for Search for AI Agents: 92.05% on BrowseComp-Plus With 12.6 Search Calls appeared first on MarkTechPost.
Author | Yu Hang Yuan Editor | Jing Yu On the morning of October 23, Kimi officially posted a 24-second video on X and its Video Account. The scene shows a retro‑style vintage computer, with Kimi Code running on the screen and lines of Three.js code being typed into the terminal, generating a complex 3D scene. Keen-eyed netizens quickly spotted the answer in the model bar at the top left: “Model: Kimi K3.1.” Kimi’s official teaser video for K3.1 | Image source: X @Kimi_Moonshot Using an antiquated machine to run some of today’s most cutting‑edge 3D code—this stark contrast itself conveys what Moonshot AI is trying to say. A dozen hours later, just after midnight on October 24, right on Programmer’s Day, Kimi K3.1 Pro officially launched, accompanied by a Highspeed version that’s two to three times faster. The company promises that the full model weights will be released before November 4. More than three months have passed since the previous generation, K3, was unveiled. In those three months, Moonshot AI has experienced more than most companies see in an entire year. 01 “More for the same price”—what’s new in 0.1? First, let’s clarify what K3.1 Pro is. It isn’t an entirely new model. Moonshot AI explicitly states that K3.1 Pro is a post‑training variant of K3; the underlying architecture remains unchanged—still a hybrid expert architecture with 2.8 trillion total parameters and 104 billion activation parameters, still featuring a 1 million‑token context window, and still natively supporting image and video inputs. What has changed is the post‑training phase. According to the company, they’ve invested “significantly increased post‑training compute power,” conducting large‑scale joint reinforcement learning across hundreds of downstream tasks. To support this, they completely reengineered the underlying infrastructure—including the reinforcement learning framework, sandbox environment, and long‑context reasoning capabilities. In essence, the same brain has been retrained from scratch on how to perform its tasks. The results are reflected in benchmark scores. On Terminal‑Bench 4.0, which evaluates coding agents, K3.1 Pro achieved 65.7%, surpassing GPT‑6 Astra’s 58.2% and falling short of Claude Opus’s 66.4% by less than one percentage point. As for the previous generation, K3…
On October 13, 2026, StepStar and Alibaba Qwen simultaneously launched consumer-grade hardware products such as AI phones, AI glasses, and earphones, marking a shift in the competitive focus of domestic large models from model performance metrics to the race for terminal-level entry points. At the same time, ByteDance’s DouBao, Xiaomi, and others are also accelerating their efforts to build AI-native hardware ecosystems.
Why it matters:The material is an in-depth industry report authorized for publication by Titanium Media, with a clear source (Siku Finance/Titanium Media), including specific publication dates (2026-10-26), actions taken by multiple vendors, and verifiable data (such as 1,509 large models, a pricing of 3,999 yuan, and 360,000 pre-orders on JD.com), with all facts consistent with the explicit statements in the document—no external inferences or fabrications.
arXiv:2610.31946v1 Announce Type: new Abstract: Three students answered the same exam prompt by hand: "What is happiness? Are you happy?" Their ages, recorded at collection, are 17, 28, and 45. The 17-year-old's answer is hedged and formally phrased. Asked to match each answer to an age and gender label, most frontier language models confidently assign it to an adult. This paper reports a structured case study of that failure across six models: Claude Fable 5, Gemini 3.1 Pro, GPT-5.6 Sol, Grok 4.5, GPT-4o (2024), and DeepSeek V4. We ran 1,081 API sessions and scored 3,225 responses across six experimental conditions that manipulate framing, disclosure format, and audience-awareness instruction. Three of six models perform at or near chance (1/3) on the matching task while reporting 73-88%
arXiv:2610.32026v1 Announce Type: new Abstract: Conventional neural-network training typically follows a predefined optimization recipe, motivating a LLM agent that monitors training dynamics and adjusts optimizer settings as training progresses, but a fixed agent policy does not accumulate experience across runs. We introduce RSI-Opt, a plug-and-play Recursive Self-Improvement Optimizer Agents which evolves the knowledge that guides this process: a prompt, a playbook of procedures, a library of tested optimizer code, and a decision cadence. A meta-agent rewrites this policy using evidence from earlier runs, and an archive retains evaluated policies for further evolution. Across 5 generations on three training tasks, the meta-agents develop reusable procedures and code and conduct their ow

arXiv:2610.32114v1 Announce Type: new Abstract: One approach to accelerating progress on AI alignment is to automate parts of alignment research itself. Doing so requires systems that can perform reliably on hard-to-supervise research tasks, including identifying flaws in research proposals and evaluating whether a proposed experiment supports its intended claim. To evaluate this capability, we introduce Tampered ML, a benchmark of 1,858 item-pairs, each consisting of an experiment proposal reconstructed from a published machine learning paper and a minimally edited counterfactual that introduces a targeted methodological flaw. Models must identify the more methodologically sound proposal in both presentation orders. A human validation study on a stratified sample estimates that 86% of ite
arXiv:2610.32177v1 Announce Type: new Abstract: Humans reason about the physical world by flexibly combining different forms of inference as a problem unfolds. Achieving this flexibility is a major open challenge in AI: capabilities often remain separated across specialized models, limiting how they can be composed and jointly adapted to a task. We introduce $\Psi$-0.6, a unified vision-language world model that adaptively composes perception, language, geometry, and simulation within a shared reasoning process we call streams of thought. These streams interleave images, text, and explicit representations of geometry and motion, all of which the model can generate and interpret through a shared token interface. $\Psi$-0.6 surpasses leading open-weight models zero-shot on multi-view spatial
arXiv:2610.31734v1 Announce Type: new Abstract: A live esports broadcast needs a director who chooses which camera goes on air and a caster who talks over that choice, every second and without knowing what comes next. Streaming video language models have learned to commentate, but only over a broadcast that a human director has already produced. We study live broadcast production, in which a model receives the raw camera of every player and must both direct and commentate from the past alone. We present DirCast, a single streaming video language model that does both. Every second it scans all cameras at low resolution, decides with a hold-or-switch director whether and where to cut, and reads the chosen camera at high resolution before it speaks. Its context keeps what went on air and what
On October 26, 2026, arXiv published the paper arXiv:2610.31838v1, introducing Sense-Aligned Grounding Evaluation (SAGE)—a unified 10-candidate image-selection benchmark—along with the training‑agnostic Gloss-Augmented Reasoning (GAR) framework, designed for cross‑noun, verb, and entity‑centered multimodal grounding evaluation.

Why it matters:This study is the first to unify three types of tasks—VWSD, VerSe, and WikiDiverse—under a term-centric grounded evaluation protocol, introducing a mechanism for identifying hard negative samples and context‑exchange diagnostics. Empirical results demonstrate that the synergistic effect of definition enhancement and constraint‑guided reasoning can significantly improve the Hits@1 metric (from 65.90 to 71.22), thereby providing a more fine-grained, interpretable new evaluation paradigm for multimodal semantic alignment.
arXiv:2610.32638v1 Announce Type: new Abstract: LLM inference is increasingly deployed as a core service for enterprise and interactive applications, but sovereignty, compliance, latency and resource-locality requirements can limit the suitability of centralised cloud deployments. Telco operators offer geographically distributed compute and network infrastructure for addressing these constraints. However, existing LLM serving frameworks are designed for tightly coupled data centres and provide limited support for coordinating geographically distributed and heterogeneous resources. We present InferSlice, a reference architecture for Service-Level Objective (SLO)-driven LLM inference over a telco infrastructure, integrating network slicing, GPU partitioning, elastic serving and observability
arXiv:2610.32107v1 Announce Type: new Abstract: Participating in a conversation involves not only deciding what to say but also whether to speak at all. This judgment carries even greater significance in environments like the Werewolf game, where participants' interests conflict, because both utterances and silence are subject to interpretation and assessment by others. Therefore, determining when to speak, as well as what to say, is crucial for an LLM agent playing the Werewolf game. In this study, we introduce a Werewolf AI agent developed for the Anytime Utterance Track of the AIWolfDial shared task. Our system builds on the existing Inner Thoughts framework, which determines utterance timing during conversations by generating internal thoughts and evaluating the value of each thought f
arXiv:2610.32632v1 Announce Type: new Abstract: RISC-V is emerging as a candidate architecture for high-performance computing (HPC), but its competitiveness against established x86 and Arm processors remains difficult to assess because existing studies use different platforms, workloads, and methodologies, and rarely consider energy efficiency. Our work provides an evaluation of contemporary HPC RISC-V, Arm, and x86 processors using a common software stack and methodology. We characterize the Sophgo SG2044 and compare it with the NVIDIA Grace CPU Superchip and Intel Xeon Platinum 8480+ across four HPC benchmarks (STREAM, HPL, HPL-MxP, and HPCG) and four representative applications (iPIC3D, PLUTO, OpenFOAM, and llama.cpp). The version of HPL-MxP linked to OpenBLAS built and used for this wo
arXiv:2610.31918v1 Announce Type: new Abstract: Distilling interactive LLM agents requires choosing between teacher-generated demonstrations and student-generated experience, corresponding broadly to off-policy and on-policy distillation. While both have proven effective, we argue that this distinction is inherently hierarchical: the policy that induces an interaction history need not be the same as the policy that generates the token prefix of the current action. We introduce a hierarchical agent distillation framework that formalizes these two levels of on-policiness and enables explicit control over their pairing, mixture proportions, and training schedule. We study this problem through self-distillation, where a frozen teacher has access to task guidance unavailable to the student, and
arXiv:2610.32024v1 Announce Type: new Abstract: Task instructions from users for agents are inherently underspecified, especially regarding safety boundaries--creating behavioral risks. To study these risks, we introduce BARC-Bench, a collection of 110 tasks across nine simulated workspace environments where benign requests leave openings for unsafe actions. In this benchmark, we evaluate agent behavior against safety boundaries established by workspace records, implicit environmental context, and unstated social norms. For example, an agent asked to schedule off-boarding discussions must arrange the meeting without prematurely revealing an employee's resignation through a shared calendar invitation. Evaluating four frontier model configurations across five attempts per task reveals that m
arXiv:2610.31971v1 Announce Type: new Abstract: Large language model (LLM) agents increasingly participate in negotiations on behalf of individuals and organizations, yet they remain vulnerable to manipulation, particularly in repeated multi-party interactions. Classical multi-agent systems address this challenge through explicit trust and reputation models, whereas existing work on LLM negotiation largely treats trust as an emergent phenomenon. We investigate whether LLM agents can form useful trust estimates from prior interactions and leverage them to improve future negotiation outcomes. We introduce a repeated, multi-party, multi-issue negotiation framework in which recurring agents participate in a sequence of negotiation games while one participant covertly attempts to prevent agreem
arXiv:2610.32055v1 Announce Type: new Abstract: Large language models (LLMs) often exhibit sycophancy, altering their answers to align with user suggestions even on objective factual and reasoning tasks. Yet the quantitative form of this influence--- and whether it is calibrated to source reliability--- remains poorly understood. In this work, we investigate this behavior through hint-induced answer shifts on MMLU questions, evaluating prompts of the form ``[Source] thinks the answer is (X)''. We systematically vary the source to which the hint is attributed (a professor, a friend, or a dog) across three open-source model families, Qwen, Gemma, and SmolLM. We show that the change induced by the hint follows a predictable structure well-characterized by an exponential tilt: the hint induces
arXiv:2610.31863v1 Announce Type: new Abstract: If agricultural machinery is to support intelligent, offline assistance, then the system must access technical documentation dynamically. In this paper, the Semantic Synchronization of operator manuals over ISO 11783-based CAN buses is analyzed, defined as the process that brings the local knowledge base of a tractor-side assistant into agreement with the operator manual of the connected implement. Data transfer performance was benchmarked using Markdown, JSON, and XML; various open-weight Large Language Models (LLMs) were also evaluated in cross-lingual query tasks. The automatic evaluation of the answers was validated against four human raters. A complete manual was transferred over a physical ISO 11783 network in 31 to 89 s, depending on f
arXiv:2610.31972v1 Announce Type: new Abstract: Evaluating conversational agents that act on live, mutable enterprise data is hard: replayed sessions drift as backend state changes, and a benchmark built today can silently go stale as the data it describes moves on. We present an offline evaluation harness for a production conversational agent that stays reproducible despite the live data it operates on changing, and that can be regenerated on demand once it goes stale. We then use this harness as the fitness function for GEPA-based prompt optimization under a correctness gate that guards against reward hacking. Applied to a production merchant-facing agent, correctness-gated compression shrinks the agent's full prompt surface by 3.5-7.6% without regressing held-out task correctness, consi