Skip to content
AI NEWS JOURNAL
AI, IN PERSPECTIVE

Search AI news

Search headlines, summaries and articles to connect the dots.

Newest first

LangChain releases the five core components of its “Enterprise-Level Agent Framework”

On October 25, 2026, LangChain published a blog post systematically outlining the five universal architectural principles it has distilled from deploying AI agents (GTM Agent, OpenSWE, Content Studio) within its marketing, sales, and engineering teams: native integration with the work environment (Slack), a dynamic identity model (OBO + fixed credentials), a two-tiered memory mechanism (global/user-level), sandboxed code execution, and a high proportion of scheduled operations (not manually triggered). All agents are built on the Managed Deep Agents platform.

Why it matters:This information originates from the official LangChain blog, published on 2026-10-25T18:06:32.000Z—earlier than the current system time of 2026-10-25T23:01:18.857Z. The content focuses on implemented internal agent practices, with specific details such as Slack thread isolation, GitHub account attribution logic, and tiered permissions for Notion/Twitter, without including unverified predictions or external claims, thus meeting requirements for timeliness and factual accuracy.

Timeline and related coverage

A roundup of the most anticipated AI-powered wearable devices in 2026: over ten new models, including Bee, Friend, Limitless, and more, make their debut.

On October 25, 2026, TechCrunch published a review summarizing more than ten AI-powered wearable devices, including Bee, Friend, Limitless, Muse Charm, Nirva, Omi, Plaud NotePin, Rabbit R1, Stream Ring, and others, covering their pricing, functional positioning, market availability, and privacy controversies.

The hottest AI wearables and gadgets you should know about

Why it matters:This report is an annual roundup of new products published by the authoritative tech media outlet TechCrunch on October 25, 2026. It covers both mainstream AI hardware manufacturers and startups, providing a comprehensive overview in terms of price, form factor, core features, release timelines, and points of contention. All statements are based solely on facts explicitly stated in the source material, with no speculation or extrapolation.

Timeline and related coverage

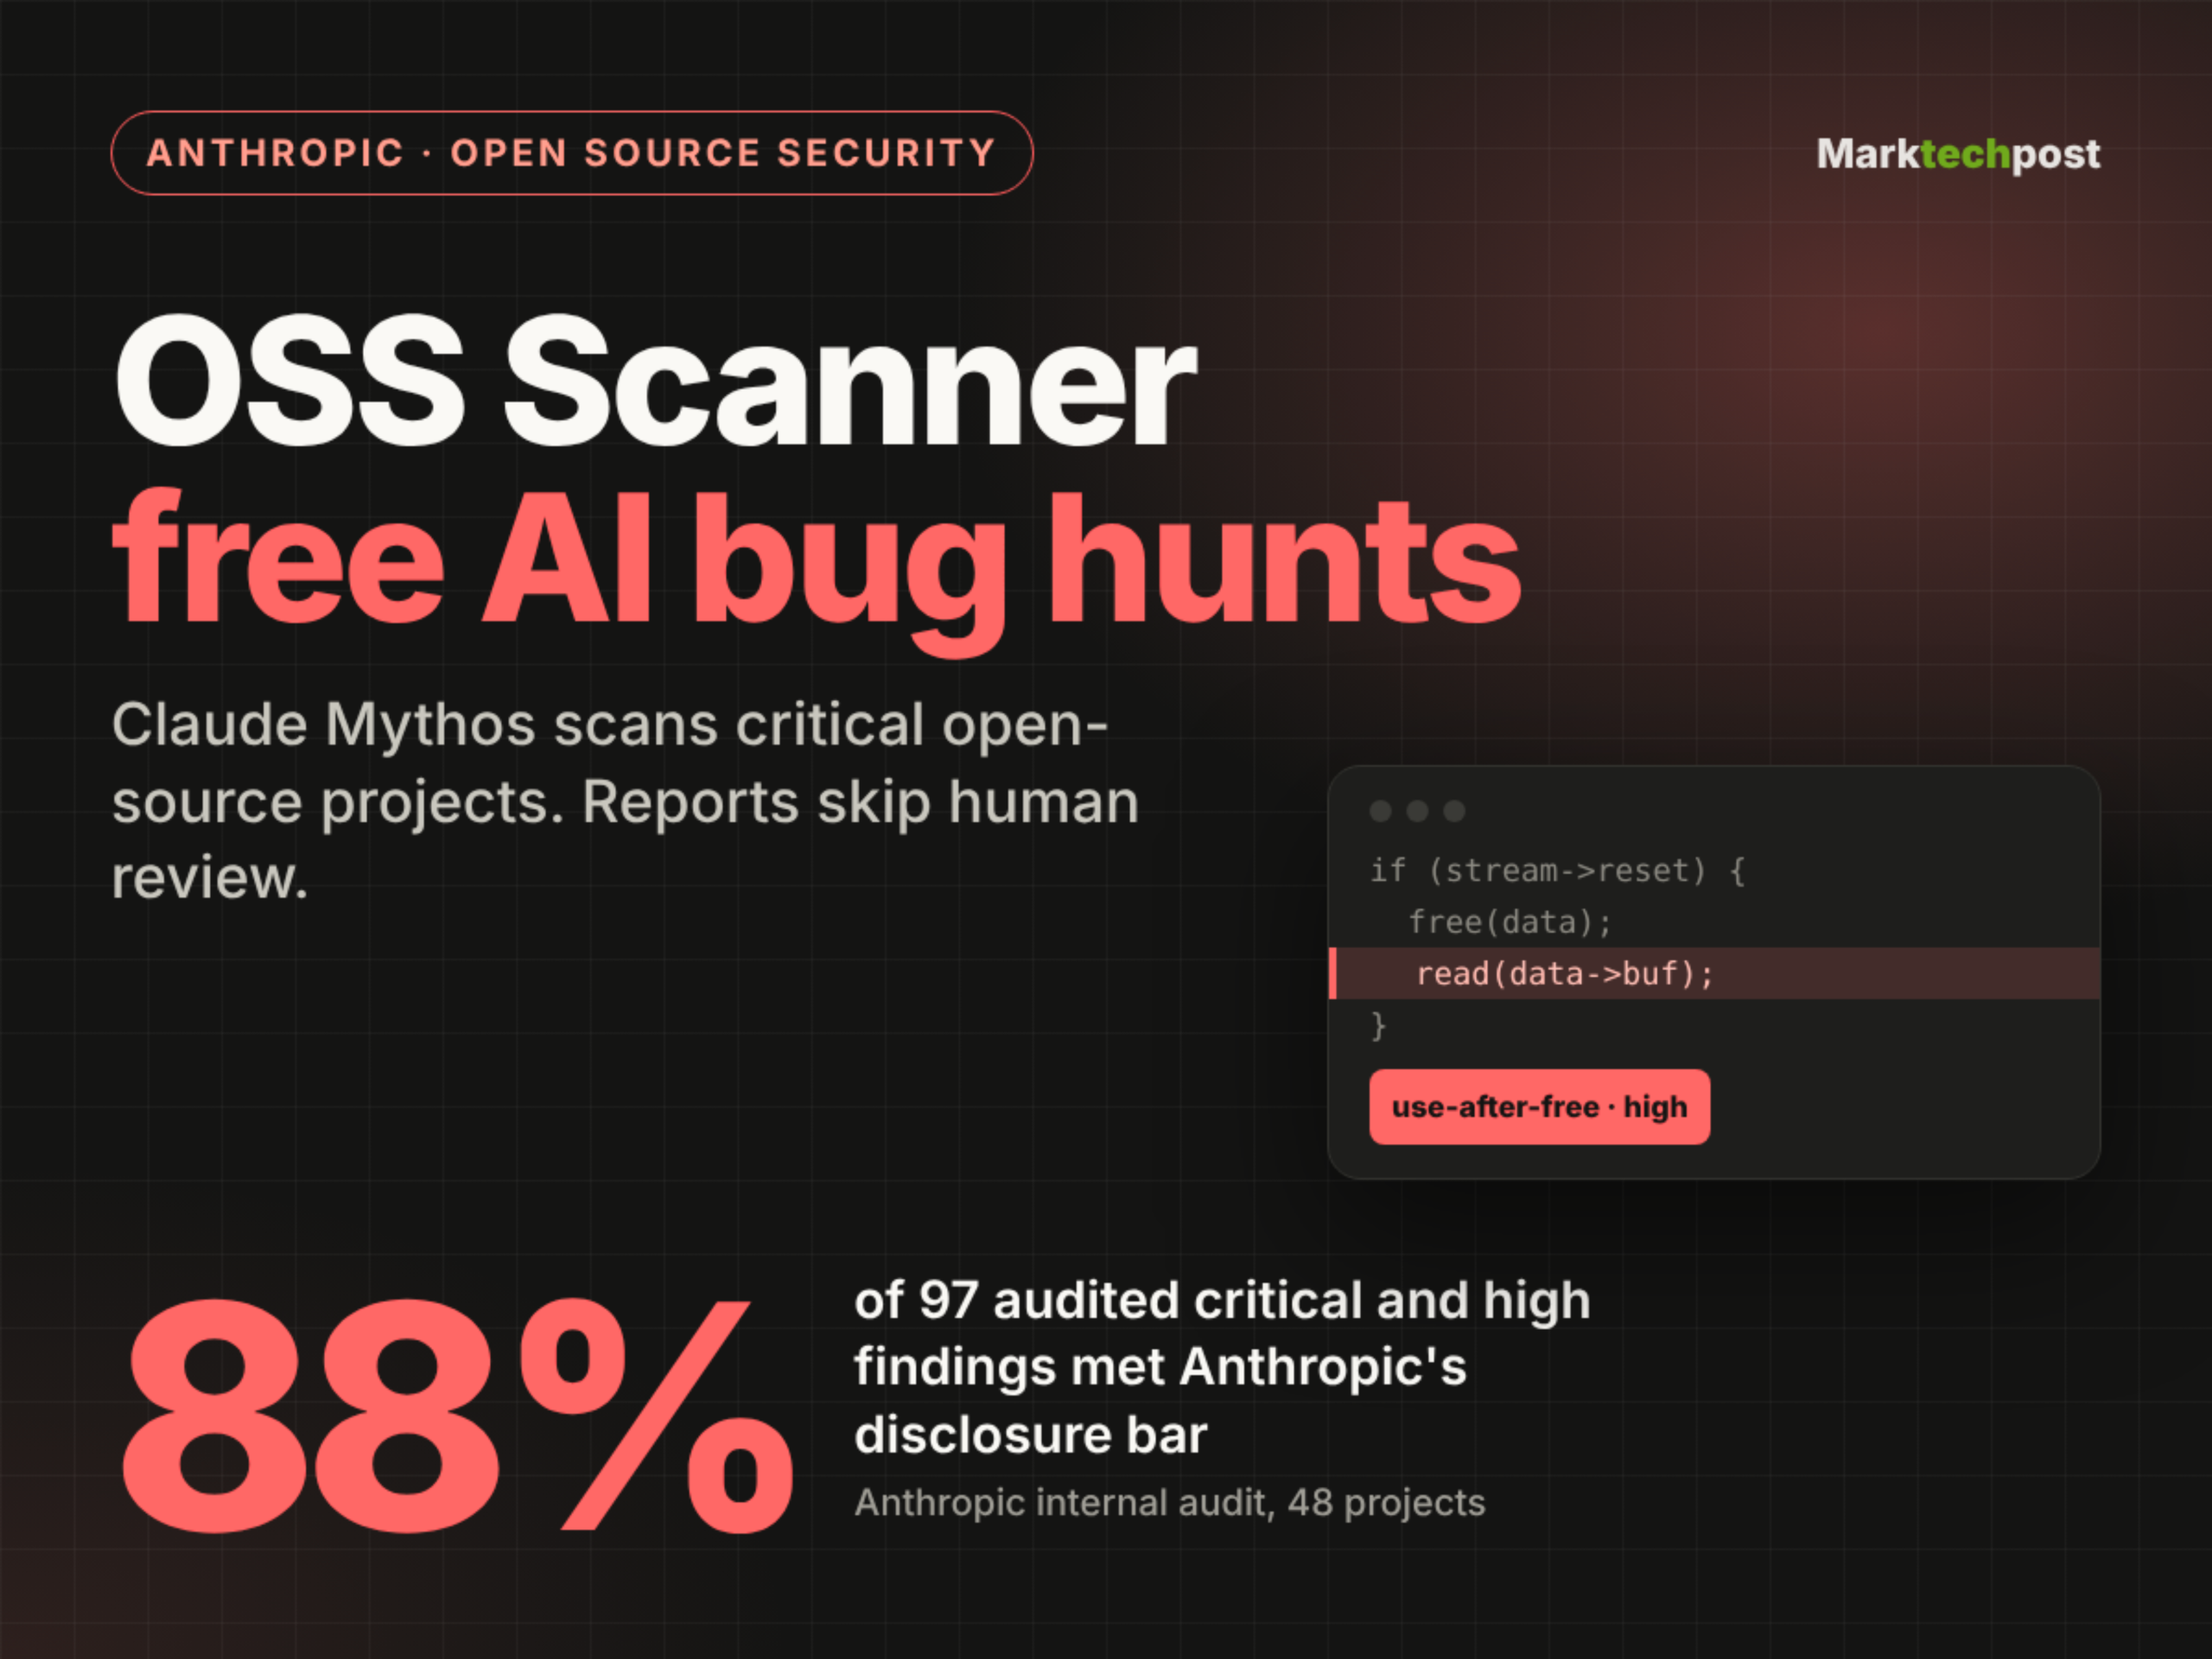
Anthropic launches OSS Scanner, a free AI-powered vulnerability scanner for critical open-source projects.

Anthropic launched OSS Scanner on October 8, 2026—a free, opt-in AI vulnerability-scanning tool powered by strong models such as Claude Mythos, designed specifically for critical open-source projects. As of October 19, it had onboarded 114 projects and, within 11 days, reported 77 high-severity and 803 medium-severity vulnerabilities (according to model ratings), with 88% of sampled audit results meeting its disclosure standards.

Anthropic Launches OSS Scanner, a Free AI Vulnerability Scanner

Why it matters:This tool represents a large-scale implementation of LLMs in the open-source security domain, characterized by zero cost, full automation, and offline auditing; however, bypassing the human review stage introduces risks of false positives and duplicate issues. Its accuracy metrics—88% detection rate and 1% false positive rate—and real-world project feedback (e.g., wolfSSL, curl) provide an empirical benchmark for the current state of AI‑driven vulnerability discovery.

Timeline and related coverage

Kimi releases K3.1 Pro: Terminal task capabilities top the charts, with simulation debugging and multimodal programming showcasing the nascent form of embodied intelligence.

On October 25, 2026, Kimi released the K3.1 Pro model, which ranked first in the Terminal-Bench 4.0 terminal task benchmark with a 67.2% success rate. Its capabilities—including autonomously fixing emulator errors, performing physics simulations, conducting audio analysis, constructing 3D scenes, and editing videos—point toward exploring pathways in embodied intelligence technology.

根据报道中的虚拟人行走训练和模拟器调试制作的编辑示意,非软件实拍截图

Why it matters:The material is based on a hands-on test report published with authorization from Titanium Media, covering authoritative third-party benchmark data (such as Artificial Analysis and Terminal-Bench 4.0), official self-test results, and the author’s multi-scenario functional validation. It highlights the K3.1 Pro’s substantial advancements in execution performance, simulation closed-loop capabilities, and multimodal programming, while clearly noting performance limitations and undisclosed information (e.g., Flash/Ultra has not yet been released), in compliance with fact-checking and source attribution requirements.

Timeline and related coverage

Panel manufacturers are collectively raising prices to cope with upstream cost pressures driven by AI, but downstream acceptance remains low, putting pressure on end-product quality control.

Starting in September 2026, panel manufacturers such as TCL CSOT, BOE, and HKC have issued price‑increase notices one after another. The primary reason is the rapid growth of AI large models, which has led to a sharp surge in demand for HBM, squeezing capacity for mature‑process chips and driving up the prices of key components like driver ICs, PCBs, and glass substrates. Upstream suppliers, including Corning, have also raised their prices in tandem. Despite clear cost pressures, downstream TV and monitor brands have yet to broadly increase purchase prices, while end users continue to report frequent quality‑control issues such as overheating and black spots. As a result, these price hikes have not yet translated into actual sales or improved user experiences.

AI大模型狂飙,面板行业也扛不住了

Why it matters:The materials system reveals the cross‑chain transmission mechanism through which the AI industry impacts indirectly related hardware sectors—rather than driving panel demand directly, it triggers a full‑chain cost repricing via the reallocation of wafer‑fabrication capacity. At the same time, it highlights a significant gap between price‑increase behavior and actual market feedback (price rigidity, declining shipments, and user complaints), underscoring the deep‑seated contradiction between industry bargaining power and product competitiveness.

Timeline and related coverage

Microsoft open-sources Agensh: a decentralized framework that supports 1024 autonomous, collaboratively operating AI coding agents.

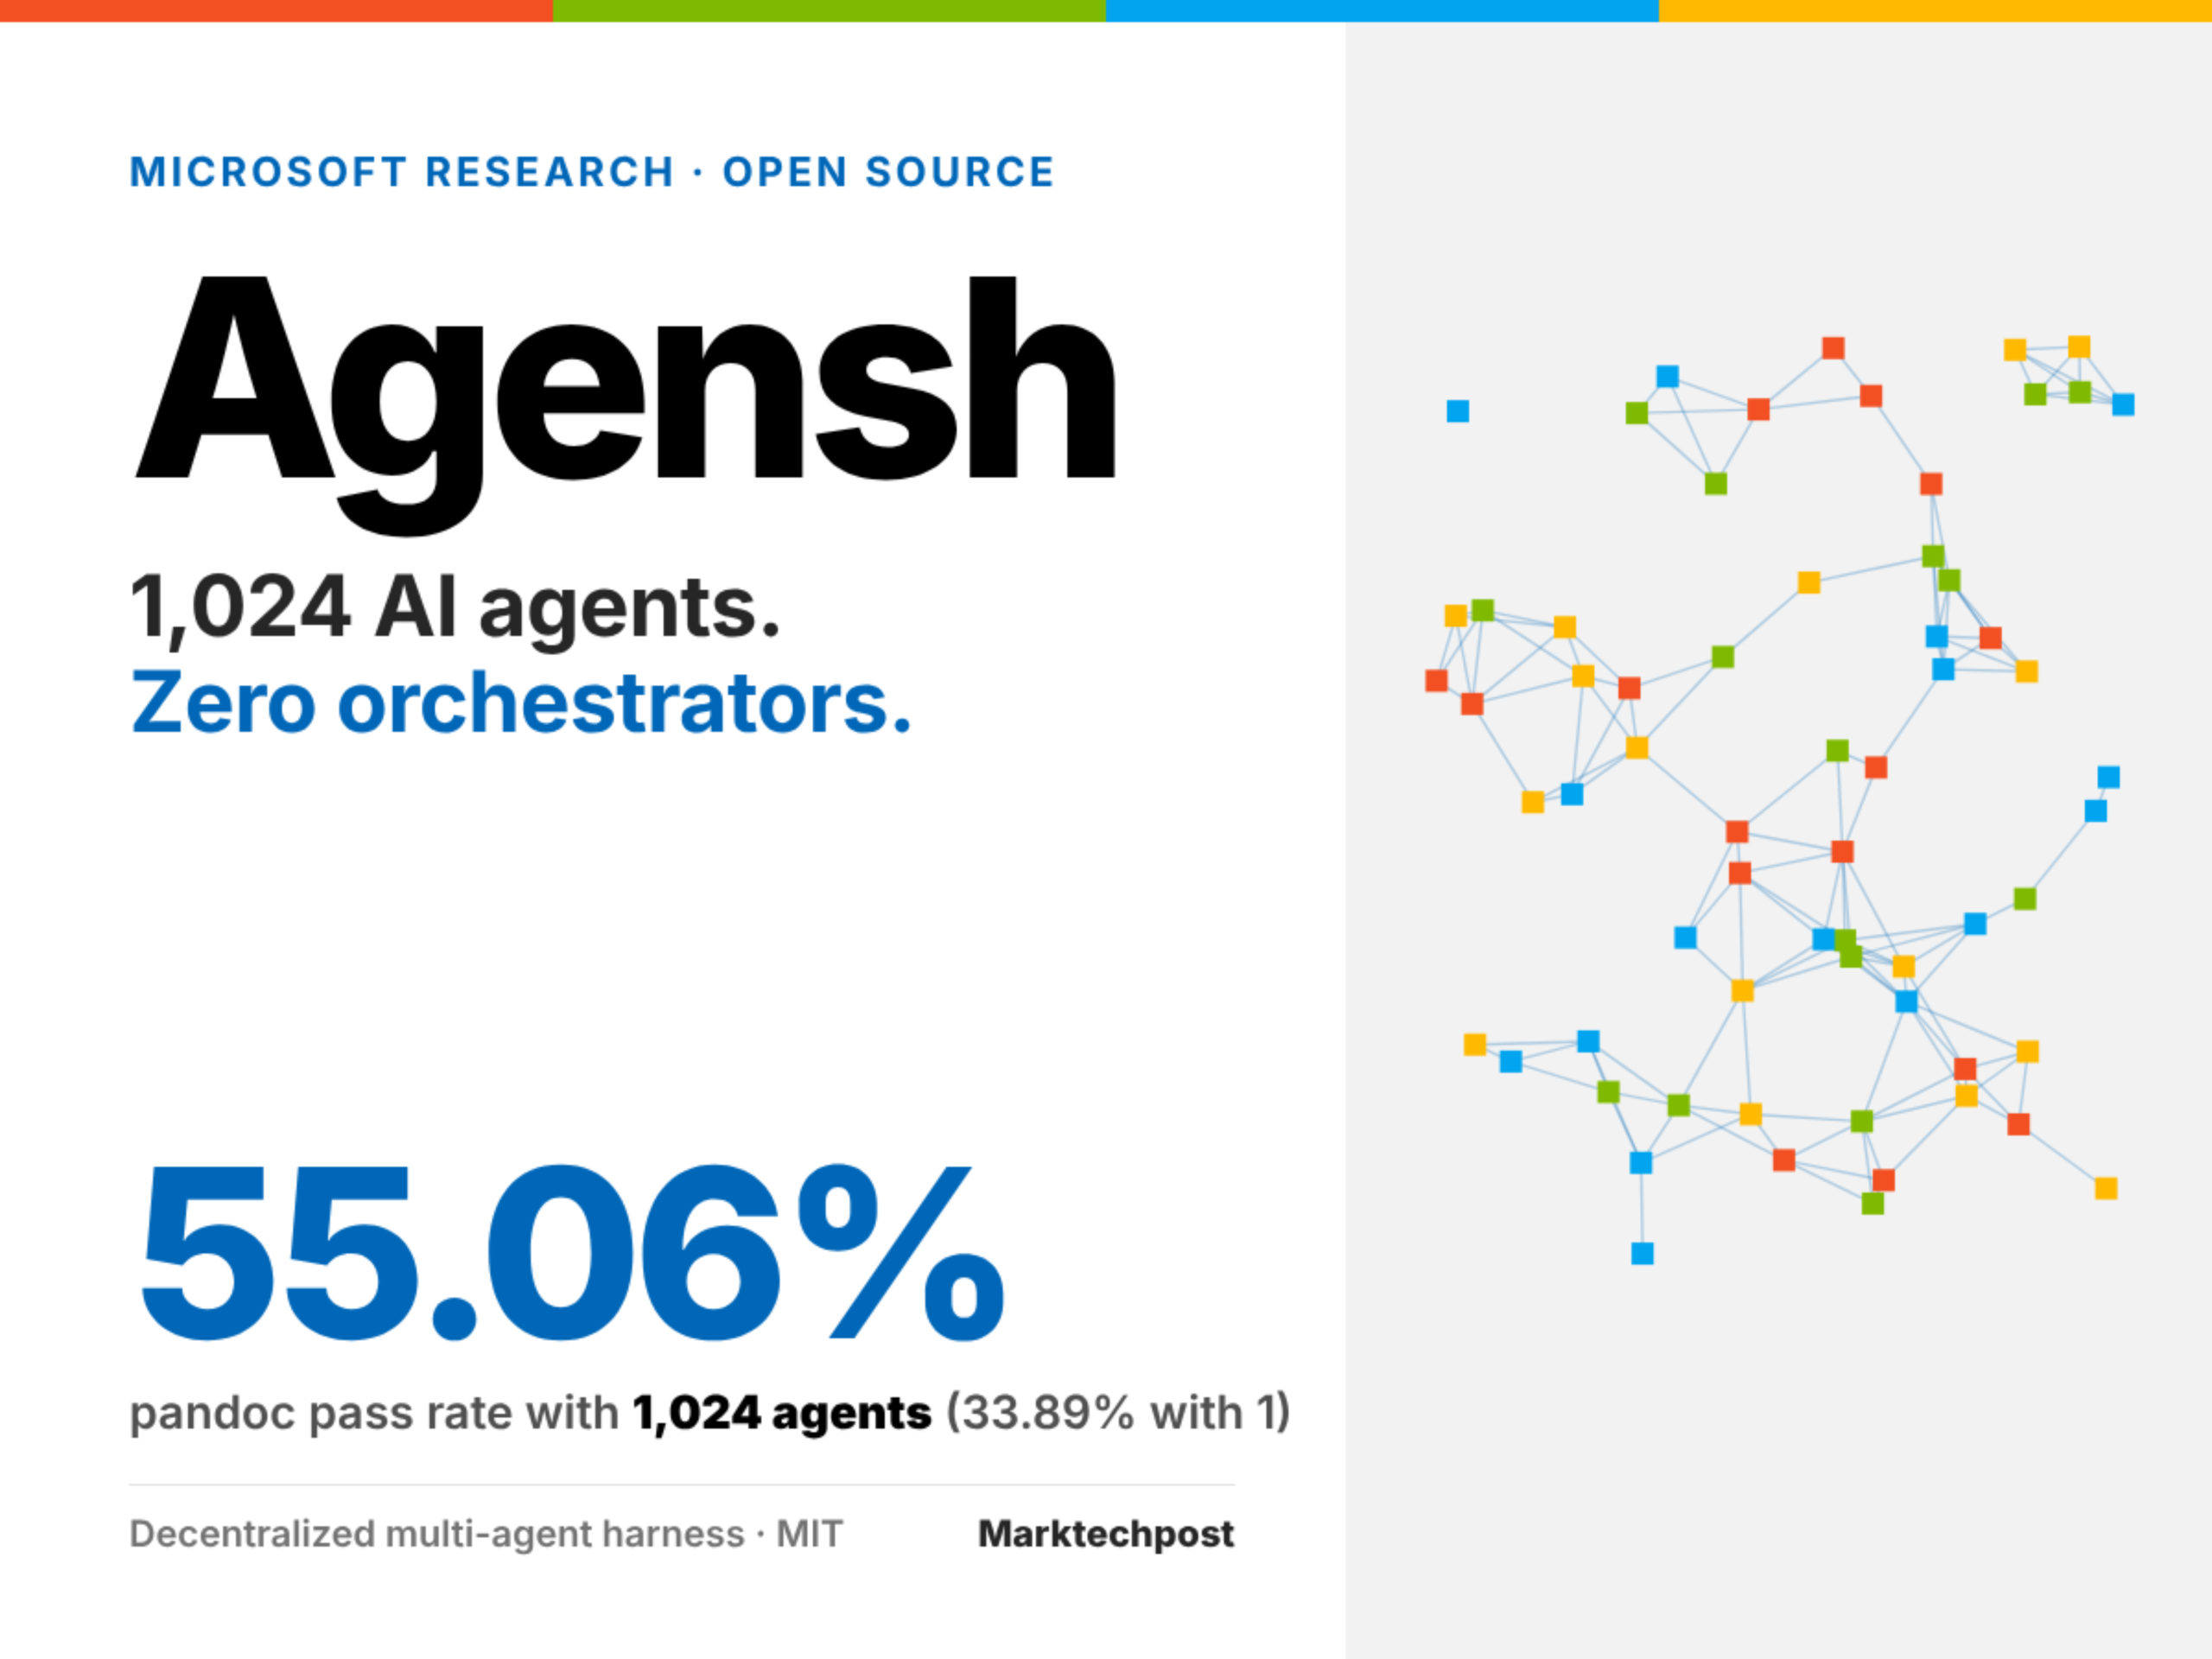
On October 25, 2026, Microsoft Research open-sourced Agensh, a multi-agent runtime framework that operates without a central coordinator, enabling 1 to 1,024 LLM-powered coding agents to self-organize and collaborate on ProgramBench. The system achieves decentralized coordination through shared dashboards inspired by Gitea, Mattermost, and DeLM, with all agents following the same prompt-driven five-step loop; its scalability has been validated in a Linux + Docker environment.

Microsoft Open-Sources Agensh: A Multi-Agent Harness for 1,024 Agents

Why it matters:This achievement represents a significant evolution in multi-agent system architectures—abandoning the traditional “master‑agent” paradigm and enabling large‑scale self‑organization through prompt engineering and lightweight service composition. Empirical results on ProgramBench (e.g., 128 agents achieving a 49% improvement in task load balancing across five tasks) establish a new benchmark for distributed AI engineering. Released under the MIT License and compatible with mainstream single‑agent tools such as Copilot CLI, it offers valuable guidance for practical development.

Timeline and related coverage

Taking on NVIDIA head-on to challenge Apple—Microsoft’s high-end AI PC gamble

Microsoft is courting local AI developers and high-end creators with the Surface Laptop Ultra, which features NVIDIA RTX Spark. The hardware brings large-capacity unified memory, CUDA, and RTX graphics capabilities to a portable device, but whether it can sustain competition against Macs will still depend on app optimization, agent-based experiences, and real-world workflows.

Why it matters:Ultimately, this competition comes down to whether on-device AI can genuinely boost creativity and development efficiency, and whether the associated costs—hardware, software, and migration—are justified. Hardware opens up new possibilities, but the ecosystem and real-world user experience determine how many users those possibilities can reach.

Timeline and related coverage

Apple’s first foldable-screen iPhone, the Duo, has already experienced widespread screen cracking shortly after going on sale.

Multiple users have reported that Apple’s first foldable smartphone, the iPhone Duo, develops screen cracks and splits right above the hinge shortly after unboxing, with failures occurring at a high rate. Cases have been documented in both Australia and China, reportedly due to tolerances in the hinge assembly. Apple has yet to issue an official response, and the outcome of the after-sales service assessment will determine whether the device will be replaced free of charge or require costly out-of-pocket repairs.

Why it matters:The incident involves widespread early‑stage quality issues with a new device, directly challenging the boundaries between consumer rights and corporate responsibility. Coupled with public concerns about the applicability of the “three‑guarantee” regulations and the positioning of AppleCare+ services, it carries significant warning implications and serves as a valuable reference for rights protection.

Timeline and related coverage

llama.cpp releases version b11867: server-side entry point refactored, with full support for multiple platforms and heterogeneous acceleration backends.

llama.cpp has officially released version b11867 on GitHub. Key changes include a refactored server entry point (PR #31113) and the addition of the server_role mechanism. Additionally, more than 40 precompiled binaries are now available, covering macOS, Linux, Windows, Android, iOS, and openEuler, with support for diverse hardware backends such as CPU, CUDA (12.4/12.8/13.4), Vulkan, ROCm 10.0, OpenVINO, SYCL (FP16/FP32), and Snapdragon (Adreno + Hexagon).

Timeline and related coverage

Sebastian Raschka has released an eight-video course titled “Building a Reasoning Model from Scratch.”

On October 24, 2026, Sebastian Raschka published an eight-part, over-11-hour hands-on video course on Python and PyTorch in Ahead of AI magazine (magazine.sebastianraschka.com), systematically covering the evaluation of inference models, scaling during inference, reinforcement learning (RLVR), and knowledge distillation, with all methods implemented using the pre-trained Qwen3-0.6B model.

Why it matters:This course is the author’s advanced technical educational offering, following “Building Large Language Models from Scratch.” It focuses on the core evolutionary direction of today’s mainstream LLMs—enhancing inference capabilities—covering the entire technical pipeline from setting up the foundational environment to GRPO reinforcement learning and self‑distillation. The author explicitly states that all implementations are “hand‑crafted from scratch,” fully reproducible, and highly instructive with significant engineering reference value.

Timeline and related coverage

Anthropic open-sources the OS-level sandbox sandbox-runtime: providing container-free file and network isolation for AI agents.

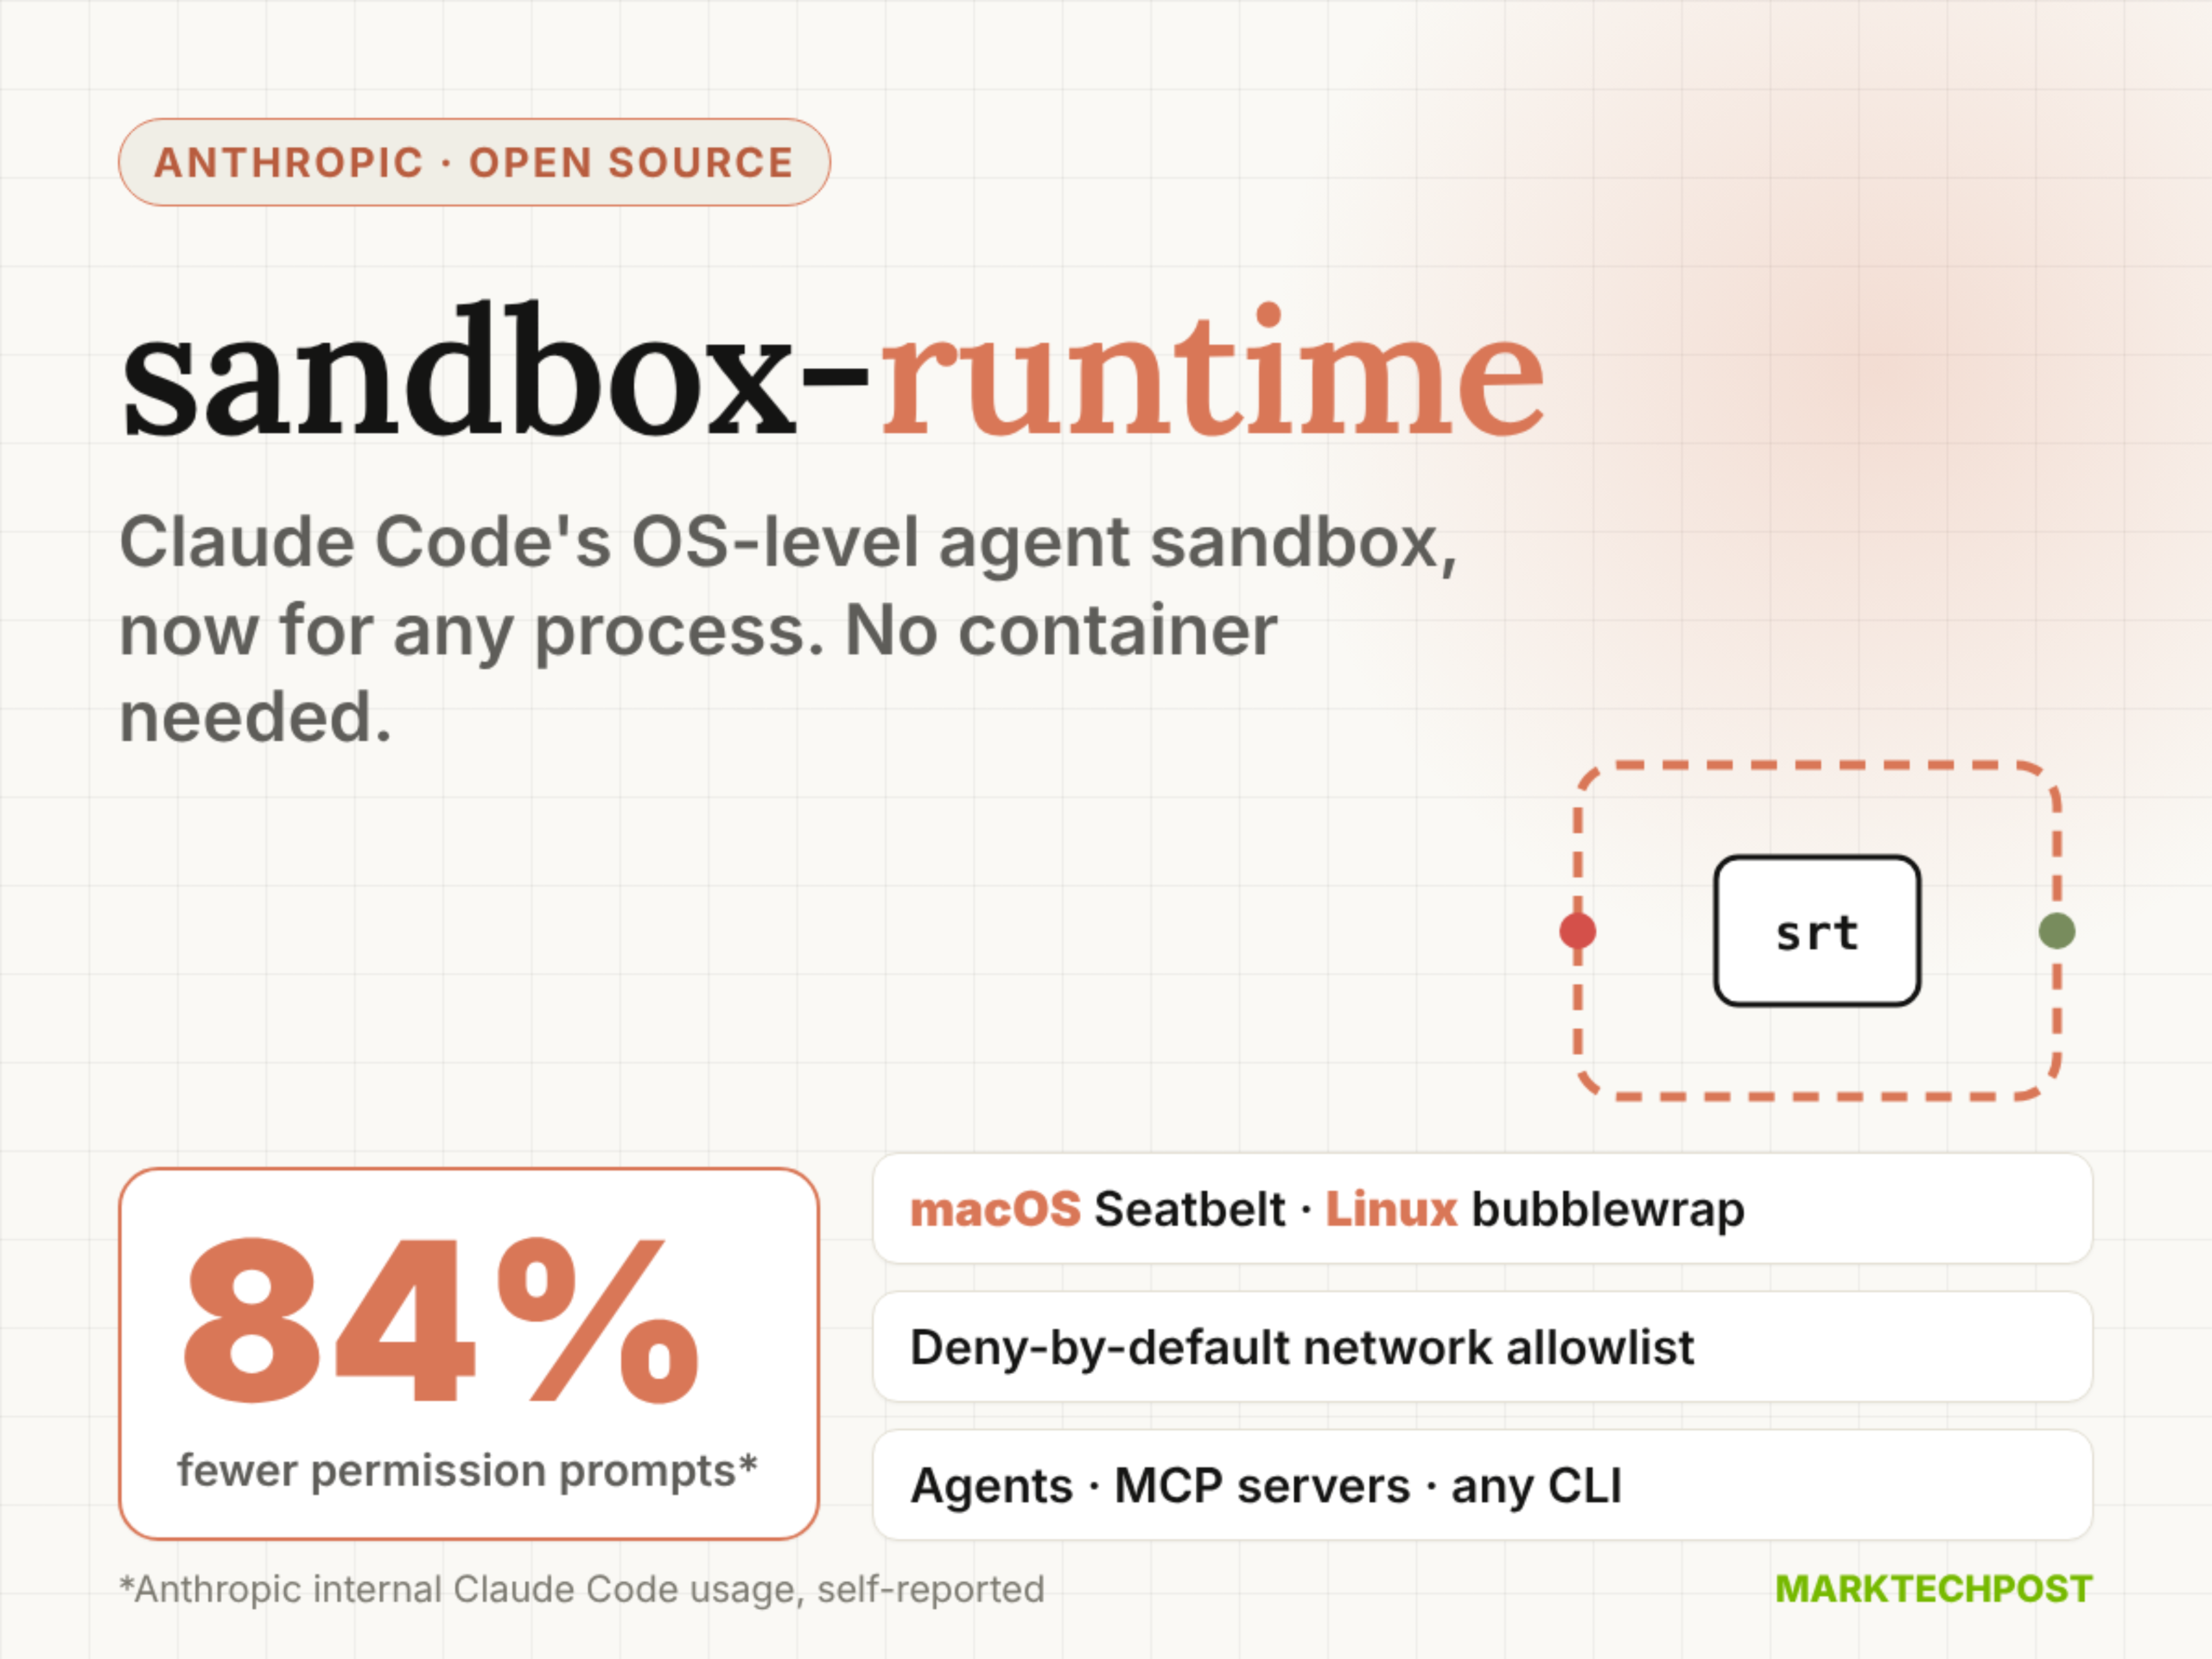
On October 24, 2026, Anthropic open-sourced sandbox-runtime (srt), an OS-level sandboxing tool that operates without containers, designed to restrict file read/write and network access permissions for AI agents, MCP servers, and CLI tools. It supports macOS (Seatbelt), Linux (bubblewrap), and Windows (alpha), with npm package version 0.0.81 under the Apache-2.0 license.

Meet Anthropic’s sandbox-runtime: OS-Level Sandboxing for AI Agents, No Containers

Why it matters:This tool represents a significant advancement in AI security infrastructure—achieving fine-grained, full-process-tree coverage through the operating system’s native isolation mechanisms, directly addressing the risks of prompt injection and privilege escalation, and has already been deployed for internal validation within Claude Code.

Timeline and related coverage

Letta platform releases a tutorial on building stateful engineering collaborators: supporting core memory, shared state, and portable workflows.

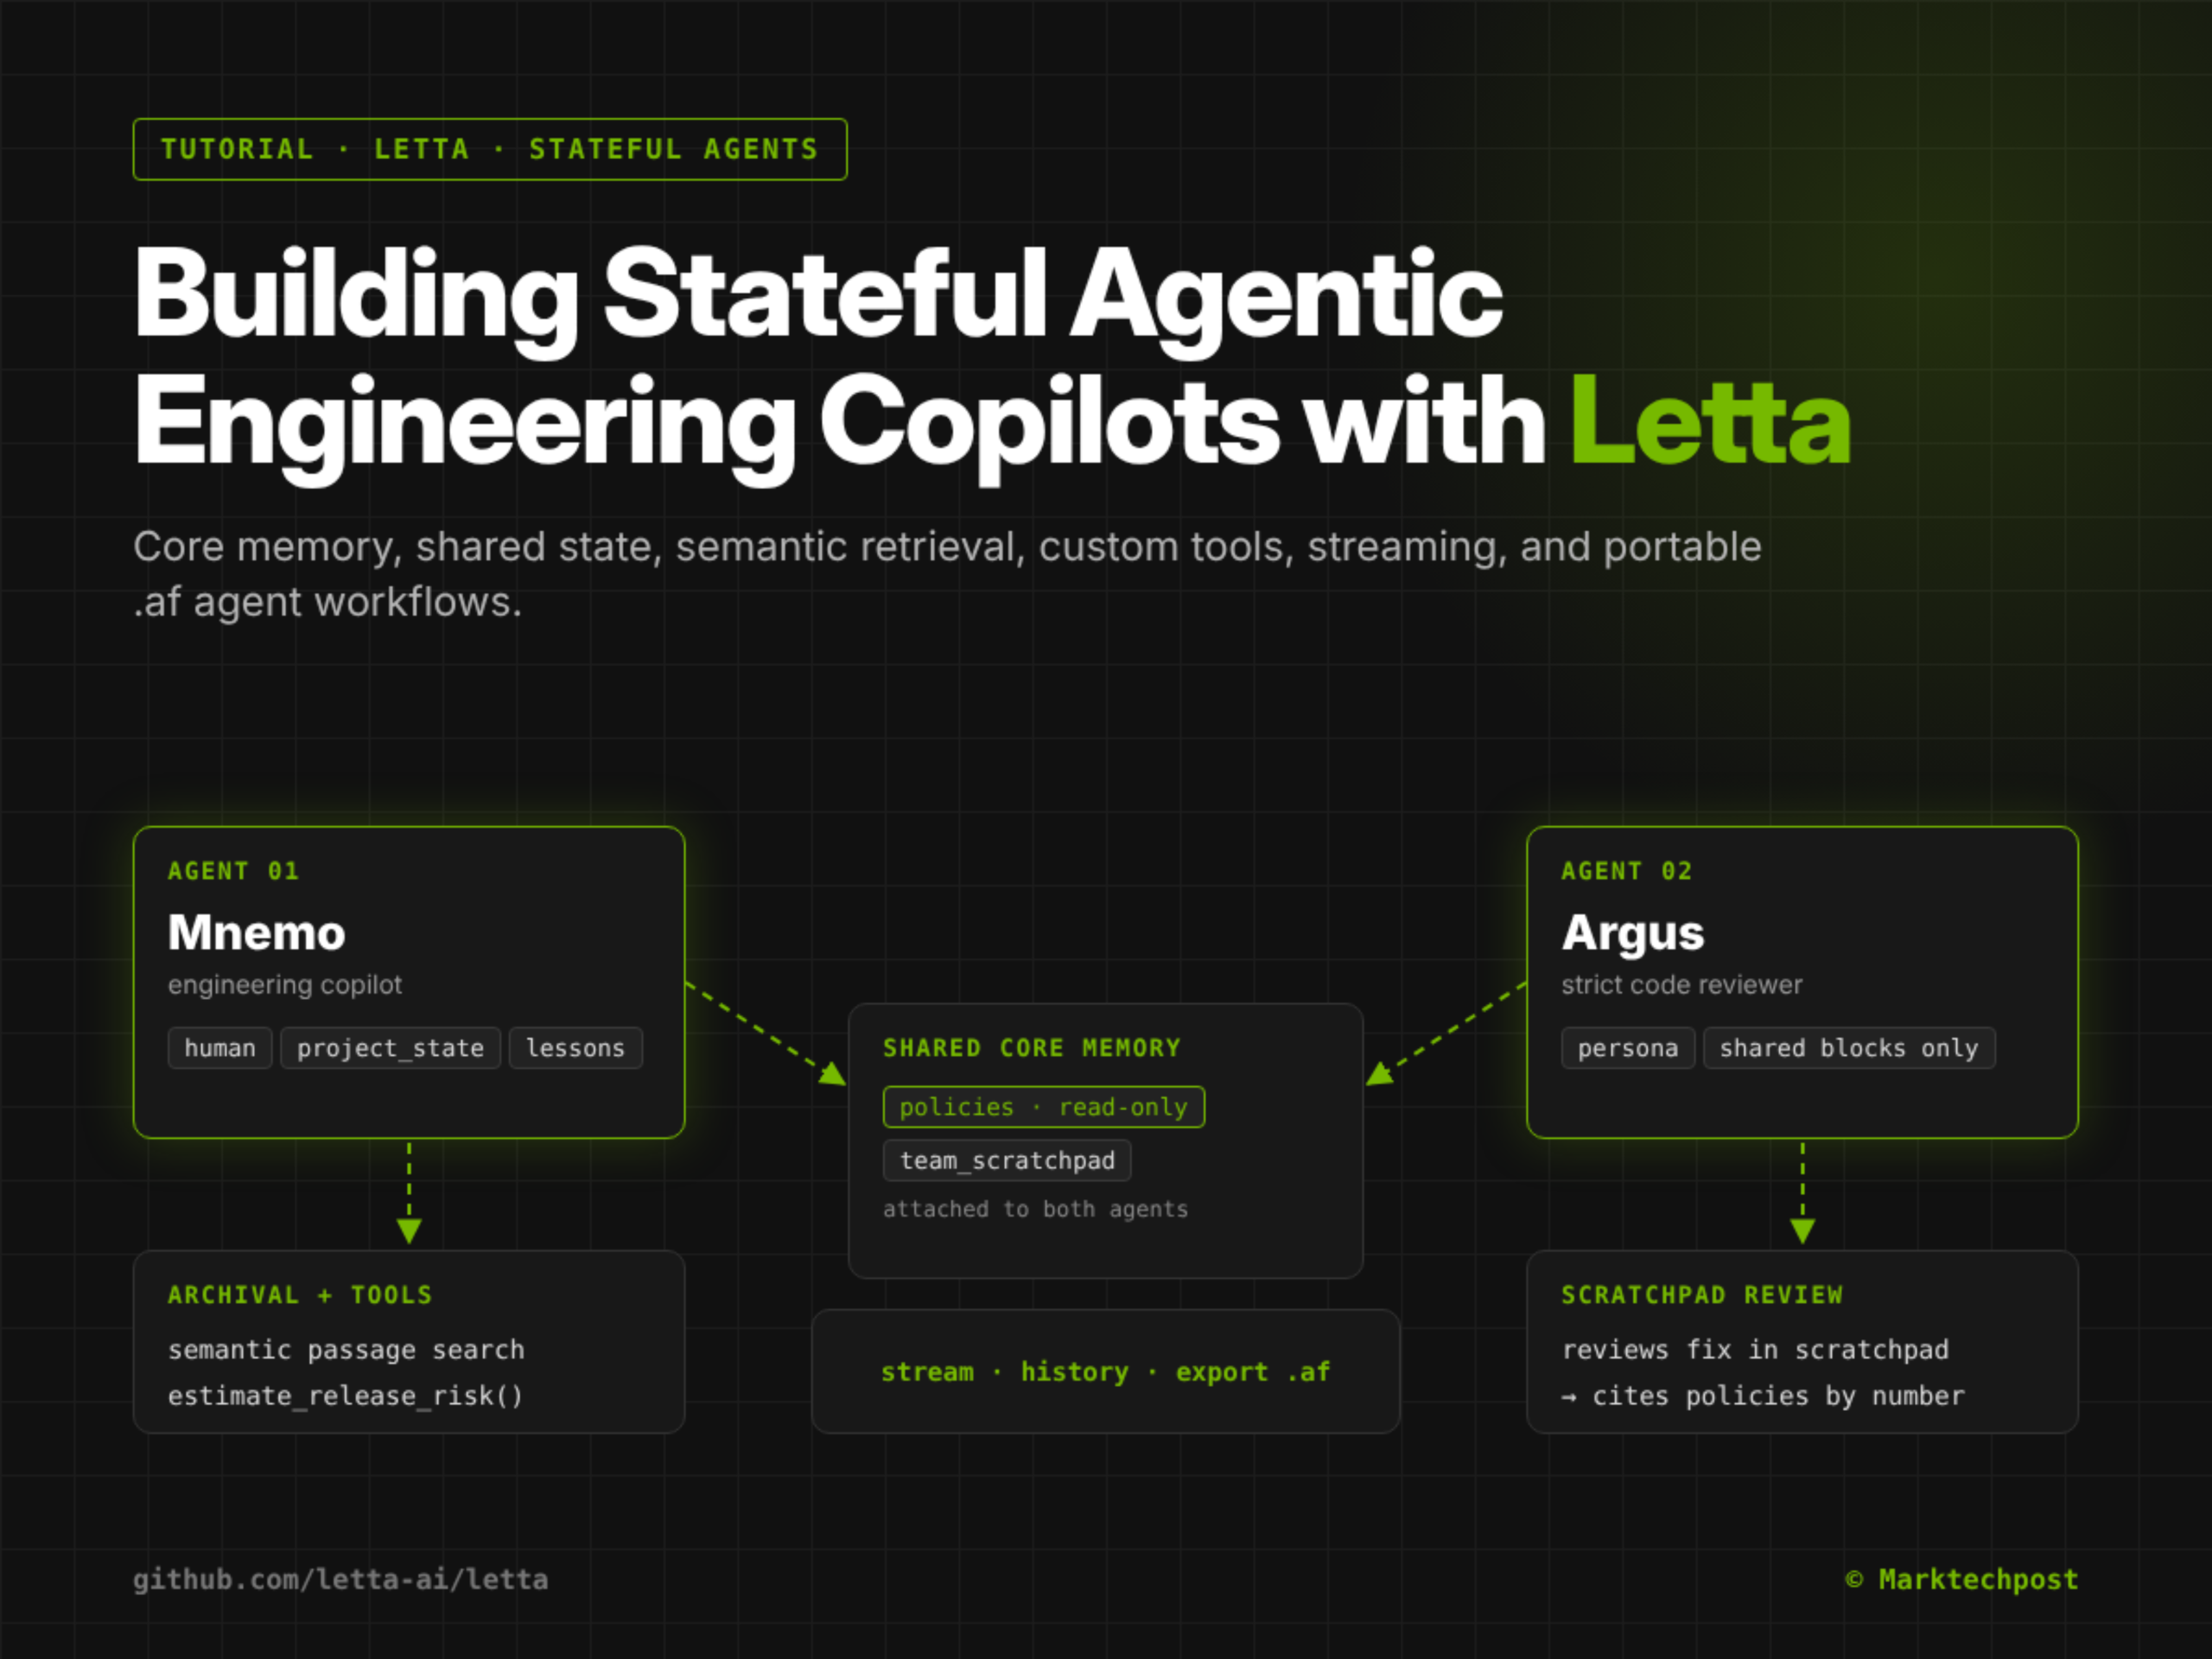
MarkTechPost published a tutorial on October 24, 2026, detailing how to build an agentic copilot with persistent state using the Letta framework. The guide covers capabilities such as verifiable core memory, multi-agent shared memory, semantic retrieval of archived knowledge, custom Python tool integration, streaming responses, and .agent format (.af) export. The content serves as a technical practice guide and does not provide performance metrics, security audits, or production‑environment validation.

Stateful Agentic Engineering Copilots with Letta: Core Memory, Shared State, Semantic Retrieval, Custom Tools, Streaming, and Portable Agent Workflows
Timeline and related coverage

TRIAD Release: The First Multimodal Large Model Evaluation Benchmark for All-Modal Ambiguity Resolution

On October 24, 2026, researchers published the paper arXiv:2610.30841v1 on arXiv, officially introducing the TRIAD benchmark—a new evaluation framework designed to assess the ability of text–image–audio tri-modal systems to resolve cross-modal ambiguities. The benchmark comprises 327 hand-crafted tri-modal samples, spanning 86 scenario groups and 18 categories of cross-modal ambiguity types.

TRIAD: Benchmarking Omni-Modal Ambiguity in Multimodal Large Language Models

Why it matters:This achievement directly addresses a core blind spot in current multimodal large-model evaluations: existing benchmarks focus on perception or reasoning under deterministic, single-modal inputs. In contrast, TRIAD is the first to systematically target “modal-complementary disambiguation” as its evaluation objective. Through rigorously designed leave-one-modal-out counterfactual tests, it reveals critical shortcomings—particularly in audio processing—and highlights weak scene-level robustness, thereby providing a reproducible diagnostic protocol and taxonomy for assessing next-generation all‑modal models.

Timeline and related coverage

TutorCaseBench Released: The First LLM Tutoring Evaluation Benchmark for Special Education Scenarios

On October 24, 2026, researchers published TutorCaseBench on arXiv (ID 2610.30828v1)—an LLM tutoring evaluation benchmark built on real-world cases from pedagogy, educational psychology, and special education, focusing on the ability to support students with learning and behavioral challenges. The benchmark comprises 923 dialogue segments, covering five categories of challenging behaviors, and employs a dual-track assessment approach: open-ended generation (1,560 questions) and multiple-choice questions (2,537 questions). Among 11 state-of-the-art large models, the top performer met the evaluation criteria in only 55.8% of the open-ended items.

TutorCaseBench: A Case-Grounded Benchmark for Evaluating LLM Tutors in Supporting Students with Challenging Behaviors

Why it matters:This study fills a critical gap in existing AI‑based educational assessment, which has overlooked the complexity of students with special needs. Its methodology emphasizes evidence‑based tracing—combining qualitative case studies with source‑grounded rubrics—and all data are openly available, ensuring reproducibility and relevance to educational practice. The findings clearly reveal significant shortcomings of current LLMs in generating contextually appropriate responses, offering important warnings and guidance for the practical implementation of educational AI.

Timeline and related coverage

baseVultra: A novel compact nonlinear recurrent unit for focused candidate generation, outperforming LSTM and GRU in small-scale scenarios.

On October 24, 2026, arXiv published the paper arXiv:2610.30154v1, introducing a novel recurrent neural network unit called baseVultra. This model centralizes dense recurrent computations into a single H×H candidate generation matrix and replaces traditional gating matrices with O(H)-complexity diagonal interactions. Its effectiveness was validated in compact settings such as TinyShakespeare: under a 200K-parameter single-layer configuration, it achieved a validation loss of 1.594, outperforming LSTM (1.604) and GRU (1.616) with the same number of parameters, while its dense computation overhead is only about 54% of that of GRU.

baseVultra: Compact Nonlinear Recurrence with Reallocated Capacity

Why it matters:This study represents a new direction in the design of recurrent neural network architectures—shifting from a gate‑driven approach to a candidate‑generation‑driven one. Experiments span character‑level language modeling (TinyShakespeare, text8) and formal language probes (the Counter task), with results clearly demonstrating that its advantages are most pronounced in compact settings where hidden‑state capacity is limited (e.g., H=16), providing a well‑defined technical positioning supported by empirical evidence.

Timeline and related coverage

Research reveals the local geometric structure of semantic meaning in large language models

A paper published on October 24, 2026, on arXiv (ID 2610.30715v1) characterizes the local geometric properties of semantic meaning in embedding space across four decoder-only large language models—Gemma 4, Llama 3.2, Qwen 2.5, and Pythia—using cross-lingual probes and fine-grained probes.

Meaning Contracts: Local Semantic Geometry in Large Language Models

Why it matters:This study is the first to systematically characterize the invariance, variability, and refinement mechanisms within “the same semantic factor” in LLMs, proposing the “local anisotropic neighborhood” model. The approach has been validated through blind human evaluations, demonstrating rigorous methodology, broad model coverage, and cross-architecture consistency in its findings.

Timeline and related coverage

Clinicians Lead the Development of Verifiable Safety Guidelines: Establishing a Traceable Layer of Safeguards for Mental Health Chatbots

On October 24, 2026, arXiv published the paper arXiv:2610.30690v1, which proposes a four‑rule safety‑check rulebook defined, finalized, and adjudicated under the guidance of two clinical physicians. After formal verification, this rulebook is deployed as a guardrail layer to govern the outputs of large language models (LLMs) in mental health contexts. All judgments within this guardrail can be traced back to a single naming rule and sixteen factual verifications, aiming to enhance the interpretability and testability of safety assessments.

From Clinical Judgment to Checkable Rules: Clinician-Led Guardrails for Mental-Health Chatbots

Why it matters:This study offers a safety‑enhancing approach distinct from mainstream prompt engineering, LLM‑as‑a‑Judge, or Constitutional AI. Its core innovation lies in structuring and formalizing clinical decision‑making while maintaining a complete audit trail throughout the process. All key claims—such as the number of rules, validation methods, factual base, comparative experimental data, and cost metrics—are explicitly stated in the original text, and the publication date (2026‑10‑24) aligns with the current UTC date (2026‑10‑25), ensuring timeliness and a solid foundation of credibility.

Timeline and related coverage

The study proposes an ontology-driven behavioral analysis framework for Bengali-language cyberbullying, ODCBNA.

The paper, published on October 24, 2026, on arXiv (ID 2610.30885v1), proposes an offender-centric analytical framework called ODCBNA, which integrates ontology design, knowledge graph construction, behavior modeling, community analysis, and influence modeling, and conducts empirical analysis based on the Bengali-language cyberbullying corpus BenCoDiC.

From Perpetrators' Digital Footprints to Behavioral Communities: An Ontology-Driven Framework for Bengali Cyberbullying Analysis--- FULL VERSION

Why it matters:The material is an arXiv preprint, published on 2026-10-24—no later than the current date of 2026-10-26—with a clear source and a complete structure. The content focuses on methodological innovation and reproducible analytical results (such as identifying 1,063 perpetrators, detecting six Louvain communities, and ranking feature contributions), meeting the requirements for timeliness and factual accuracy in academic information.

Timeline and related coverage

Researchers have introduced the Japanese fact-checking benchmark JSFactCheckBench, revealing latent shortcomings in large language models’ fact-verification capabilities.

On October 24, 2026, arXiv published the paper arXiv:2610.30504v1, introducing a new Japanese benchmark called JSFactCheckBench. This benchmark is the first to explicitly define three key design elements in fact-checking evaluation—question relevance, judgment criteria, and evidence sources—and encompasses 1,913 statements derived from LLM responses to misleading information on Japanese social media platforms. It also features dual annotations for both factual accuracy and importance, based on pre-selected online sources at a reference point in time.

Rethinking the Evaluation of LLM Fact-Checkers

Why it matters:This study fills a gap in existing LLM fact-checking evaluation benchmarks, which have not explicitly specified assessment criteria. Through structured annotation, it reveals systematic weaknesses in mainstream models regarding direct-response statement verification, long‑ and multi‑source localization, and context sensitivity. Moreover, all findings rely on the benchmark’s transparent documentation of annotation conditions, endowing the work with methodological innovation and empirical value.

Timeline and related coverage

The study proposes a self-assessment reinforcement learning framework, SARL, which enhances the search state-awareness capability of retrieval-augmented large models.

On October 24, 2026, arXiv published the paper arXiv:2610.30435v1, introducing the Self-Assessment Reinforcement Learning (SARL) framework, which aims to address the issue in existing retrieval-augmented large language models where search agents lack the ability to perceive search states.

Self-Assessment Reinforcement Learning for Search-State Awareness in Retrieval-Augmented Large Language Models

Why it matters:This study addresses a critical limitation of retrieval-augmented large language models—namely, their tendency to generate hallucinatory reasoning and prematurely terminate searches when they fail to recognize previously acquired or missing information in complex tasks. It proposes an end-to-end reinforcement learning approach that requires no additional evaluation during testing, achieving significant performance improvements on multi-hop reasoning and deep-research benchmarks.

Timeline and related coverage