
What is MemoAI?
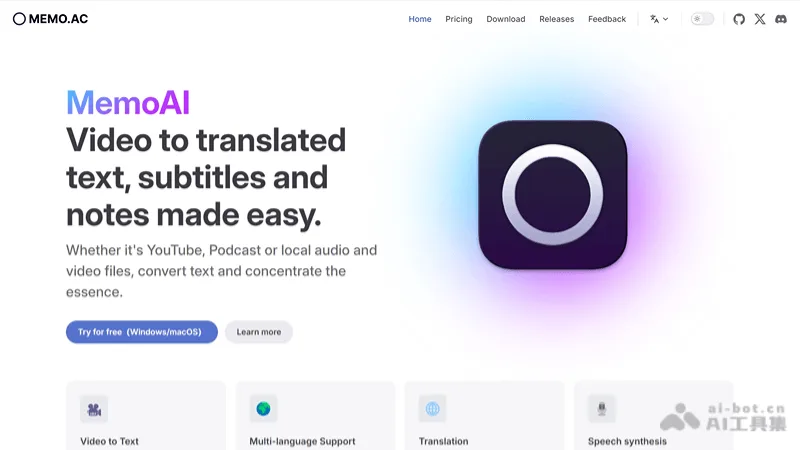
MemoAI is an offline-first intelligent audio-video processing tool designed for Windows and macOS platforms, emphasizing localized AI transcription and translation capabilities. It allows one-click conversion of YouTube videos, podcasts, and local audio/video files (in formats such as MP4, MP3, AAC, M4A) into text; includes built-in translation support for over 90 languages, covering major languages like Chinese, English, and Japanese; and leverages NVIDIA/AMD GPUs and Apple Silicon GPUs for acceleration—for example, GTX-4090 or M1 Max can process 30 minutes of audio/video in just 2 minutes. All processing occurs entirely on the device, with no data uploads, ensuring absolute privacy. Users can try it out through the free Beta program.
Key features
Supports speech-to-text and cross-language translation in Chinese, English, Japanese, and over 90 other languages, with context-aware long-subtitle translation capabilities;
Provides a locally-run speaker diarization feature, suitable for automatically distinguishing roles and structuring multi-person conversations in meetings, interviews, podcasts, and similar contexts.
Use cases and audience
Individual users, content creators, researchers, and business professionals who require efficient handling of audio and video content
- Convert YouTube videos, podcasts, and other audio/video content into written transcripts, extracting key information
- Supports speech transcription and mutual translation in over 90 languages, including Chinese, English, and Japanese.
- Runs locally and offline on multi-person dialogue audio such as meetings, interviews, and podcasts, enabling speaker diarization.
Local audio/video files (MP4, MP3, AAC, M4A, etc.) or YouTube video links
Transcribed text, multilingual translated texts, real-time subtitles, floating key-point notes, AI-generated summaries (requires a personal API key), and export files in SRT/Markdown/Notion formats
Frequently asked questions
Does it support offline use?
Yes. All processing is performed on your local device, with no data uploads—completely offline.
Can you customize AI prompts to optimize summarization performance?
Supported. You can customize AI assistant prompts to achieve personalized responses.
How to use
- 01
Download and install the Memo AI Windows/macOS client.
- 02
Import local audio or video files (MP4, MP3, AAC, M4A, etc.) or paste a YouTube link.
- 03
Select your target language and enable real-time subtitles, floating notes, or AI summarization features.
- 04
Export the results in subtitle (SRT), Markdown, or Notion format.
Pricing and availability
Currently in the free Beta testing phase, available for trial at no cost; official pricing, subscription periods, commercial licensing scope, and usage limits have not yet been announced.
- Pricing source
- https://memo.ac/
- Pricing last updated
- 2026-10-30
Prices and limits may change. Check the official website for current terms.
Official website & sources
Sources
Updated on 2026-10-30