
Skip to content
AI NEWS JOURNAL
AI, IN PERSPECTIVE

Search AI news

Search headlines, summaries and articles to connect the dots.

Newest first

Clinicians Lead the Development of Verifiable Safety Guidelines: Establishing a Traceable Layer of Safeguards for Mental Health Chatbots

On October 24, 2026, arXiv published the paper arXiv:2610.30690v1, which proposes a four‑rule safety‑check rulebook defined, finalized, and adjudicated under the guidance of two clinical physicians. After formal verification, this rulebook is deployed as a guardrail layer to govern the outputs of large language models (LLMs) in mental health contexts. All judgments within this guardrail can be traced back to a single naming rule and sixteen factual verifications, aiming to enhance the interpretability and testability of safety assessments.

From Clinical Judgment to Checkable Rules: Clinician-Led Guardrails for Mental-Health Chatbots

Why it matters:This study offers a safety‑enhancing approach distinct from mainstream prompt engineering, LLM‑as‑a‑Judge, or Constitutional AI. Its core innovation lies in structuring and formalizing clinical decision‑making while maintaining a complete audit trail throughout the process. All key claims—such as the number of rules, validation methods, factual base, comparative experimental data, and cost metrics—are explicitly stated in the original text, and the publication date (2026‑10‑24) aligns with the current UTC date (2026‑10‑25), ensuring timeliness and a solid foundation of credibility.
Timeline and related coverage

SIM-UT: A User Behavior Simulation and Evaluation Framework for Medical Triage Chatbots

Researchers have proposed SIM-UT (Simulation of User Behaviour for Triage), a multi-round, real-user-behavior–based evaluation method designed to identify eco‑valid failure patterns of large language model (LLM)-driven medical triage chatbots in real-world settings within low- and middle-income countries (LMICs).

SIM-UT: A User Simulation based Evaluation Framework for Medical Triage Chatbots

Why it matters:This framework breaks through the limitations of existing single-round, English‑centric evaluations by conducting over 5,000 rounds of multilingual simulated conversations, covering real‑world WhatsApp health programs in India, South Africa, and Kenya. For the first time, it systematically reveals “de‑escalation risk,” a critical failure mode, demonstrating both methodological innovation and significant clinical safety implications.

Timeline and related coverage

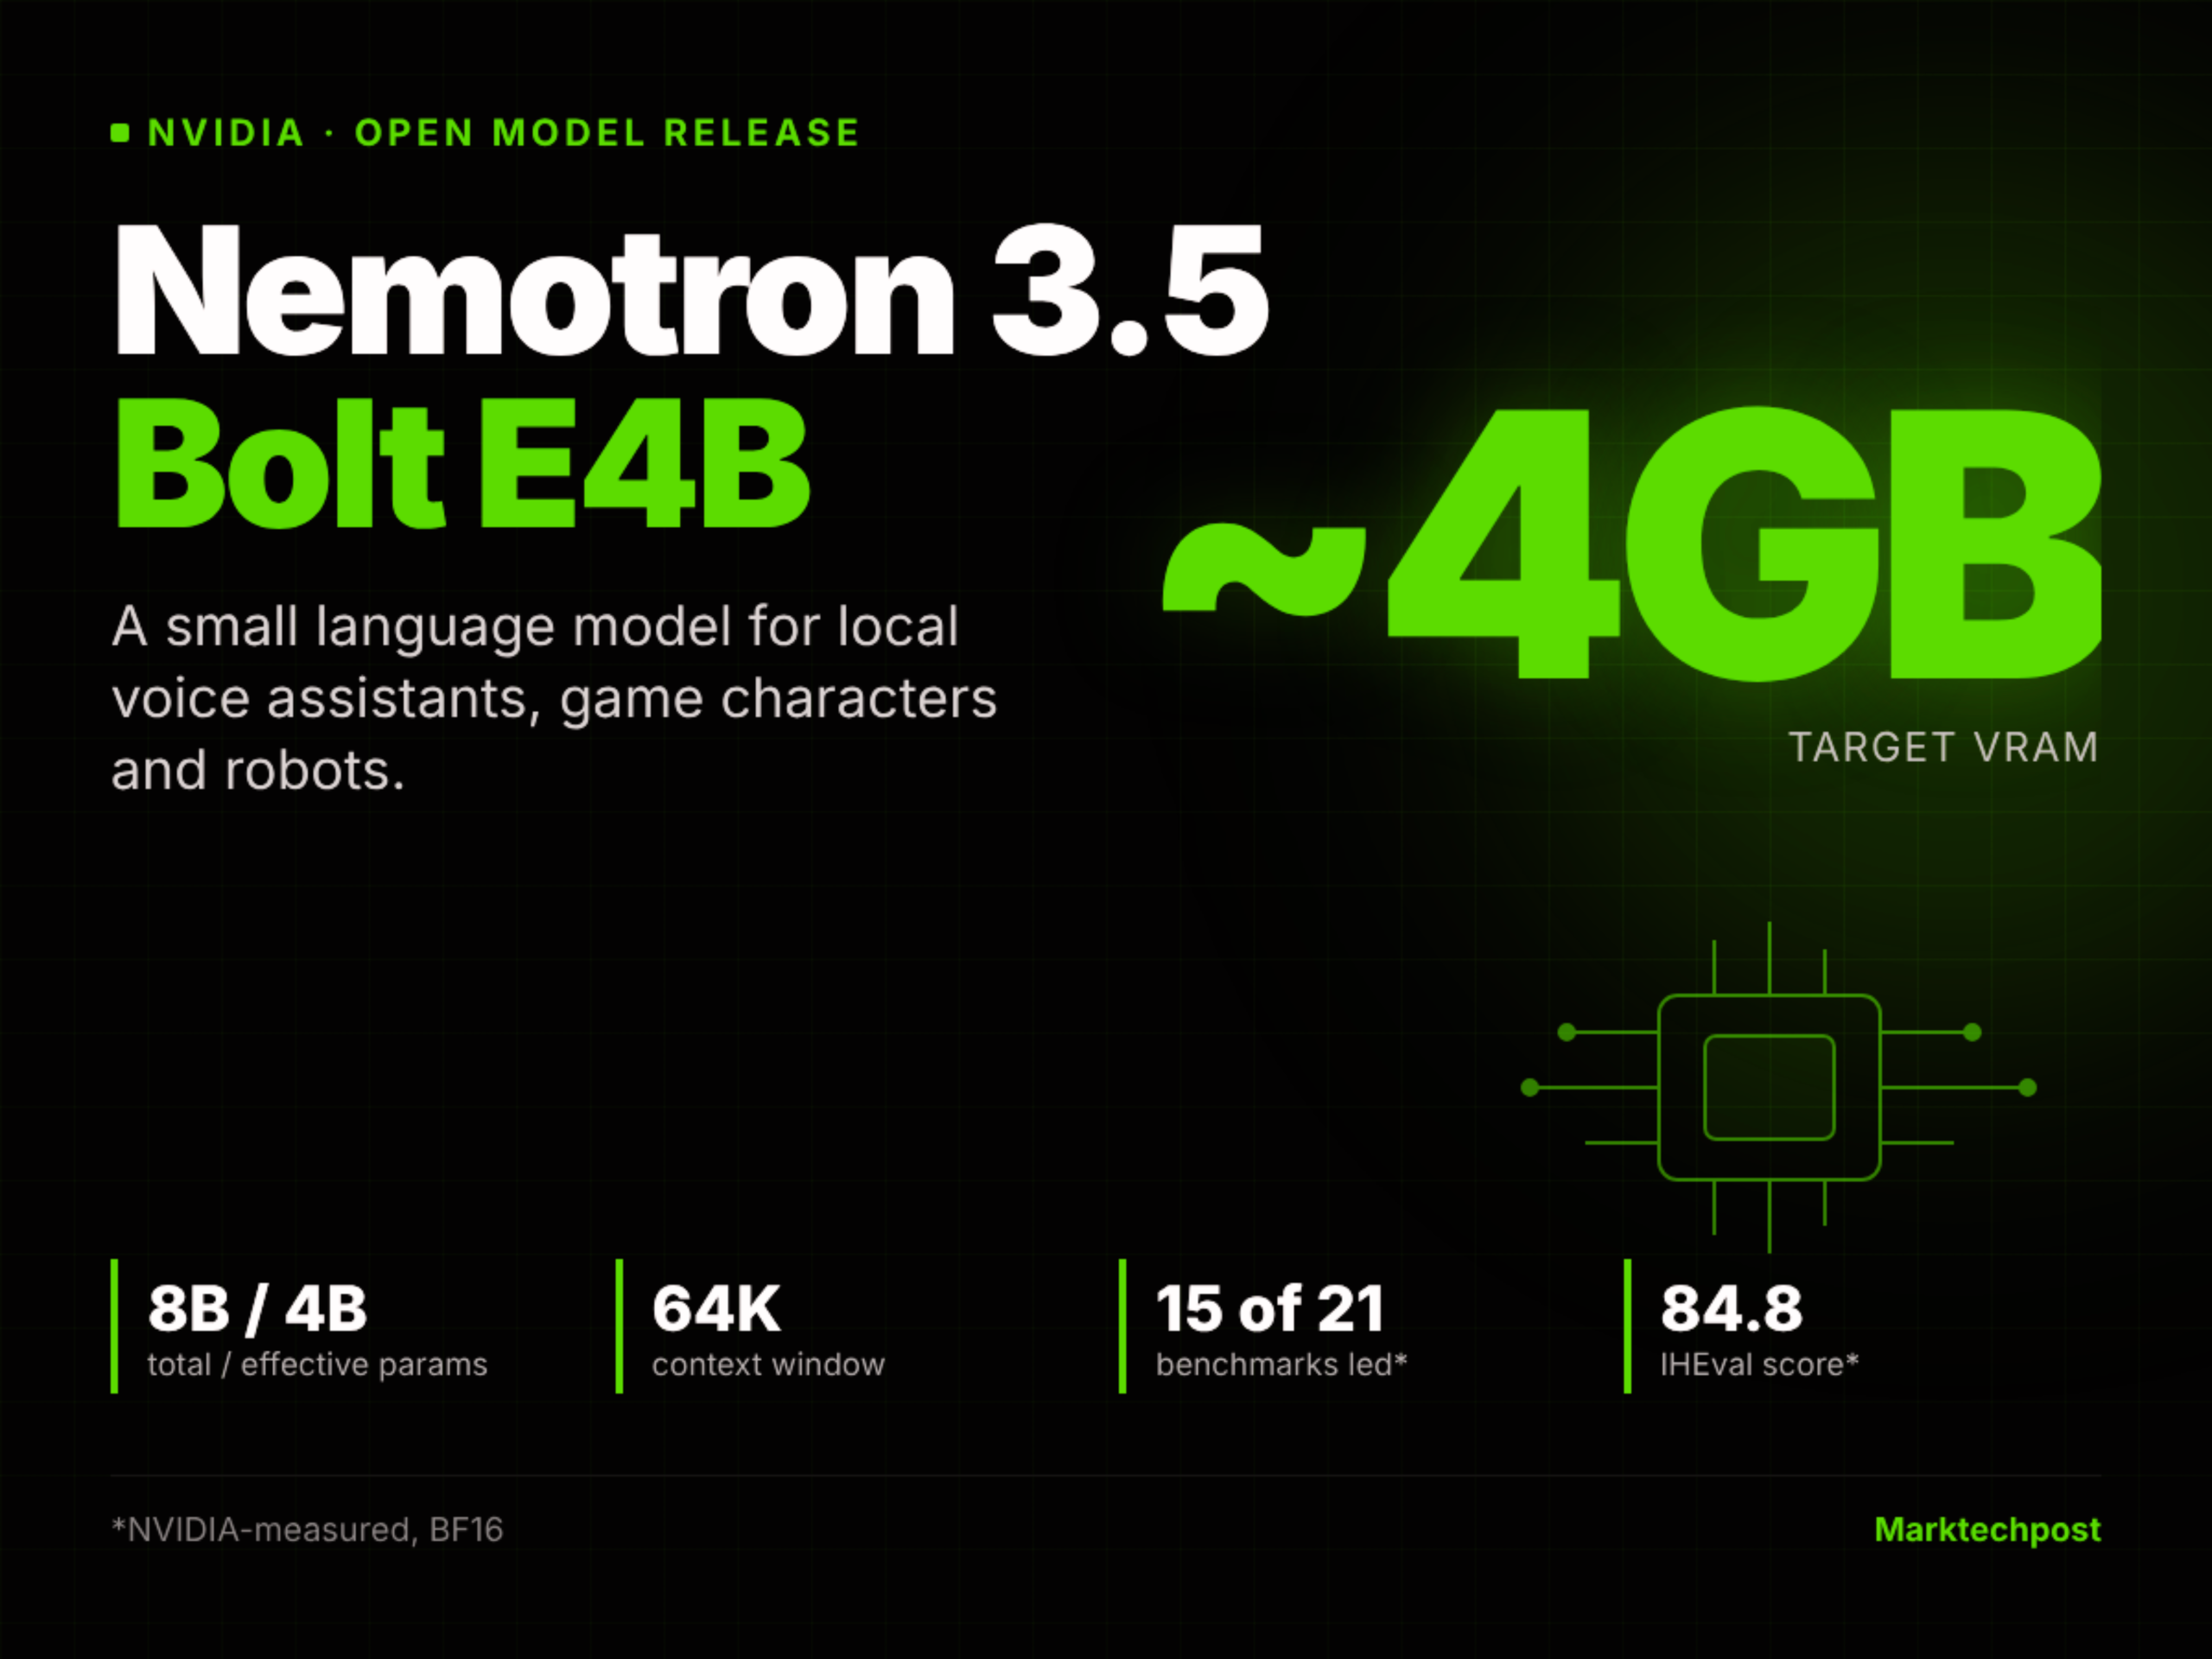
NVIDIA has released the open-source small language model Nemotron 3.5 Bolt E4B 4GB, optimized for on-device voice assistants, game NPCs, and robots.

NVIDIA, leveraging Google’s Gemma 4 E4B model and employing only reinforcement learning (RL) for post-training, has launched Nemotron 3.5 Bolt E4B 4GB—a small open-source language model with 8B total parameters, 4B effective parameters, and a 64K context window. It is designed to run on edge devices such as RTX and Jetson with approximately 4GB of VRAM, supporting multi-turn tool calls and low-latency voice interaction.

NVIDIA Releases Nemotron 3.5 Bolt E4B 4GB: An Open Small Language Model for Local Voice Agents, Game Characters and Robots
Timeline and related coverage