
Skip to content
AI NEWS JOURNAL
AI, IN PERSPECTIVE

Search AI news

Search headlines, summaries and articles to connect the dots.

Newest first

Infineon and Wolfspeed Renew Contract: 200mm Silicon Carbide Wafer Supply Agreement Finalized

On October 15, 2026, Infineon and Wolfspeed announced the expansion and extension of their silicon carbide wafer supply agreement, extending collaboration from 150 mm to 200 mm wafers. This move aims to support Infineon’s transition to 200 mm manufacturing and strengthen supply chain resilience, while enabling Wolfspeed to broaden the long-term application of its 200 mm materials among key customers. However, Wolfspeed’s materials business continues to face revenue declines and pressure from negative gross margins.


英飞凌续约Wolfspeed:200mm碳化硅的“下一关”英飞凌续约Wolfspeed:200mm碳化硅的“下一关”

Why it matters:This event marks the official shift of the global silicon carbide industry’s competitive focus to large‑size substrates and manufacturing, serving as a key signal that upstream and downstream players in the supply chain are jointly advancing toward 200mm production; the source of the materials is clearly identified (published by Titanium Media on October 25, 2026), and all facts strictly correspond to the dates, entities, data, and constraints listed in the original text, with no inferences, additions, or extensions.
Timeline and related coverage

Panel manufacturers are collectively raising prices to cope with upstream cost pressures driven by AI, but downstream acceptance remains low, putting pressure on end-product quality control.

Starting in September 2026, panel manufacturers such as TCL CSOT, BOE, and HKC have issued price‑increase notices one after another. The primary reason is the rapid growth of AI large models, which has led to a sharp surge in demand for HBM, squeezing capacity for mature‑process chips and driving up the prices of key components like driver ICs, PCBs, and glass substrates. Upstream suppliers, including Corning, have also raised their prices in tandem. Despite clear cost pressures, downstream TV and monitor brands have yet to broadly increase purchase prices, while end users continue to report frequent quality‑control issues such as overheating and black spots. As a result, these price hikes have not yet translated into actual sales or improved user experiences.

AI大模型狂飙,面板行业也扛不住了

Why it matters:The materials system reveals the cross‑chain transmission mechanism through which the AI industry impacts indirectly related hardware sectors—rather than driving panel demand directly, it triggers a full‑chain cost repricing via the reallocation of wafer‑fabrication capacity. At the same time, it highlights a significant gap between price‑increase behavior and actual market feedback (price rigidity, declining shipments, and user complaints), underscoring the deep‑seated contradiction between industry bargaining power and product competitiveness.

Timeline and related coverage

Global Experiences That the U.S. Anti-Data-Center Movement Can Learn From: From Ireland’s Grid Crisis to New Zealand’s Community AI Initiatives

In his book “Hyper-Scale,” Paris Marx traces the history of resistance within global data centers, noting that Ireland imposed a ban due to grid capacity saturation, prompting companies to build their own gas-fired power plants; meanwhile, New Zealand is exploring a non-exploitative AI pathway by leveraging local cloud services to support Māori-language speech recognition; and the wave of opposition currently sweeping the United States is, in fact, a reenactment of long‑foreseen global tensions.

Timeline and related coverage

llama.cpp 发布 b11871 版本:新增 JSON 嵌套深度限制以防止服务崩溃

llama.cpp 在 b11871 版本中引入关键安全修复,对请求中 JSON 嵌套层级实施 128 层硬性限制,避免因深度递归解析导致 HTTP 线程栈溢出、服务崩溃(macOS 触发 SIGBUS,Linux 触发 SIGSEGV)。该策略覆盖 chat 接口多类输入场景,并统一返回 HTTP 400 错误。

Why it matters:按信源设置仅收录,不参与自动精选

Timeline and related coverage

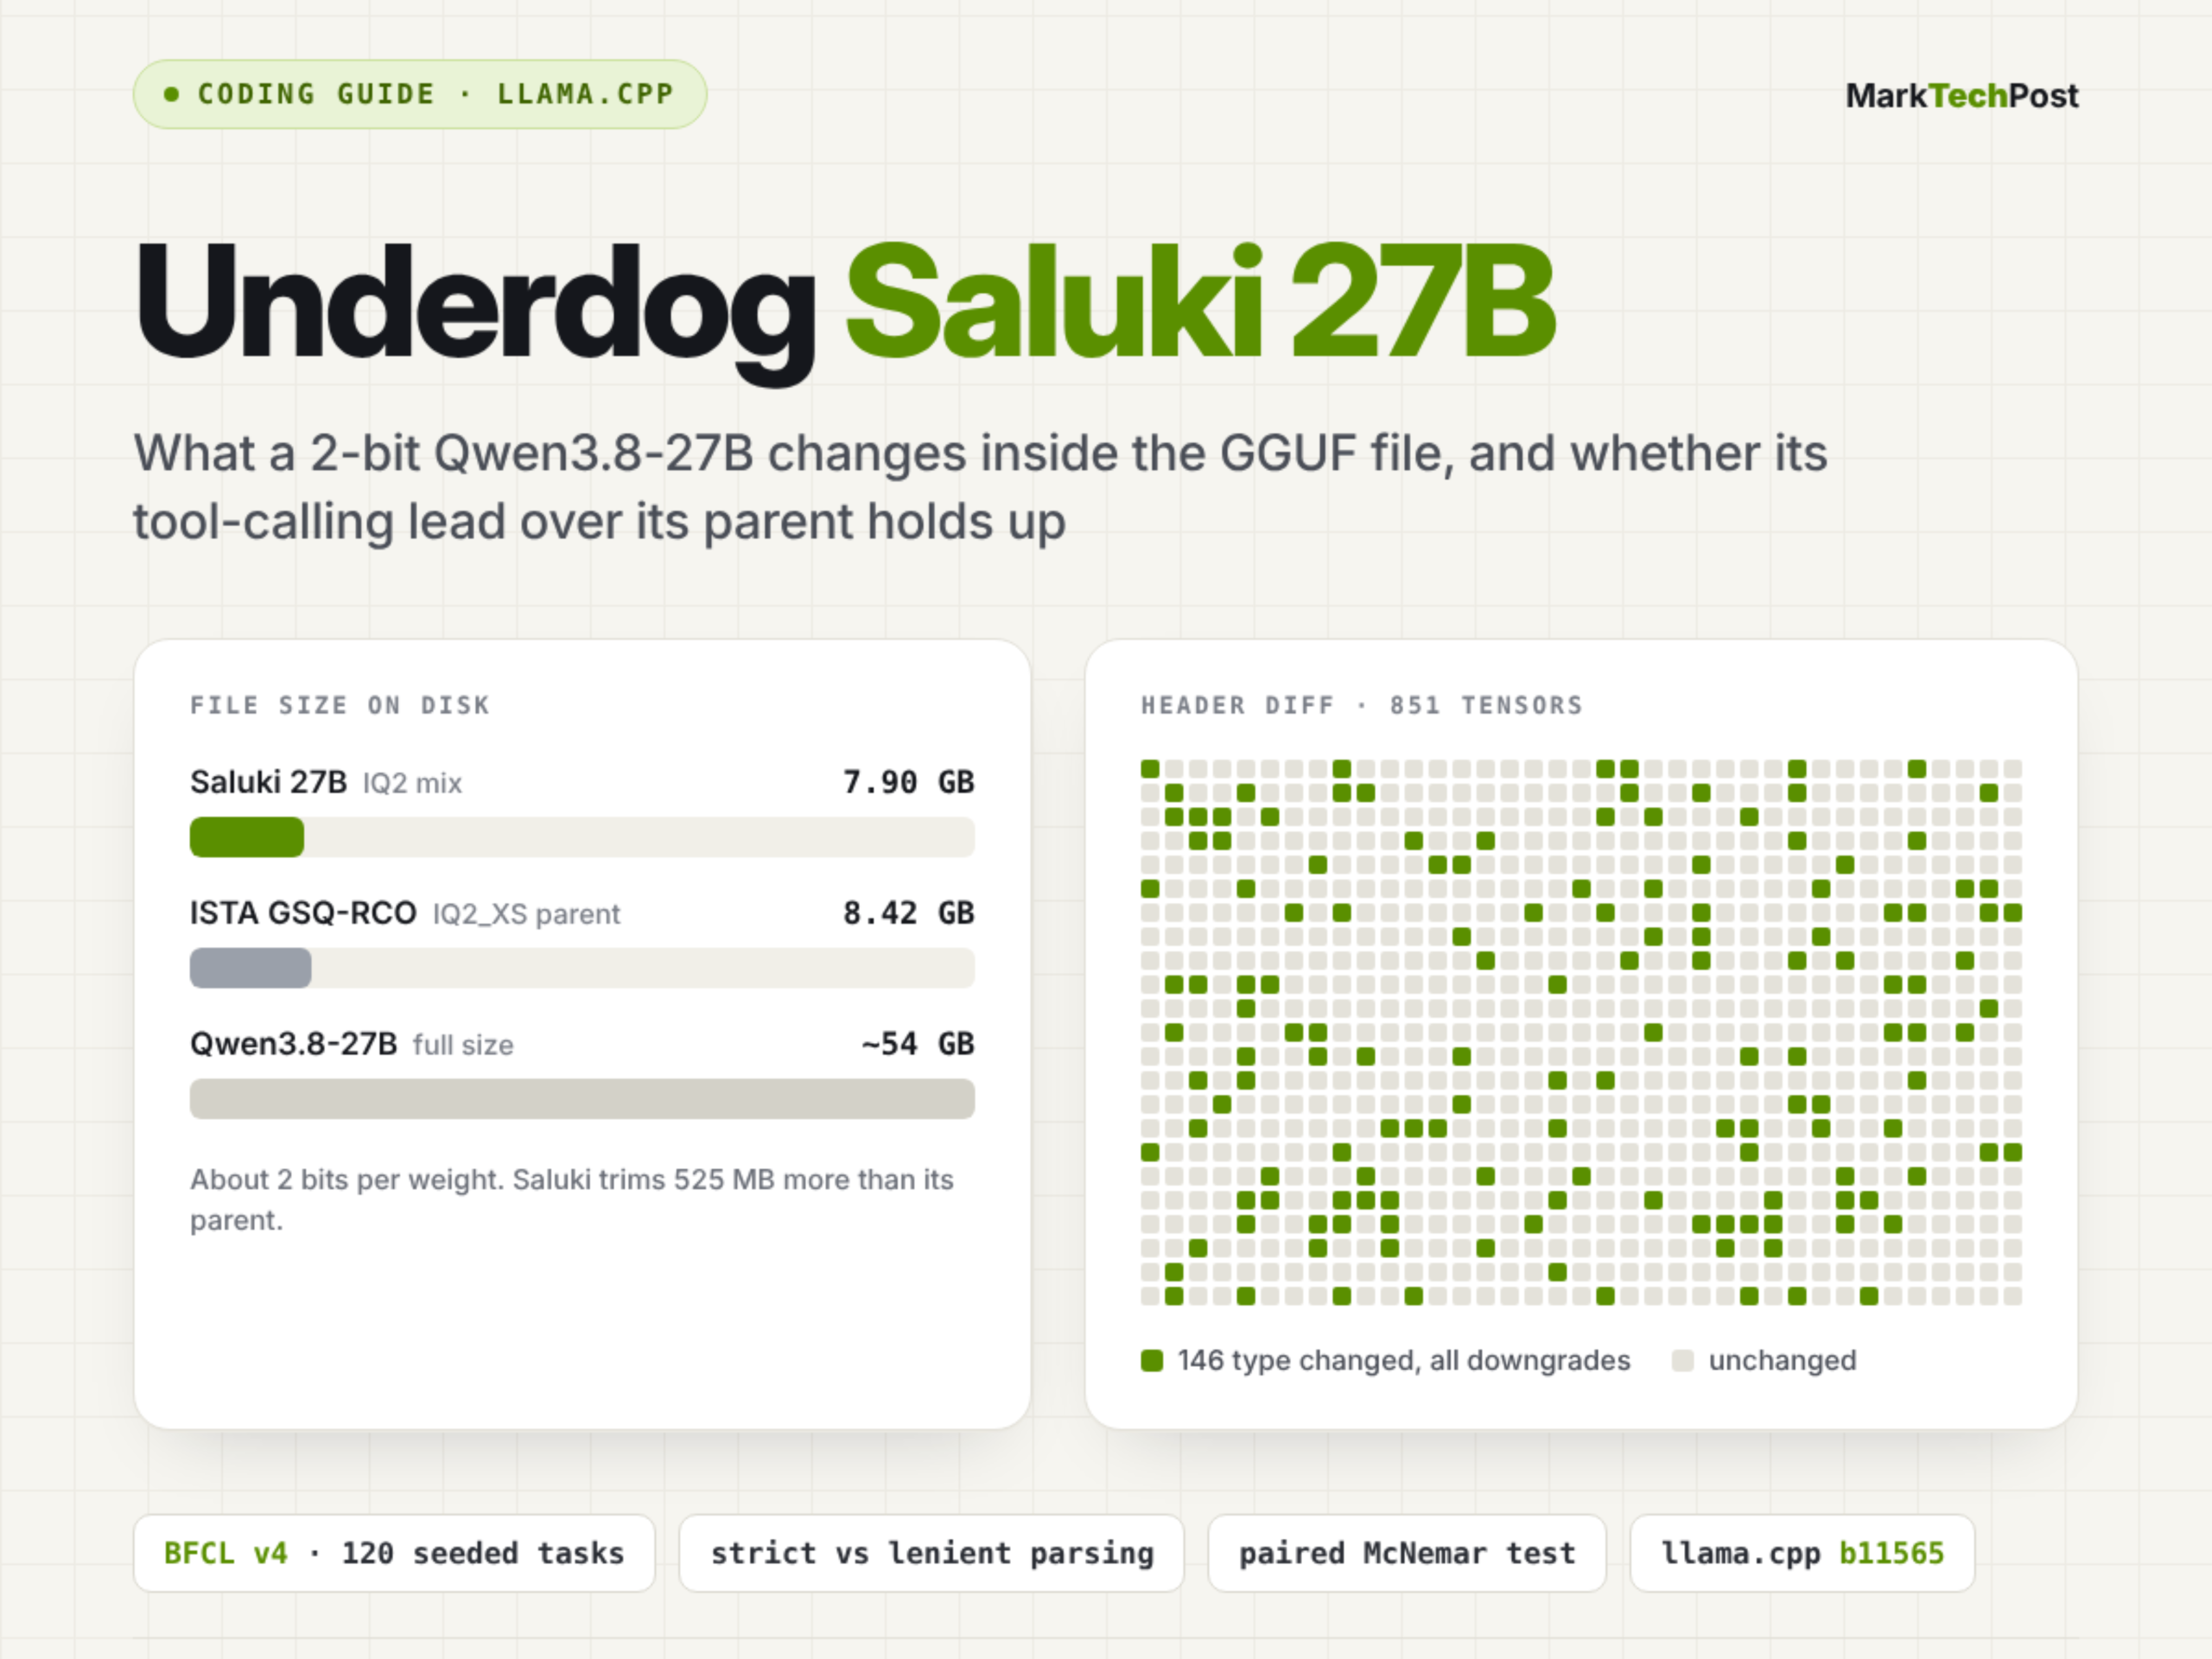
Underdog Saluki 27B: Technical Analysis of the 2-bit Qwen3.8-27B Tool-Calling Model Based on GSQ-RCO

This article introduces Saluki 27B, a model released by Underdog—a 7.9 GB, 2-bit quantized variant of Qwen3.8-27B—built using the GSQ-RCO method from ISTA-DASLab. It claims to outperform the original 54 GB full-precision model on the BFCL v4 benchmark across 120 tasks; however, all performance conclusions are based solely on the developers’ assertions and have not been independently verified.

How to Run Underdog Saluki 27B: 2-Bit Qwen3.8-27B Tool-Calling Guide
Timeline and related coverage

llama.cpp 发布 b11870 版本,正式支持 DeepSeek-V4.1-Flash 模型

llama.cpp 在版本 b11870 中新增对 DeepSeek-V4.1-Flash(deepseek41)模型的支持,并针对其 Engram 架构进行多项底层优化,包括 KV 缓存计算简化、BF16 精度替代 MXFP8、in-graph 行 gather 等;同步提供覆盖 macOS、Linux、Windows、Android、iOS 及 openEuler 的多平台二进制构建。

Why it matters:按信源设置仅收录,不参与自动精选

Timeline and related coverage

llama.cpp 发布 b11868 版本:增强 Hexagon NPU 多核 Flash Attention 支持,覆盖全平台编译构建

llama.cpp v2.45.0(标签 b11868)正式发布,核心更新为 Hexagon 后端引入 KV-head 团队拆分机制以优化多核 HMX Flash Attention 性能,并统一 FA 拆分控制标志;同步提供 macOS、Linux、Windows、Android、iOS 及 openEuler 等全平台二进制包,含 CUDA 12/13、Vulkan、ROCm、OpenVINO、SYCL、Snapdragon(Adreno+Hexagon)等多后端支持。

Why it matters:按信源设置仅收录,不参与自动精选

Timeline and related coverage

llama.cpp 发布 b11867 版本:服务端入口重构,全面支持多平台与异构加速后端

llama.cpp 于 GitHub 正式发布 b11867 版本,核心变更包括服务端(server)入口点重构(PR #31113),新增 server_role 机制;同时提供覆盖 macOS、Linux、Windows、Android、iOS 及 openEuler 的 40+ 预编译二进制包,支持 CPU、CUDA(12.4/12.8/13.4)、Vulkan、ROCm 10.0、OpenVINO、SYCL(FP16/FP32)、Snapdragon(Adreno+Hexagon)等多元硬件后端。

Why it matters:按信源设置仅收录,不参与自动精选

Timeline and related coverage

llama.cpp 发布 b11866 版本:移除 Metal 后端冗余 AMAX 缩放逻辑,精简 MoE 计算路径

llama.cpp v.b11866 移除了 Metal 后端中已过时的 src1 power-of-two AMAX 缩放机制,转而依赖计算图内更精细的 per expert-token amax 缩放,确保 MoE 下投影激活值在 f16 表示范围内;同步删除相关两阶段归约核、F32 精度调度及越界测试用例。

Why it matters:按信源设置仅收录,不参与自动精选

Timeline and related coverage

llama.cpp 发布 b11861 版本:修复 minimax-m3 模型量化缩放张量未传递导致的推理异常

llama.cpp v.b11861 修复了 minimax-m3 模型在 NVFP4/MXFP8 量化下因 scale 张量未注入计算图而导致的权重失真问题,避免‘token soup’与残差淹没;同步提供覆盖 macOS、Linux、Windows、Android、iOS 及 openEuler 的多平台二进制构建。

Why it matters:按信源设置仅收录,不参与自动精选

Timeline and related coverage